Integrate AI with Rails: Day 10 – RAG with PostgreSQL + pgvector – part 1

We’ll move quickly, but this time keep each milestone runnable. Since you already have PostgreSQL and a working Rails 8.1 app, pgvector is a natural fit: it stores vectors alongside normal PostgreSQL data and supports cosine similarity plus exact and approximate nearest-neighbor search. (GitHub)

Step 13A – Install and enable pgvector

1. Check your PostgreSQL version

Run:

psql --version

Then check whether the extension is already installed:

bin/rails dbconsole

Inside PostgreSQL:

SELECT extname, extversion
FROM pg_extension
WHERE extname = 'vector';

If you get a row

For example:

 vector | 0.8.6

you’re ready.

If you get no rows

You need to install the extension on your PostgreSQL installation.

Since you’re on macOS, if PostgreSQL was installed via Homebrew:

brew install pgvector

The pgvector project currently documents Homebrew installation for PostgreSQL 17/18 formulas. (GitHub)

Then restart PostgreSQL if required by your installation:

brew services restart postgresql@14

Use your actual PostgreSQL version if different.

Step 13B – Enable pgvector in Rails

Once PostgreSQL has the extension available, exit psql:

\q

Generate the migration:

bin/rails generate migration EnablePgvector

Open the migration and use:

class EnablePgvector < ActiveRecord::Migration[8.1]
  def change
    enable_extension "vector"
  end
end

Then:

bin/rails db:migrate

Error: PG::UndefinedFile: ERROR: could not open extension control file "/opt/homebrew/share/postgresql@14/extension/vector.control": No such file or director

This error occurs because the pgvector extension is not installed or cannot be found in the directory of your specific Homebrew-managed PostgreSQL 14 installation.

Do:

# 1. Clone the pgvector repository
cd /tmp
git clone --branch v0.8.6 https://github.com/pgvector/pgvector.git
cd pgvector

# 2. Explicitly point to your PostgreSQL 14 pg_config binary
export PG_CONFIG=/opt/homebrew/opt/postgresql@14/bin/pg_config

# 3. Build and install the extension
make
make install # may need sudo

# Verify the Installation: after the installation completes successfully, check if the vector.control file is present in the target directory
ls /opt/homebrew/share/postgresql@14/extension/vector.control

Verify:

➜  ai_assistant git:(main) rails dbconsole
psql (14.17 (Homebrew))
Type "help" for help.

ai_assistant_development=# SELECT extname, extversion
FROM pg_extension
WHERE extname = 'vector';
 extname | extversion
---------+------------
(0 rows)

ai_assistant_development=#
\q
➜  ai_assistant git:(main) ✗ brew services restart postgresql@14
Stopping `postgresql@14`... (might take a while)
==> Successfully stopped `postgresql@14` (label: sh.brew.postgresql@14)
==> Successfully started `postgresql@14` (label: sh.brew.postgresql@14)
➜  ai_assistant git:(main) ✗ rails dbconsole
psql (14.17 (Homebrew))
Type "help" for help.

ai_assistant_development=# SELECT extname, extversion
FROM pg_extension
WHERE extname = 'vector';
 extname | extversion
---------+------------
 vector  | 0.8.6
(1 row)

You should now see vector.

Step 13C – Understand our RAG data model

We’re going to introduce two models:

Document
   │
   └── has_many :document_chunks

A document could be:

Ruby Guide

and chunks might be:

Chunk 1 → Ruby blocks
Chunk 2 → Classes
Chunk 3 → Modules
Chunk 4 → Metaprogramming

Each chunk gets its own embedding:

Chunk text
   ↓
Embedding API
   ↓
[0.021, -0.318, ...]
   ↓
PostgreSQL vector column

We’ll use 1536 dimensions initially, because we’ll use an embedding model that produces 1536-dimensional vectors. The actual dimension must match the embedding model you choose; pgvector requires the declared vector dimension to match stored vectors.

Step 13D – Create Document

Run:

bin/rails g model Document title:string source:string

Then:

bin/rails db:migrate

Open:

app/models/document.rb

Change it to:

class Document < ApplicationRecord
  has_many :document_chunks, dependent: :destroy

  validates :title, presence: true
end

Step 13E – Create DocumentChunk

Generate it:

bin/rails g model DocumentChunk \
  document:references \
  content:text \
  chunk_index:integer

Then don’t migrate yet.

We need to add the vector column manually because Rails’ generator doesn’t know which embedding dimension we want.

Open the generated migration and make it:

class CreateDocumentChunks < ActiveRecord::Migration[8.1]
  def change
    create_table :document_chunks do |t|
      t.references :document, null: false, foreign_key: true
      t.text :content, null: false
      t.integer :chunk_index, null: false
      t.vector :embedding, limit: 1536

      t.timestamps
    end

    add_index(
      :document_chunks,
      [:document_id, :chunk_index],
      unique: true
    )
  end
end

Depending on the pgvector Rails integration available in your environment, t.vector may not be recognized. If that happens, we’ll use:

add_column :document_chunks, :embedding, :vector, limit: 1536

instead.

The underlying PostgreSQL representation is:

embedding vector(1536)

which is the pgvector-native type.

Then:

bin/rails db:migrate

As expected gets the error:

-- create_table(:document_chunks)
bin/rails aborted!
StandardError: An error has occurred, this and all later migrations canceled: (StandardError)

undefined method 'vector' for an instance of ActiveRecord::ConnectionAdapters::PostgreSQL::TableDefinition

Do:

rails g migration addEmbeddingToDocumentChunks

# add
add_column :document_chunks, :embedding, :vector, limit: 1536

# do
rails db:migrate -t

Step 13F – Model association

Open:

app/models/document_chunk.rb

Use:

class DocumentChunk < ApplicationRecord
  belongs_to :document

  validates :content, presence: true
  validates :chunk_index, presence: true
end

Step 13G – Verify the database

Run:

bin/rails dbconsole

Then:

\d document_chunks

You should have:

ai_assistant_development=# \d document_chunks
                                          Table "public.document_chunks"
   Column    |              Type              | Collation | Nullable |                   Default
-------------+--------------------------------+-----------+----------+---------------------------------------------
 id          | bigint                         |           | not null | nextval('document_chunks_id_seq'::regclass)
 document_id | bigint                         |           | not null |
 content     | text                           |           | not null |
 chunk_index | integer                        |           | not null |
 created_at  | timestamp(6) without time zone |           | not null |
 updated_at  | timestamp(6) without time zone |           | not null |
 embedding   | vector                         |           |          |
Indexes:
    "document_chunks_pkey" PRIMARY KEY, btree (id)
    "index_document_chunks_on_document_id" btree (document_id)
    "index_document_chunks_on_document_id_and_chunk_index" UNIQUE, btree (document_id, chunk_index)
Foreign-key constraints:
    "fk_rails_99b41ada32" FOREIGN KEY (document_id) REFERENCES documents(id)

And:

SELECT vector_dims(
  '[1,2,3]'::vector
);

should return:

3

That proves the extension itself is working.

Exit:

\q

Step 13H – Create your first document manually

Before worrying about PDFs, parsers, Sidekiq, etc., let’s prove the RAG data model.

Run:

bin/rails c

Then:

document = Document.create!(
  title: "Ruby Guide",
  source: "manual"
)

Create chunks:

document.document_chunks.create!(
  content: "Ruby blocks are chunks of code passed to methods.",
  chunk_index: 0
)

document.document_chunks.create!(
  content: "Ruby modules allow code to be organized and reused.",
  chunk_index: 1
)

document.document_chunks.create!(
  content: "Ruby classes define objects and their behavior.",
  chunk_index: 2
)

Check:

document.document_chunks.count

Expected:

3

Step 13I – What we’ve built

Our database is now:

documents
----------------
id
title
source

        │
        │ 1 → many
        ▼

document_chunks
----------------
id
document_id
content
chunk_index
embedding

The crucial field is:

embedding

which will eventually contain:

[0.012, -0.883, 0.217, ...]

Int. Checkpoint

You should now be able to explain:

Why don’t we put the embedding on documents?

Because a document is usually too large to embed as one semantic unit.

We split it into chunks and embed each chunk independently:

Document
  ↓
Chunks
  ↓
Embeddings

That lets retrieval find the relevant section instead of returning the entire document.

One important design choice

We’re not adding an HNSW index yet.

An HNSW (Hierarchical Navigable Small World) index is a high-speed graph-based algorithm used to find similar items in large collections of high-dimensional data. It is widely used in vector databases for AI tasks like semantic search and recommendation systems.

pgvector supports exact nearest-neighbor search by default, and approximate indexes such as HNSW and IVFFlat become useful as the dataset grows. HNSW generally offers a strong speed/recall tradeoff but costs more memory and has a slower build.

IVFFlat (Inverted File with Flat compression) is a type of database index used to speed up similarity searches for high-dimensional vectors

For our small learning dataset:

exact search first

Once we have real embeddings and enough data:

HNSW index

We’ll deliberately compare both, which makes a good senior-level discussion.

We’ll create an Ai::EmbeddingService, generate a real embedding through our current provider setup, store it in PostgreSQL, and then perform our first semantic similarity search. That will be the point where we can honestly say we’ve built RAG mechanics rather than just knowing the definition.


to be continued ..

Integrate AI with Rails: Day 9 – implement OpenRouter model fallbacks

We should implement OpenRouter model fallbacks. I have received an email that is pointing to exactly the right mechanism.

The important distinction is:

  • model = primary model
  • models = ordered fallback models
  • OpenRouter tries the models in order when the current one errors
  • With the OpenAI Ruby SDK, OpenRouter’s models extension should be passed through extra_body. (OpenRouter)

Also, our previous openai/gpt-oss-20b:free error is precisely the kind of failure where a fallback chain is useful.

1. Don’t use openrouter/free

Let’s make the model selection explicit.

In Ai::Client:

PRIMARY_MODEL = "openai/gpt-oss-20b:free"
FALLBACK_MODELS = [
"some-other-free-model:free",
"another-free-model:free"
].freeze

However, don’t blindly copy model names from an old tutorial, because OpenRouter’s free catalog changes. Its current model listing shows multiple free models and their availability/status. (OpenRouter)

For this reason, let’s first see what free models are currently available to your account/API.

2. Get the current free models

From your terminal:

curl https://openrouter.ai/api/v1/models

You can filter it on macOS with jq if installed:

➜  ai_assistant git:(main) ✗ curl -s https://openrouter.ai/api/v1/models | \
  jq '.data[] | select(.pricing.prompt == "0" and .pricing.completion == "0") | .id'
"inclusionai/ling-3.0-flash-sante:free"
"inclusionai/ling-3.0-flash-fin:free"
"dots-studio/dots-3-note-preview:free"
"liquid/lfm-2.5-2.6b:free"
"nvidia/nemotron-3.5-lightning:free"
"thinkingmachines/inkling-small:free"
"poolside/laguna-s-2.1:free"
"thinkingmachines/inkling:free"
"poolside/laguna-xs-2.1:free"
"cohere/north-mini-code:free"
"nvidia/nemotron-3.5-content-safety:free"
"nvidia/nemotron-3-ultra-550b-a55b:free"
"minimax/minimax-m3:free"
"nvidia/nemotron-3-nano-omni-30b-a3b-reasoning:free"
"google/gemma-4-26b-a4b-it:free"
"google/gemma-4-31b-it:free"
"google/lyria-3-pro-preview"
"google/lyria-3-clip-preview"
"minimax/minimax-m2.7:free"
"nvidia/nemotron-3-super-120b-a12b:free"
"openrouter/free"

This gives us the currently available zero-price model IDs instead of guessing.

Pick 2–3 general-purpose conversational models.

Avoid things whose purpose is:

moderation
safety classification
reranking
embedding
image generation

Our earlier User Safety: safe response is exactly why.

3. Model fallback implementation

I would not use openrouter/free as our primary model anymore and definitely not nvidia/nemotron-3.5-content-safety, which is why you previously got the safety-classification output.

For our AI Assistant app, let’s use three general-purpose free models and let OpenRouter handle model-level fallback. OpenRouter documents that the models array is tried in order and with the OpenAI SDK it belongs inside extra_body. (OpenRouter)

Our free fallback chain

From the models we actually have available, I’d use:

MODELS = [
  "minimax/minimax-m3:free",
  "google/gemma-4-31b-it:free",
  "nvidia/nemotron-3-super-120b-a12b:free"
].freeze

The reason I’m choosing these is that they’re general instruction/chat models rather than specialized safety, embedding, or multimodal models. We are optimizing for learning reliability, not benchmarking model quality.

I would not use:

nvidia/nemotron-3.5-content-safety:free

because that’s the wrong task.

I would also avoid for this particular chat application:

cohere/north-mini-code:free

because we’re building a general assistant rather than a coding-only assistant.

And we won’t use:

openrouter/free

Change Ai::Client

Let’s simplify the configuration.

class Ai::Client
  MODELS = [
    "minimax/minimax-m3:free",
    "google/gemma-4-31b-it:free",
    "nvidia/nemotron-3-super-120b-a12b:free"
  ].freeze

  BASE_URL = "https://openrouter.ai/api/v1"

  def initialize
    api_key = Rails.application.credentials.dig(
      :openrouter,
      :api_key
    )

    raise "OpenRouter API key is missing" if api_key.blank?

    @client = OpenAI::Client.new(
      api_key: api_key,
      base_url: BASE_URL
    )
  end

  def chat(messages:)
    response = @client.chat.completions.create(
      model: MODELS.first,
      extra_body: {
        models: MODELS.drop(1)
      },
      messages: messages
    )

    {
      content: response.choices.first.message.content,
      model: response.model,
      input_tokens: response.usage&.prompt_tokens,
      output_tokens: response.usage&.completion_tokens
    }
  rescue OpenAI::Errors::RateLimitError => e
    raise Ai::RateLimitError, e.message
  rescue OpenAI::Errors::APITimeoutError => e
    raise Ai::TimeoutError, e.message
  rescue OpenAI::Errors::APIConnectionError => e
    raise Ai::ProviderError, e.message
  rescue OpenAI::Errors::APIStatusError => e
    raise Ai::ProviderError, e.message
  end
end

This produces the equivalent OpenRouter request:

{
  "model": "minimax/minimax-m3:free",
  "models": [
    "google/gemma-4-31b-it:free",
    "nvidia/nemotron-3-super-120b-a12b:free"
  ],
  "messages": [
    {
      "role": "user",
      "content": "Why Node.js as a backend?"
    }
  ]
}

OpenRouter then tries the models in order if the preceding model can’t serve the request. (OpenRouter)

Why model plus models?

This is worth understanding:

model: MODELS.first

is the primary model.

extra_body: {
models: MODELS.drop(1)
}

are the fallbacks.

So:

M3
↓ unavailable
Gemma
↓ unavailable
Nemotron

If the request succeeds using Gemma, response.model tells us which model actually served the request. OpenRouter documents that the response’s model identifies the model used for the successful run. (OpenRouter)

Test it now

Start:

bin/rails c

Then:

client = Ai::Client.new

And:

result = client.chat(
messages: [
{
role: "user",
content: "Why Node.js as a backend?"
}
]
)
=>
{content:
"# Why Node.js as a Backend?\n\nNode.js has become one of the most popular choices for backend development for several compelling reasons:\n\n## 1. **JavaScript Everywhere**\n- Use the same language (JavaScript) on both frontend and backend\n- Easier to share code between client and server\n- Single language for full-stack development reduces context switching\n\n## 2. **Non-Blocking, Event-Driven Architecture**\n- Built on Google's V8 JavaScript engine\n- Handles thousands of concurrent connections with a single thread\n- Ideal for:...skipping...
=>
> puts result[:model]
minimax/minimax-m3:free
=> nil

Then:

puts result[:content]
puts result[:model]

You should now get an actual conversational answer.

Run it several times if you want to observe which model is serving your requests.

And this connects directly to our AiRequest

This is why we built the observability table earlier.

Imagine:

Requested:
minimax/m3
Actual:
google/gemma-4-31b-it

Our admin dashboard should eventually show:

Requested Model minimax/minimax-m3:free
Actual Model google/gemma-4-31b-it:free
Status success

That’s a genuinely useful production metric.

OpenRouter documents that, when using the OpenAI SDK, its models parameter is passed through extra_body. (OpenRouter)

The routing becomes:

                 OpenRouter
                     │
                     ▼
           PRIMARY_MODEL
              /       \
           works      fails
            │           │
            ▼           ▼
          result     FALLBACK 1
                         │
                       fails
                         │
                         ▼
                    FALLBACK 2

OpenRouter says fallback can happen for provider downtime, rate limiting, moderation refusal and context-length errors, among other errors. (OpenRouter)

4. One thing we should NOT do

Don’t implement this:

begin
call_model_a
rescue
call_model_b
rescue
call_model_c
end

unless you have a very specific reason.

OpenRouter already provides model-level failover and doing the fallback manually would mean:

Your Rails app
      ↓
request A
      ↓
failure
      ↓
request B

while OpenRouter can perform this routing itself.

The provider also knows its own availability and provider-level routing state better than our Rails application does.

So:

Let OpenRouter handle model fallback; let Rails handle application-level error handling.

That’s a clean separation of responsibilities. (OpenRouter)


Where we are now

Our AI project has evolved into:

                    AI Rails Assistant
                           │
          ┌────────────────┼────────────────┐
          │                │                │
          ▼                ▼                ▼
      Chat UI             LLM             Admin
          │                │                │
          ▼                ▼                ▼
    Conversations       Ai::Client     Ai Requests
          │                │                │
          └────────────────┼────────────────┘
                           ▼
                       PostgreSQL

And this sets us up perfectly for the next stage.

Next: RAG + pgvector

We’ll start building the actual knowledge system:

PDF / Document
      ↓
Text extraction
      ↓
Chunks
      ↓
Embeddings
      ↓
pgvector
      ↓
Semantic search
      ↓
Relevant context
      ↓
LLM

That will be the biggest AI feature in this application and one of the most valuable things for our preparation.

to be continued..

Integrate AI with Rails: Day 8 – Production Hardening of the AI Integration, add AI Observablility

We have enough practical experience with SSE right now. We don’t need to perfect the transport layer, lets move on to improve our production error handling architecture.

Step 12 – Production Hardening of the AI Integration

We’ll cover this as one compact step:

LLM request
 ├── timeout
 ├── rate limit
 ├── provider error
 ├── invalid response
 ├── logging
 └── token/cost tracking

12.1 Add a custom AI error

Create:

app/services/ai/error.rb
class Ai::Error < StandardError
end

class Ai::ProviderError < Ai::Error
end

class Ai::RateLimitError < Ai::Error
end

class Ai::TimeoutError < Ai::Error
end

This gives our application its own error vocabulary instead of exposing SDK/provider exceptions everywhere.

12.2 Wrap the provider call

In Ai::Client, wrap the API call.

Conceptually:

def chat(messages:)
  response = @client.chat.completions.create(
    model: MODEL,
    messages: messages
  )

  {
    content: response.choices.first.message.content,
    model: response.model,
    input_tokens: response.usage&.prompt_tokens,
    output_tokens: response.usage&.completion_tokens
  }
rescue Faraday::TooManyRequestsError => e
  raise Ai::RateLimitError, e.message
rescue Faraday::TimeoutError => e
  raise Ai::TimeoutError, e.message
rescue Faraday::Error => e
  raise Ai::ProviderError, e.message
end

The exact exception classes can depend on the SDK/version, so inspect the exception raised by your installed openai gem rather than blindly copying provider-specific classes.

The important architecture is:

OpenRouter/SDK error
        ↓
Ai::Client
        ↓
Ai::RateLimitError
Ai::TimeoutError
Ai::ProviderError
        ↓
Rails application

Your controllers don’t need to know OpenRouter’s exception hierarchy.

12.3 Add timeout thinking

Never allow an AI request to hang indefinitely.

A production system should have:

connection timeout
read/request timeout

and then either:

retry

or:

fail gracefully

depending on the failure.

A key int. answer:

Retry transient failures such as timeouts and 429s with bounded exponential backoff, but don’t blindly retry all errors.

12.4 Token tracking

We’re already storing:

input_tokens
output_tokens

in messages.

That gives us an important operational capability:

conversation.messages.sum(:input_tokens)

and:

conversation.messages.sum(:output_tokens)

Now we can answer:

How many tokens did this conversation consume?

Later we can add pricing:

input tokens  × input price
+
output tokens × output price
=
estimated cost

Don’t hard-code provider pricing into the model. Pricing changes.

12.5 Add request timing

For a production AI application, latency is valuable.

In Ai::Client:

started_at = Process.clock_gettime(Process::CLOCK_MONOTONIC)

response = ...

latency_ms =
  ((Process.clock_gettime(Process::CLOCK_MONOTONIC) - started_at) * 1000).round

Then eventually store:

latency_ms

on the message or in a separate AI usage/event table.

This allows:

model
tokens
latency
errors

to be correlated.

12.6 Don’t log prompts blindly

Avoid:

Rails.logger.info(params)

for AI endpoints.

User prompts may contain:

  • PII
  • secrets
  • customer information
  • proprietary company data

Log metadata instead:

conversation_id
model
latency
token counts
error type

rather than dumping the entire conversation into logs.

12.7 Add application-level rate limiting

An expensive AI endpoint should never be unrestricted.

Conceptually:

User
 ↓
Rate limit
 ↓
AI endpoint
 ↓
LLM

For example:

10 requests/minute/user

The exact limit depends on your application.

This protects:

  • cost
  • provider quotas
  • abuse
  • system capacity

12.8 What about retries?

Use something like:

Timeout      → retry
429          → retry with backoff
5xx          → retry with backoff
400          → don't retry
401          → don't retry
invalid input → don't retry

The exact mapping depends on the provider.

A useful int. phrase:

“I distinguish transient failures from permanent failures. For transient failures, I use a bounded number of retries with exponential (delay: 1,2,4,8,16 seconds) backoff.”


Step 13: Add AI Observability with admin Dashboard

Instead of merely saying we support observability, let’s build an actual AI Admin / Observability dashboard into the app. This will make the project much stronger because you can demonstrate that we thought beyond “call the LLM.”

We will track:

AI Request
├── provider
├── model
├── operation
├── status
├── conversation
├── message
├── input tokens
├── output tokens
├── estimated cost
├── latency
├── started/completed timestamps
├── retry count
├── HTTP status
├── error class
├── error message
├── request ID
├── streamed?
└── metadata

And the admin UI will have:

/admin/ai_requests

AI Observability
-------------------------------------------------
Total Requests       127
Successful           119
Failed                 8
Total Input Tokens  45,230
Total Output Tokens 18,921
Avg Latency          2.34 sec
Estimated Cost       $0.00 / N/A
-------------------------------------------------

Recent AI Requests
-------------------------------------------------
Time | Model | Status | Tokens | Latency | Error
-------------------------------------------------
...

Then clicking a request gives the complete details.

Step 12A – Create AiRequest

We’ll call the model AiRequest.

This is not the AI message itself.

Remember:

Message
    ↓
What the user/assistant said

AiRequest
    ↓
What happened while talking to the LLM

That distinction is important.

1. Generate the model

Run:

bin/rails g model AiRequest \
  conversation:references \
  message:references \
  provider:string \
  model:string \
  operation:string \
  status:string \
  input_tokens:integer \
  output_tokens:integer \
  estimated_cost:decimal \
  latency_ms:integer \
  retry_count:integer \
  http_status:integer \
  request_id:string \
  error_class:string \
  error_message:text \
  started_at:datetime \
  completed_at:datetime \
  streamed:boolean \
  metadata:jsonb

You can also use one line:

bin/rails g model AiRequest conversation:references message:references provider:string model:string operation:string status:string input_tokens:integer output_tokens:integer estimated_cost:decimal latency_ms:integer retry_count:integer http_status:integer request_id:string error_class:string error_message:text started_at:datetime completed_at:datetime streamed:boolean metadata:jsonb

Step 12B – Migration

Open the generated migration.

Change it to:

class CreateAiRequests < ActiveRecord::Migration[8.1]
  def change
    create_table :ai_requests do |t|
      t.references :conversation, null: true, foreign_key: true
      t.references :message, null: true, foreign_key: true

      t.string :provider, null: false
      t.string :model, null: false
      t.string :operation, null: false
      t.string :status, null: false

      t.integer :input_tokens
      t.integer :output_tokens

      t.decimal :estimated_cost, precision: 12, scale: 8

      t.integer :latency_ms
      t.integer :retry_count, null: false, default: 0
      t.integer :http_status

      t.string :request_id

      t.string :error_class
      t.text :error_message

      t.datetime :started_at
      t.datetime :completed_at

      t.boolean :streamed, null: false, default: false

      t.jsonb :metadata, null: false, default: {}

      t.timestamps
    end

    add_index :ai_requests, :status
    add_index :ai_requests, :provider
    add_index :ai_requests, :model
    add_index :ai_requests, :created_at
    add_index :ai_requests, :request_id, unique: true
  end
end

Why are conversation and message nullable?

Because not every AI operation has to belong to a chat message.

Later we might have:

AI embedding request
AI summarization
AI classification
AI agent tool call

So:

conversation_id = NULL
message_id = NULL

can still be valid.

Step 12C – Run migration

bin/rails db:migrate

Then verify:

bin/rails dbconsole
\d ai_requests

Step 12D – Create the model

Open:

app/models/ai_request.rb

Use:

class AiRequest < ApplicationRecord
  belongs_to :conversation, optional: true
  belongs_to :message, optional: true

  enum :status, {
    pending: "pending",
    success: "success",
    failed: "failed",
    rate_limited: "rate_limited",
    timeout: "timeout"
  }, validate: true

  validates :provider, :model, :operation, :status, presence: true

  scope :recent, -> { order(created_at: :desc) }
  scope :successful, -> { where(status: :success) }
  scope :failed_requests, -> { where.not(status: :success) }

  def duration_seconds
    return unless latency_ms

    latency_ms / 1000.0
  end

  def total_tokens
    input_tokens.to_i + output_tokens.to_i
  end
end

Step 12E – Add reverse associations

Open:

app/models/conversation.rb

Add:

has_many :ai_requests, dependent: :nullify

So:

class Conversation < ApplicationRecord
  has_many :messages, dependent: :destroy
  has_many :ai_requests, dependent: :nullify
end

And in:

app/models/message.rb

add:

has_many :ai_requests, dependent: :nullify

So:

class Message < ApplicationRecord
  belongs_to :conversation

  has_many :ai_requests, dependent: :nullify

  enum :role, {
    user: "user",
    assistant: "assistant",
    system: "system"
  }, validate: true
end

Step 12F – Why AiRequest instead of putting everything in Message?

This is an important architectural decision.

A message answers:

What was said?

An AI request answers:

What happened while generating it?

For example:

Message
--------------------
role: assistant
content: "Ruby is..."

while:

AiRequest
--------------------
provider: openrouter
model: ...
status: success
input_tokens: 240
output_tokens: 120
latency_ms: 1840
retry_count: 0
http_status: 200

This separation is much cleaner.

Step 12G – Generate the Admin Controller

Run:

bin/rails g controller Admin::AiRequests index show

This creates:

app/controllers/admin/ai_requests_controller.rb

app/views/admin/ai_requests/index.html.erb
app/views/admin/ai_requests/show.html.erb

Step 12H – Admin routes

Open:

config/routes.rb

Add:

namespace :admin do
  resources :ai_requests, only: %i[index show]
end

So your routes become something like:

Rails.application.routes.draw do
  resources :conversations, only: [:create, :show] do
    resources :messages, only: [:create]
  end

  namespace :admin do
    resources :ai_requests, only: %i[index show]
  end

  root "conversations#new"
end

Check:

bin/rails routes | grep ai_requests

You should get:

/admin/ai_requests
/admin/ai_requests/:id

Step 12I – Admin Controller

Open:

app/controllers/admin/ai_requests_controller.rb

Use:

class Admin::AiRequestsController < ApplicationController
  before_action :authenticate_admin!

  def index
    @ai_requests = AiRequest
      .includes(:conversation, :message)
      .recent
      .limit(100)

    @total_requests = AiRequest.count

    @successful_requests =
      AiRequest.successful.count

    @failed_requests =
      AiRequest.failed_requests.count

    @total_input_tokens =
      AiRequest.sum(:input_tokens)

    @total_output_tokens =
      AiRequest.sum(:output_tokens)

    @average_latency =
      AiRequest.where.not(latency_ms: nil).average(:latency_ms)

    @estimated_cost =
      AiRequest.sum(:estimated_cost)
  end

  def show
    @ai_request = AiRequest.includes(
      :conversation,
      :message
    ).find(params[:id])
  end

  private

  def authenticate_admin!
    authenticate_or_request_with_http_basic("AI Admin") do |username, password|
      username == Rails.application.credentials.dig(:admin, :username) &&
        password == Rails.application.credentials.dig(:admin, :password)
    end
  end
end

This means the admin dashboard isn’t publicly accessible.

Step 12J – Configure Admin Credentials

Run:

bin/rails credentials:edit

Add:

admin:
username: admin
password: CHANGE_ME

Obviously use a proper password locally.

Then:

bin/rails c

Verify:

Rails.application.credentials.dig(:admin, :username)

and:

Rails.application.credentials.dig(:admin, :password)

Step 12K – Admin Index View

Open:

app/views/admin/ai_requests/index.html.erb

Use:

<h1>AI Observability</h1>

<section>
  <h2>Summary</h2>

  <dl>
    <dt>Total Requests</dt>
    <dd><%= @total_requests %></dd>

    <dt>Successful</dt>
    <dd><%= @successful_requests %></dd>

    <dt>Failed</dt>
    <dd><%= @failed_requests %></dd>

    <dt>Input Tokens</dt>
    <dd><%= number_with_delimiter(@total_input_tokens) %></dd>

    <dt>Output Tokens</dt>
    <dd><%= number_with_delimiter(@total_output_tokens) %></dd>

    <dt>Average Latency</dt>
    <dd>
      <%= @average_latency ? "#{@average_latency.round} ms" : "N/A" %>
    </dd>

    <dt>Estimated Cost</dt>
    <dd>
      <%= @estimated_cost ? number_to_currency(@estimated_cost) : "N/A" %>
    </dd>
  </dl>
</section>

<hr>

<h2>Recent Requests</h2>

<table>
  <thead>
    <tr>
      <th>ID</th>
      <th>Time</th>
      <th>Provider</th>
      <th>Model</th>
      <th>Operation</th>
      <th>Status</th>
      <th>Tokens</th>
      <th>Latency</th>
      <th>Retries</th>
      <th>HTTP</th>
    </tr>
  </thead>

  <tbody>
    <% @ai_requests.each do |request| %>
      <tr>
        <td>
          <%= link_to request.id,
              admin_ai_request_path(request) %>
        </td>

        <td>
          <%= request.created_at.strftime("%Y-%m-%d %H:%M:%S") %>
        </td>

        <td><%= request.provider %></td>

        <td><%= request.model %></td>

        <td><%= request.operation %></td>

        <td><%= request.status %></td>

        <td><%= number_with_delimiter(request.total_tokens) %></td>

        <td>
          <%= request.latency_ms ? "#{request.latency_ms} ms" : "N/A" %>
        </td>

        <td><%= request.retry_count %></td>

        <td><%= request.http_status || "N/A" %></td>
      </tr>
    <% end %>
  </tbody>
</table>

Step 12L – Request Detail View

Open:

app/views/admin/ai_requests/show.html.erb

Use:

<h1>AI Request #<%= @ai_request.id %></h1>

<p>
  <%= link_to "← Back to AI Requests",
      admin_ai_requests_path %>
</p>

<table>
  <tbody>
    <tr>
      <th>Provider</th>
      <td><%= @ai_request.provider %></td>
    </tr>

    <tr>
      <th>Model</th>
      <td><%= @ai_request.model %></td>
    </tr>

    <tr>
      <th>Operation</th>
      <td><%= @ai_request.operation %></td>
    </tr>

    <tr>
      <th>Status</th>
      <td><%= @ai_request.status %></td>
    </tr>

    <tr>
      <th>Streamed</th>
      <td><%= @ai_request.streamed? ? "Yes" : "No" %></td>
    </tr>

    <tr>
      <th>Input Tokens</th>
      <td><%= @ai_request.input_tokens || "N/A" %></td>
    </tr>

    <tr>
      <th>Output Tokens</th>
      <td><%= @ai_request.output_tokens || "N/A" %></td>
    </tr>

    <tr>
      <th>Total Tokens</th>
      <td><%= @ai_request.total_tokens %></td>
    </tr>

    <tr>
      <th>Estimated Cost</th>
      <td>
        <%= @ai_request.estimated_cost || "N/A" %>
      </td>
    </tr>

    <tr>
      <th>Latency</th>
      <td>
        <%= @ai_request.latency_ms ?
            "#{@ai_request.latency_ms} ms" :
            "N/A" %>
      </td>
    </tr>

    <tr>
      <th>Retries</th>
      <td><%= @ai_request.retry_count %></td>
    </tr>

    <tr>
      <th>HTTP Status</th>
      <td><%= @ai_request.http_status || "N/A" %></td>
    </tr>

    <tr>
      <th>Request ID</th>
      <td><%= @ai_request.request_id || "N/A" %></td>
    </tr>

    <tr>
      <th>Started At</th>
      <td><%= @ai_request.started_at || "N/A" %></td>
    </tr>

    <tr>
      <th>Completed At</th>
      <td><%= @ai_request.completed_at || "N/A" %></td>
    </tr>

    <tr>
      <th>Conversation</th>
      <td>
        <% if @ai_request.conversation %>
          <%= link_to(
            "##{@ai_request.conversation.id}",
            conversation_path(@ai_request.conversation)
          ) %>
        <% else %>
          N/A
        <% end %>
      </td>
    </tr>

    <tr>
      <th>Message</th>
      <td>
        <%= @ai_request.message_id || "N/A" %>
      </td>
    </tr>

    <tr>
      <th>Error Class</th>
      <td><%= @ai_request.error_class || "N/A" %></td>
    </tr>

    <tr>
      <th>Error Message</th>
      <td>
        <pre><%= @ai_request.error_message || "N/A" %></pre>
      </td>
    </tr>

    <tr>
      <th>Metadata</th>
      <td>
        <pre><%= JSON.pretty_generate(@ai_request.metadata) %></pre>
      </td>
    </tr>
  </tbody>
</table>

Step 12M – Create some test data

Before wiring the real AI request into this table, let’s verify the admin UI independently.

Run:

bin/rails c

Create:

AiRequest.create!(
  provider: "openrouter",
  model: "openrouter/free",
  operation: "chat",
  status: :success,
  input_tokens: 120,
  output_tokens: 80,
  latency_ms: 1530,
  retry_count: 0,
  http_status: 200,
  request_id: SecureRandom.uuid,
  started_at: 2.seconds.ago,
  completed_at: Time.current,
  streamed: true
)

Then open:

http://localhost:3000/admin/ai_requests

Browser authentication should ask for:

Username:
Password:

Use your configured admin credentials.

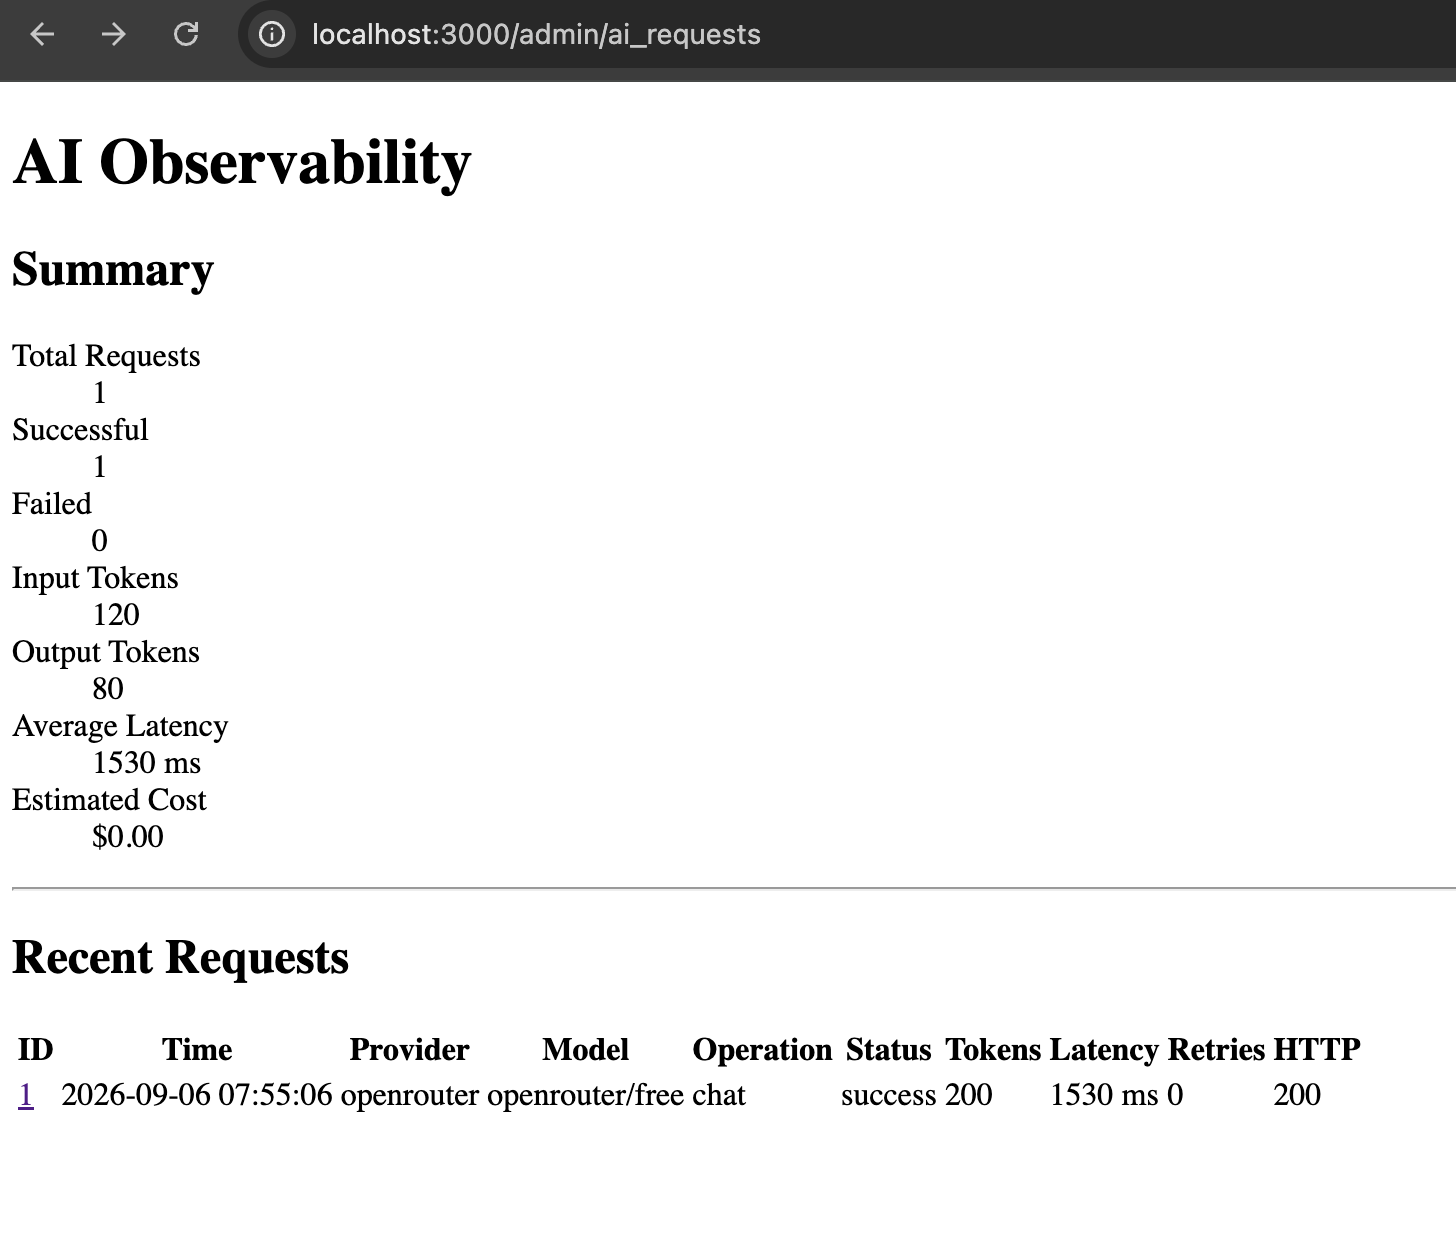
You should see:

AI Observability

Total Requests      1
Successful          1
Failed              0
Input Tokens        120
Output Tokens        80
Average Latency    1530 ms

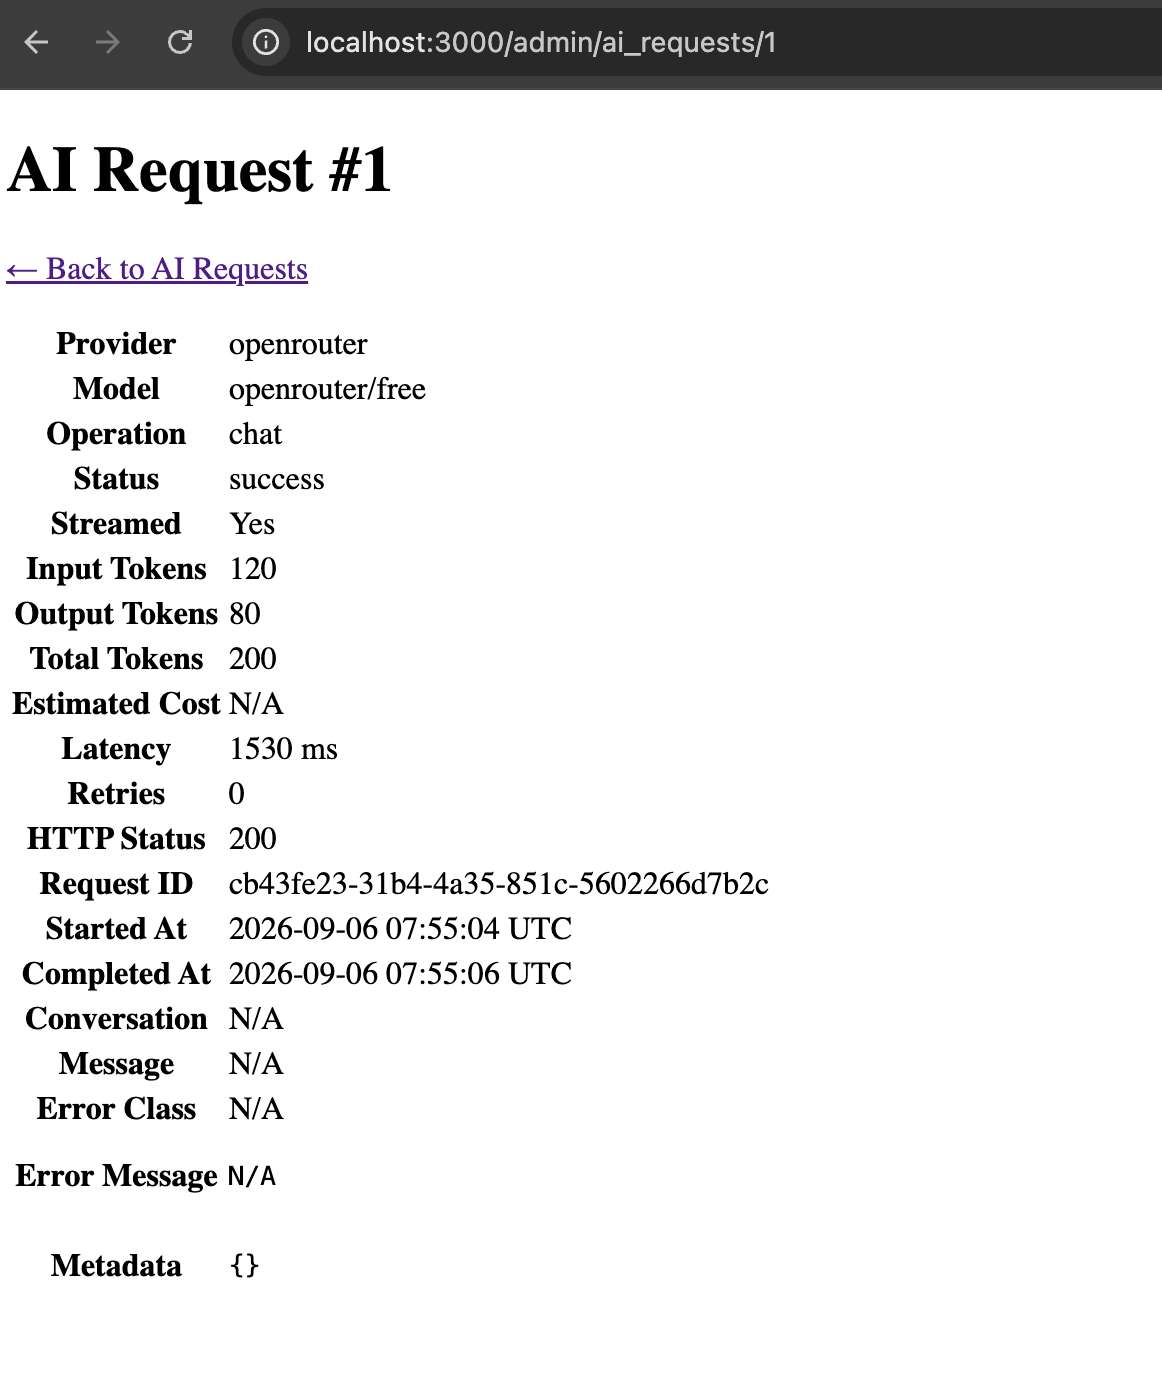
Click the request ID and you’ll see the complete details.

Step 12N – Now connect this to the real AI request

This is the important part.

We don’t want:

AI request
nothing stored

We want:

ChatService
     ↓
AiRequest.pending
     ↓
Ai::Client
     ↓
LLM
     ↓
AiRequest.success

Eventually:

                 AiRequest
                    │
       ┌────────────┼─────────────┐
       ▼            ▼             ▼
    Message    Conversation      LLM
       │                          │
       └──────────────┬───────────┘
                      ▼
                Admin Dashboard

We’ll modify Ai::ChatService to create and update the record around the provider call.

For the non-streaming path first, use this structure:

class Ai::ChatService
  def initialize(
    ai_client: Ai::Client.new,
    prompt_builder_class: Ai::PromptBuilder
  )
    @ai_client = ai_client
    @prompt_builder_class = prompt_builder_class
  end

  def call(conversation:, user_message:)
    conversation.transaction do
      user_message_record = conversation.messages.create!(
        role: :user,
        content: user_message
      )

      messages = @prompt_builder_class
        .new(conversation: conversation)
        .build

      ai_request = conversation.ai_requests.create!(
        message: user_message_record,
        provider: "openrouter",
        model: Ai::Client::MODEL,
        operation: "chat",
        status: :pending,
        streamed: false,
        started_at: Time.current,
        request_id: SecureRandom.uuid
      )

      started_at = Process.clock_gettime(Process::CLOCK_MONOTONIC)

      begin
        result = @ai_client.chat(messages: messages)

        latency_ms =
          (
            Process.clock_gettime(Process::CLOCK_MONOTONIC) -
            started_at
          ) * 1000

        assistant_message = conversation.messages.create!(
          role: :assistant,
          content: result[:content],
          model: result[:model],
          input_tokens: result[:input_tokens],
          output_tokens: result[:output_tokens]
        )

        ai_request.update!(
          message: assistant_message,
          status: :success,
          input_tokens: result[:input_tokens],
          output_tokens: result[:output_tokens],
          latency_ms: latency_ms.round,
          completed_at: Time.current,
          http_status: 200
        )

        assistant_message
      rescue => e
        ai_request.update!(
          status: :failed,
          error_class: e.class.name,
          error_message: e.message,
          completed_at: Time.current
        )

        raise
      end
    end
  end
end

One important architecture note

I used:

rescue => e

here only to demonstrate recording unexpected failures.

In the final production version, we’ll distinguish:

timeout
rate limit
provider error
invalid response
unexpected application bug

and map them to the proper AiRequest.status.

That’s coming immediately after this.


Why this dashboard is worth having

You now have a tangible answer to questions like:

How would you monitor an AI application?

You can say:

“I record each AI invocation separately from the conversation message itself. I track provider, model, status, latency, token consumption, retries, HTTP status and error information, then expose that through an internal observability dashboard.”

Then show page:

/admin/ai_requests

That’s much stronger than saying:

“I would use logging.”


One thing I deliberately did NOT add

I don’t recommend storing the complete prompt by default in AiRequest.

Why?

Because prompts can contain:

PII
customer data
confidential company information
secrets

Instead we can later store safe metadata such as:

{
"message_count": 8,
"prompt_tokens": 1200,
"temperature": 0.2
}

and keep sensitive content under the normal conversation access controls.


Issue 1:Fix AI Response: User Safety

Currently when I tested I get the AI Response like:
User Safety: safeResponse Safety: safe

This is a model-selection problem, not a Rails problem.

The response:

User Safety: safeResponse Safety: safe

is characteristic of a content-safety/guardrail model, not a normal conversational model. OpenRouter currently lists Nemotron 3.5 Content Safety (free) as a moderation model whose intended output is exactly safety classifications such as User Safety and Response Safety. (OpenRouter)

Because we’re using:

MODEL = "openrouter/free"

OpenRouter is free to route that request to an available free model. The free-model router is explicitly designed to select among available free models, so you shouldn’t use it when you need a stable application behavior. (OpenRouter)

Fix: choose an actual chat model

For our course, let’s use a specific free conversational model instead of:

MODEL = "openrouter/free"

A good current option is:

MODEL = "openai/gpt-oss-20b:free"

OpenRouter lists free models separately, including general-purpose models; the exact free catalog changes over time.

Change Ai::Client

Open:

app/services/ai/client.rb

Change:

MODEL = "openrouter/free"

to:

MODEL = "openai/gpt-oss-20b:free"

Then test:

bin/rails c
client = Ai::Client.new
result = client.chat(
messages: [
{
role: "user",
content: "Why Node.js as a backend?"
}
]
)
puts result[:content]

We should now get an actual explanatory answer rather than the safety classification.

Why I want a specific model for our project

This is actually a valuable AI engineering lesson.

Current approach

Ai::Client
openrouter/free
??? model

The model can change depending on routing.

Better application architecture

Ai::Client
specific model
predictable behavior

For production systems, model choice should generally be deliberate rather than an accidental consequence of a router.

The openrouter/free router is useful for experimentation, but for our course we’ll use an explicit free model so our behavior stays understandable. OpenRouter itself recommends openrouter/free as a convenient way to sample available free models, which is precisely why it shouldn’t be treated as a fixed model identity.


One more thing: our RAG work needs an embedding model

Don’t use the chat model for embeddings.

We’ll have:

Chat:
openai/gpt-oss-20b:free
Embeddings:
separate embedding model

OpenRouter currently lists free embedding models as well, including NVIDIA’s Nemotron 3 Embed 1B, which is specifically intended for retrieval/RAG. (OpenRouter)

We’ll choose the embedding model separately when we implement Ai::EmbeddingService.

For now

Make this one-line change:

MODEL = "openai/gpt-oss-20b:free"

After that, we’ll continue with Step 13 – generating embeddings and storing the first real vector in document_chunks.


Issue 2: OpenAI::Errors::NotFoundError

Our server Log:

OpenAI::Errors::NotFoundError ({url: "https://openrouter.ai/api/v1/chat/completions", status: 404, body: {error: {message: "This model is unavailable for free. The paid version is available now - use this slug instead: openai/gpt-oss-20b", code: 404}, user_id: ... 

Since we’re using the openai Ruby SDK, our rescue layer should use OpenAI::Errors::*, not Faraday exceptions. The SDK maps HTTP status codes such as 400, 401, 403, 404, 409, 422, 429 and 500+ into its own typed exceptions, and it has separate APIConnectionError / APITimeoutError classes. (https://github.com/openai/openai-ruby/blob/main/lib/openai/errors.rb)

Also, our 404 message tells us something important:

OpenRouter’s current free catalog does include openai/gpt-oss-20b:free, but free endpoints can change availability. (OpenRouter)

Our earlier 404 specifically said that the endpoint was unavailable for free at that moment and suggested the paid slug. Since OpenRouter currently lists the :free variant as free, this looks like provider/availability inconsistency, not that our slug was fundamentally wrong. OpenRouter also notes that free variants are rate-limited and availability can vary. (OpenRouter)

1. Fix the model

Let’s use the explicit free model again:

MODEL = "openai/gpt-oss-20b:free"

OpenRouter currently lists that exact slug as free with zero input/output pricing. (OpenRouter)

If that endpoint temporarily fails, we can switch to another currently listed free model rather than using openrouter/free.

2. Fix Ai::Client error handling

Also change our Ai::Client chat rescues from: Faraday::TooManyRequestsError 
Faraday::TimeoutError 
Faraday::Error 
to: similar to: OpenAI::Errors::NotFoundError etc, 

check: https://github.com/openai/openai-ruby/blob/main/lib/openai/errors.rb

Let’s use the actual SDK error hierarchy.

The important classes are:

OpenAI::Errors::BadRequestError
OpenAI::Errors::AuthenticationError
OpenAI::Errors::PermissionDeniedError
OpenAI::Errors::NotFoundError
OpenAI::Errors::ConflictError
OpenAI::Errors::UnprocessableEntityError
OpenAI::Errors::RateLimitError
OpenAI::Errors::InternalServerError
OpenAI::Errors::APIConnectionError
OpenAI::Errors::APITimeoutError

The current SDK maps HTTP 404 → NotFoundError, 429 → RateLimitError, and 500+ → InternalServerError. (GitHub)

So replace our old Faraday rescues entirely.

app/services/ai/client.rb

Use:

class Ai::Client
  MODEL = "openai/gpt-oss-20b:free"
  BASE_URL = "https://openrouter.ai/api/v1"

  def initialize
    api_key = Rails.application.credentials.dig(:openrouter, :api_key)

    raise "OpenRouter API key is missing" if api_key.blank?

    @client = OpenAI::Client.new(
      api_key: api_key,
      base_url: BASE_URL
    )
  end

  def chat(messages:)
    response = @client.chat.completions.create(
      model: MODEL,
      messages: messages
    )

    {
      content: response.choices.first.message.content,
      model: response.model,
      input_tokens: response.usage&.prompt_tokens,
      output_tokens: response.usage&.completion_tokens
    }
  rescue OpenAI::Errors::RateLimitError => e
    raise Ai::RateLimitError, e.message

  rescue OpenAI::Errors::APITimeoutError => e
    raise Ai::TimeoutError, e.message

  rescue OpenAI::Errors::APIConnectionError => e
    raise Ai::ProviderError, e.message

  rescue OpenAI::Errors::BadRequestError,
          OpenAI::Errors::AuthenticationError,
          OpenAI::Errors::PermissionDeniedError,
          OpenAI::Errors::NotFoundError,
          OpenAI::Errors::ConflictError,
          OpenAI::Errors::UnprocessableEntityError,
          OpenAI::Errors::InternalServerError,
          OpenAI::Errors::APIStatusError => e
    raise Ai::ProviderError, e.message
  end
end

The specific NotFoundError you just encountered will therefore be caught here:

rescue OpenAI::Errors::NotFoundError => e

and converted into our application-level:

Ai::ProviderError

3. Why keep Ai::*Error?

This is the architecture we want:

OpenRouter / OpenAI SDK
          ↓
OpenAI::Errors::NotFoundError
          ↓
      Ai::Client
          ↓
    Ai::ProviderError
          ↓
     ChatService
          ↓
 Rails application

Your Rails code shouldn’t care whether the provider throws:

OpenAI::Errors::NotFoundError

or some completely different exception tomorrow.

That’s precisely why our abstraction exists.

4. But don’t catch everything as ProviderError

There’s an important distinction.

We should not do:

rescue StandardError => e
raise Ai::ProviderError
end

because a programming bug such as:

NoMethodError

would then masquerade as an LLM provider failure.

Keep provider/API exceptions mapped, but let genuine application bugs surface.

5. Our current custom errors are good

We already created:

class Ai::Error < StandardError
end
class Ai::ProviderError < Ai::Error
end
class Ai::RateLimitError < Ai::Error
end
class Ai::TimeoutError < Ai::Error
end

That’s still a good design.

Now the relationship is:

OpenAI::Errors::RateLimitError
Ai::RateLimitError
OpenAI::Errors::APITimeoutError
Ai::TimeoutError
OpenAI::Errors::NotFoundError
Ai::ProviderError

6. Test the actual exception

Since we currently have a 404 issue, this is a useful test.

In Rails console:

bin/rails c

Then, Try the request with the unavailable model if you want to verify the mapping:

client = Ai::Client.new

client.chat(
  messages: [
    {
      role: "user",
      content: "Why Node.js as a backend?"
    }
  ]
)

You should now receive:

Ai::ProviderError

rather than:

OpenAI::Errors::NotFoundError

That proves our abstraction is working.


Happy Rails AI Integration!

Integrate AI with Rails: AI bootcamp for Developers – Day 7 – AI Response Streaming

Now let’s implement streaming. OpenRouter supports Server-Sent Events (SSE) when stream: true, and the current Ruby SDK exposes Chat Completions streaming through stream_raw; its higher-level stream helper is not available in every released SDK version. (OpenRouter)

We’ll keep the implementation practical and compatible with the SDK behavior you’re using.

Step 9 – Stream the AI response

What changes?

Currently:

Browser
  ↓
POST
  ↓
Rails waits for entire LLM response
  ↓
redirect

We want:

Browser
  ↓
POST
  ↓
Rails
  ↓
OpenRouter SSE stream
  ↓
token
token
token
token
  ↓
Browser

SSE is a long-lived HTTP response where the server sends incremental events. OpenRouter explicitly supports this with stream: true.

9.1 First, prove streaming works from Ruby

Before involving Rails, modify Ai::Client temporarily with a method:

def stream_chat(messages:, &on_delta)
  stream = @client.chat.completions.stream_raw(
    model: MODEL,
    messages: messages
  )

  stream.each do |chunk|
    delta = chunk.choices.first&.delta&.content
    on_delta.call(delta) if delta.present?
  end
end

The current SDK’s stream_raw returns an enumerable stream of chat completion chunks. (RubyDoc)

Now from Rails console:

conversation = Conversation.first

messages = Ai::PromptBuilder
  .new(conversation: conversation)
  .build

Then:

Ai::Client.new.stream_chat(messages: messages) do |delta|
  print delta
  $stdout.flush
end

You should see the answer appearing progressively:

Ruby is a programming language...

instead of getting the entire answer at once.

Why $stdout.flush?

Ruby can buffer stdout. Flushing makes each chunk visible immediately in the console.

9.2 Now expose streaming from Rails

Instead of making MessagesController#create wait for the completed response, we’ll create a streaming endpoint.

Open:

config/routes.rb

Add:

resources :conversations, only: [:create, :show] do
  resources :messages, only: [:create]
end

get "/conversations/:conversation_id/messages/stream",
    to: "messages#stream",
    as: :conversation_messages_stream

9.3 Add the streaming controller action

Open:

app/controllers/messages_controller.rb

Add:

include ActionController::Live

and:

def stream
  conversation = Conversation.find(params[:conversation_id])

  response.headers["Content-Type"] = "text/event-stream"
  response.headers["Cache-Control"] = "no-cache"
  response.headers["X-Accel-Buffering"] = "no"

  sse = SSE.new(response.stream)

  messages = Ai::PromptBuilder
    .new(conversation: conversation)
    .build

  content = +""

  begin
    Ai::Client.new.stream_chat(messages: messages) do |delta|
      next if delta.blank?

      content << delta

      sse.write(
        { content: delta },
        event: "message"
      )
    end

    sse.write(
      { done: true },
      event: "done"
    )
  ensure
    sse.close
    response.stream.close
  end
end

But Rails doesn’t provide SSE automatically.

Add:

include ActionController::Live

and use Rails’ ActionController::Live::SSE if available in our Rails 8.1 setup, or otherwise we can use the standard SSE format directly. Rails 8.1’s Live controller infrastructure is the relevant mechanism here.

To avoid another dependency, let’s actually use the raw SSE format ourselves.

Replace the sse.write(...) parts with:

response.stream.write(
  "event: message\n" \
  "data: #{JSON.generate(content: delta)}\n\n"
)

and completion:

response.stream.write(
  "event: done\n" \
  "data: #{JSON.generate(done: true)}\n\n"
)

So the complete action becomes:

include ActionController::Live

def stream
  conversation = Conversation.find(params[:conversation_id])

  response.headers["Content-Type"] = "text/event-stream"
  response.headers["Cache-Control"] = "no-cache"
  response.headers["X-Accel-Buffering"] = "no"

  messages = Ai::PromptBuilder
    .new(conversation: conversation)
    .build

  begin
    Ai::Client.new.stream_chat(messages: messages) do |delta|
      next if delta.blank?

      response.stream.write(
        "event: message\n" \
        "data: #{JSON.generate(content: delta)}\n\n"
      )
    end

    response.stream.write(
      "event: done\n" \
      "data: #{JSON.generate(done: true)}\n\n"
    )
  rescue IOError
    # Browser disconnected.
  ensure
    response.stream.close
  end
end

9.4 What’s happening?

The server sends chunks like:

event: message
data: {"content":"Ruby"}

event: message
data: {"content":" is"}

event: message
data: {"content":" a"}

event: message
data: {"content":" programming"}

That’s SSE.

The browser doesn’t need to wait for the entire LLM response.

9.5 Important limitation

Our current stream action is only streaming the display.

We are not yet persisting the final assistant message.

That’s deliberate.

The next iteration will accumulate:

content << delta

and after the stream finishes:

conversation.messages.create!(
role: :assistant,
content: content,
model: ...,
input_tokens: ...,
output_tokens: ...
)

So we ultimately want:

LLM
stream chunks
Browser
accumulate full response
PostgreSQL

9.6 Browser side

We can consume SSE with JavaScript:

const source = new EventSource(
  `/conversations/${conversationId}/messages/stream`
);

let content = "";

source.addEventListener("message", (event) => {
  const data = JSON.parse(event.data);

  content += data.content;

  document.querySelector("#assistant-response").innerHTML =
    content;
});

source.addEventListener("done", () => {
  source.close();
});

For our application, we’ll eventually use a Stimulus controller rather than inline JavaScript.

9.7 Don’t spend time styling this

Our immediate objective is proving:

LLM → SSE → Browser

Once you can see the response arriving incrementally, we’ve achieved the important part.

9.8 Commit

Once Ruby streaming works:

git add app/services/ai/client.rb
git commit -m "feat: stream LLM responses"
git push

Then we’ll wire the browser properly.


Int. knowledge from this step

You should now be able to explain:

What is SSE?

A persistent HTTP connection where the server pushes events to the client.

Why use it for AI?

Because LLM output naturally arrives incrementally, and streaming improves perceived latency.

Why not Action Cable?

WebSockets are bidirectional; SSE is simpler when the server primarily needs to push generated output to the browser.

Where does the LLM stream end?

At the Rails server, which consumes the provider’s SSE stream and forwards its own stream to the browser.

OpenRouter documents its AI streaming as SSE, while the Ruby SDK provides streaming chat-completion chunks through stream_raw.

Next step

Since ActionController::Live::SSE exists in Rails 8.1, let’s test the controller before committing.

One important point first: don’t test this through bin/rails server with WEBrick. Rails documents that WEBrick buffers responses, so Live streaming won’t behave correctly. Use our normal Puma server instead. (Ruby on Rails Guides)

1. First verify the route

Run:

bin/rails routes | grep stream

You should see our route, something like:

conversation_messages_stream
GET /conversations/:conversation_id/messages/stream

Then get a conversation ID:

bin/rails c
Conversation.last.id

For example:

1

Exit:

exit

2. Test with curl first

This is the easiest way to prove that the Rails endpoint is actually streaming.

Start Rails with Puma:

bin/rails server

Then in another terminal:

curl -N \
  -H "Accept: text/event-stream" \
  http://localhost:3000/conversations/1/messages/stream

Replace 1 with your real conversation ID.

Why -N?

curl -N means:

Don’t buffer the response.

Without it, you may receive everything at once and incorrectly conclude that streaming isn’t working.

3. What you should see

Because we’re using ActionController::Live::SSE, our response should look roughly like:

event: message
data: {"content":"Ruby"}
event: message
data: {"content":" is"}
event: message
data: {"content":" a"}
event: message
data: {"content":" programming"}
event: done
data: {"done":true}

The exact chunks will vary.

The important thing is that the output arrives progressively, not as one giant response at the end.

Rails’ SSE helper formats events and data for the text/event-stream response. (Ruby on Rails API)

4. Very important: our current stream action has a logical problem

Our current endpoint is probably something like:

def stream
  conversation = Conversation.find(params[:conversation_id])

  response.headers["Content-Type"] = "text/event-stream"

  sse = ActionController::Live::SSE.new(response.stream)

  messages = Ai::PromptBuilder
    .new(conversation: conversation)
    .build

  Ai::Client.new.stream_chat(messages: messages) do |delta|
    sse.write({ content: delta }, event: "message")
  end

  sse.write({ done: true }, event: "done")
ensure
  sse.close
end

This can stream the existing conversation, but it doesn’t receive a new user question.

Eventually our endpoint needs something like:

POST /conversations/:id/messages/stream

with:

content=Explain Ruby blocks

Otherwise we’re streaming whatever messages already exist in the conversation.

So for this first test, we’re only proving:

Rails
ActionController::Live
SSE
Browser/curl

We’ll fix the request lifecycle immediately afterward.

5. Test directly from the browser

You can also open the endpoint in Chrome:

http://localhost:3000/conversations/1/messages/stream

But I prefer curl -N for the first test because the browser doesn’t give you a very useful raw view of SSE events.

Rails’ documentation uses essentially this same pattern – writing to response.stream periodically and closing the stream in ensure. (Ruby on Rails Guides)


One architectural correction before we commit

Don’t commit our current streaming implementation yet.

we’ll change the flow to the proper one:

Browser
   │
   │ POST message
   ▼
MessagesController
   │
   ├── save user message
   │
   ▼
LLM streaming
   │
   ├── SSE chunk → Browser
   ├── SSE chunk → Browser
   ├── SSE chunk → Browser
   │
   ▼
Complete response
   │
   ▼
Save assistant message

That is the version worth keeping in our portfolio and discussing in an int. scenario. Rails requires the response headers to be set before the first stream write and requires the stream to be closed when finished. (Ruby on Rails API)

the next step will be to connect the actual user message → streaming endpoint → browser UI rather than having a standalone stream endpoint.


Debug:ActionController::Live::ClientDisconnected – 500 Internal Server Error

Yes – very likely from our rescue behavior, but the deeper issue is that ActionController::Live::ClientDisconnected is not the same exception as IOError in Rails 8.1.

Rails 8.1 explicitly has:

ActionController::Live::ClientDisconnected

as its own exception class. (Ruby on Rails API)

So this:

rescue IOError
# Browser disconnected

does not necessarily catch the exception you’re seeing.

Why the 500 appears

Our stream is working, then eventually the client closes the connection – or example:

  • browser finishes and closes the SSE connection
  • EventSource.close() is called
  • browser navigates/reloads
  • user closes the tab
  • network connection disappears

Rails detects that the client is gone while processing the Live response and raises:

ActionController::Live::ClientDisconnected

Rails’ Live processing happens in a separate thread, and once the response has been committed Rails handles exceptions differently from a normal controller request. (Ruby on Rails API)

Fix our rescue

add:

rescue ActionController::Live::ClientDisconnected
Rails.logger.info("SSE client disconnected")

You can optionally also handle IOError:

rescue ActionController::Live::ClientDisconnected, IOError
Rails.logger.info("SSE client disconnected")

And keep:

ensure
sse.close
end

So our action should have roughly:

begin
# streaming logic
rescue IOError
Rails.logger.debug(">>>>>>>>>>>>>> Error Occured: IOError")
rescue ActionController::Live::ClientDisconnected
Rails.logger.debug(">>>>>>>>>>>>>> SSE client disconnected")
ensure
sse.close
end

But there is an important point

Don’t interpret ClientDisconnected as an application failure.

It’s closer to:

Rails: "I'm streaming."
Browser: "I'm no longer listening."
Rails: "Okay."

For SSE, that’s a normal lifecycle event.

Why you’re seeing Completed 500

This is the part that initially looks strange.

With ActionController::Live, Rails starts processing the action in a separate thread. When an exception occurs after the response has already been committed/started streaming, Rails can’t behave like a normal controller request with a fresh 500 response. Rails’ Live implementation has special handling for committed responses and closes the stream after logging the exception.

So our log can be misleading:

Completed 500 Internal Server Error
ActionController::Live::ClientDisconnected

even though:

  • the user received the streamed answer successfully,
  • the connection closed normally afterward.

That’s exactly why I would treat ClientDisconnected separately from genuine application errors.


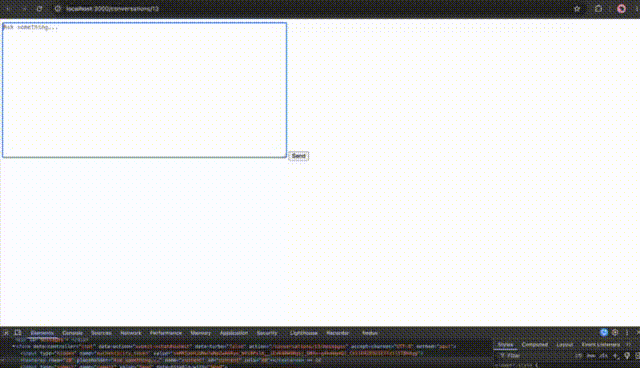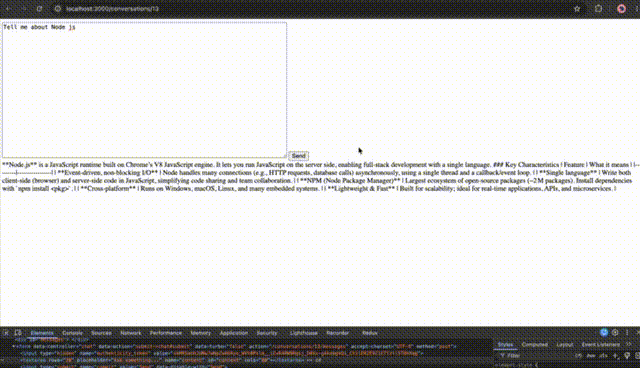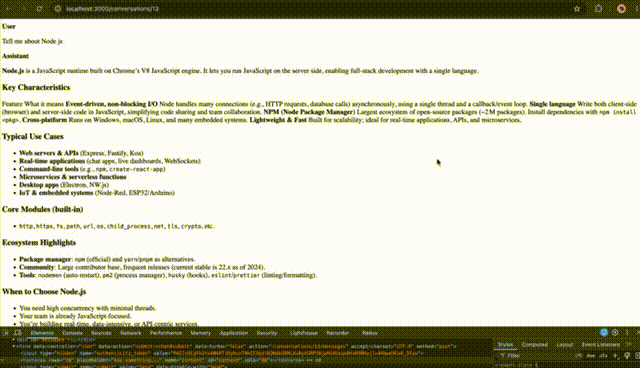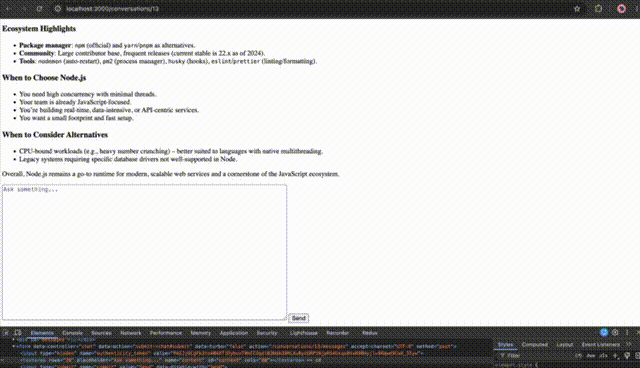
Fix Streaming issue: After entering the question the page get stuck

Our server logs are as follows:

Started POST "/conversations"
Processing by ConversationsController#create as TURBO_STREAM
Parameters: {"...., "conversation" => {"title" => "Tell me about Node js"}, "commit" => "Start conversation"}

Then goes to
Started GET "/conversations/13"
Processing by ConversationsController#show as TURBO_STREAM
Parameters: {"id" => "13"}
Rendering conversations/show.html.erb
200 OK

Then the page stuck on the Form: form_with in the conversations/show.html.erb.
the div streaming-response is blank and it is not going to messages controller#stream or I think it is not executing the chat_controller.js also.

Yes – the server logs strongly suggest the problem is before MessagesController#stream. The conversation page loads correctly, then the form submission isn’t triggering our Stimulus chat#submit.

The likely culprit is Turbo + Stimulus registration, not SSE.

Let’s debug it quickly in the right order.

1. First confirm Stimulus is actually loading

Open your browser DevTools → Console.

Put this temporarily at the top of:

app/javascript/controllers/chat_controller.js
import { Controller } from "@hotwired/stimulus"

console.log("chat_controller.js loaded")

export default class extends Controller {
  connect() {
    console.log("Chat controller connected")
  }

  submit(event) {
    console.log("Chat submit triggered")
    // existing code...
  }
}

Reload:

http://localhost:3000/conversations/13

You should see:

chat_controller.js loaded
Chat controller connected

If you don’t see these

Then the problem is Stimulus registration/import, not the form.

2. Check your Stimulus setup

Because you’re using Rails 8.1, check:

app/javascript/controllers/index.js

It should contain something similar to:

import { application } from "controllers/application"
import ChatController from "controllers/chat_controller"
application.register("chat", ChatController)

Depending on the Rails 8 application template/setup, your index.js may use automatic controller loading instead. The important thing is that chat_controller.js is being registered under:

chat

3. Check application.js

Open:

app/javascript/application.js

You should have the normal Rails setup, typically something along the lines of:

import "@hotwired/turbo-rails"
import "controllers"

The important line is:

import "controllers"

Without it, your Stimulus controllers won’t be registered.

4. Check the actual HTML generated by Rails

This is very important.

Inspect the form in Chrome DevTools.

You should see:

<form
  data-controller="chat"
  data-action="submit->chat#submit"
  ...
>

If you don’t see:

data-controller="chat"

then our view isn’t producing the attributes we expect.

Our form should look approximately like:

<%= form_with(
  url: conversation_messages_path(@conversation),
  method: :post,
  data: {
    controller: "chat",
    action: "submit->chat#submit"
  }
) do |form| %>

5. There is another issue in our previous implementation

This is important.

We currently have:

<%= form_with(... method: :post) %>

but the Stimulus controller is trying to create:

GET /conversations/:id/messages/stream

That means the normal Turbo form submission and our SSE request are two different mechanisms.

We don’t actually want Turbo submitting the form at all.

Let Stimulus own the submission.

Change the form to:

<%= form_with(
  url: conversation_messages_path(@conversation),
  method: :post,
  data: {
    controller: "chat",
    action: "submit->chat#submit",
    turbo: false
  }
) do |form| %>

  <%= form.text_area :content,
      rows: 4,
      placeholder: "Ask something..." %>

  <%= form.submit "Send" %>
<% end %>

<div id="streaming-response"></div>

The important addition is:

turbo: false

This prevents Turbo from hijacking the form submission.

6. But there’s a second problem: EventSource

Our previous controller used:

const source = new EventSource(streamUrl)

That means the browser makes:

GET /conversations/13/messages/stream

and that endpoint expects:

params[:content]

So the URL must contain:

?content=Tell+me+about+Node+js

Let’s make the controller simpler and more reliable.

Use:

app/javascripts/controllers/chat_controller.js

import { Controller } from "@hotwired/stimulus"

console.log("chat_controller.js loaded")

export default class extends Controller {
  connect() {
    console.log("Chat controller connected")
  }

  submit(event) {
    console.log("Chat submit triggered")

    event.preventDefault()

    const form = event.currentTarget
    const url = form.action
    const formData = new FormData(form)

    const responseElement = document.querySelector("#streaming-response")
    responseElement.textContent = ""

    const conversationId = url.match(/conversations\/(\d+)\/messages/)[1]
    const streamUrl = 
      `/conversations/${conversationId}/messages/stream?${new URLSearchParams(
          formData
        )}`

    const source = new EventSource(streamUrl)
    source.addEventListener("message", (event) => {
      const data = JSON.parse(event.data)

      responseElement.textContent += data.content
    })

    source.addEventListener("done", () => {
      source.close()

      // Reload for now so the persisted assistant message appears.
      window.location.reload()
    })

    source.onerror = () => {
      source.close()
      responseElement.textContent += "\n\n[AI stream disconnected]"
    }
  }
}

7. Verify the route

Run:

bin/rails routes | grep messages

You should have something like:

conversation_messages
conversation_messages_stream

Specifically:

GET /conversations/:conversation_id/messages/stream

If you don’t have that route, the browser will never reach:

MessagesController#stream

8. Test the route independently

Before testing Stimulus, prove the endpoint itself still works:

curl -N \
-H "Accept: text/event-stream" \
"http://localhost:3000/conversations/13/messages/stream?content=Explain%20Node.js"

Since you already confirmed SSE works, this should still stream.

9. Then test the browser

Reload the conversation page and open DevTools → Console.

When the page loads:

Chat controller connected

When you submit:

Chat submit triggered

Then open DevTools → Network.

You should see:

GET /conversations/13/messages/stream?content=...

and its response should remain open while the AI streams.

If you see that request, the pipeline is working:

Form
Stimulus
EventSource
GET /messages/stream
MessagesController#stream
LLM
SSE
Browser

10. Why our current log looks the way it does

You currently see:

POST /conversations
GET /conversations/13
Rendering conversations/show
200 OK

and nothing afterward.

That means:

Rails page rendering ✅
Stimulus submit ❌

The fact that we don’t see:

Started GET "/conversations/13/messages/stream"

is the strongest clue.

So don’t debug ActionController::Live or OpenRouter yet.

The problem is almost certainly:

Stimulus controller registration
OR
Turbo intercepting the form
OR
data-controller/data-action not present

Cheers! We solved it.


Recommended architectural change (Optional)

One option is we can stop using EventSource with a GET query parameter for the actual chat request.

It’s fine for learning SSE, but for a real AI application, sending the user prompt as:

GET /messages/stream?content=...

isn’t ideal.

We’ll eventually use:

POST /conversations/:id/messages

with fetch() and consume the streaming response body:

POST
Rails
LLM stream
ReadableStream
Browser

We have to keep the user’s message in the POST body and have a single request lifecycle.

But this make our current app/javascript/controllers/chat_controller.js to re-write completely. So let’s move on to the next step ASAP.

to be continued…

Integrate AI with Rails: AI bootcamp for Developers – Day 6 – Build the Rails Chat UI | Prompt Builder | Chat Memory

In this session we will be building prompt builder to build the prompt that we send to the AI model. We save every conversation in memory and create a chat feature backend architecture.

Step 7 – Conversation Memory + Prompt Builder

Right now our Ai::ChatService sends only:

current user message

So this:

User: My name is Abhilash.
User: What is my name?

doesn’t reliably work as a conversation because the second request doesn’t include the first message.

We need:

Conversation
   ↓
Messages
   ↓
Prompt Builder
   ↓
LLM

1. Change Ai::Client to accept messages

Open:

app/services/ai/client.rb

Change chat from:

def chat(message:)
  ...
end

to:

def chat(messages:)
  response = @client.chat.completions.create(
    model: MODEL,
    messages: messages
  )

  {
    content: response.choices.first.message.content,
    model: response.model,
    input_tokens: response.usage.prompt_tokens,
    output_tokens: response.usage.completion_tokens
  }
end

The client should now know nothing about conversations.

It simply receives:

messages = [
{ role: "system", content: "..." },
{ role: "user", content: "..." },
{ role: "assistant", content: "..." }
]

2. Create PromptBuilder

Create:

app/services/ai/prompt_builder.rb

Add:

class Ai::PromptBuilder
  SYSTEM_PROMPT = <<~PROMPT
    You are a helpful AI assistant.
    Answer clearly and concisely.
    If you are unsure about something, say so.
  PROMPT

  def initialize(conversation:)
    @conversation = conversation
  end

  def build
    [
      {
        role: "system",
        content: SYSTEM_PROMPT.strip
      },
      *@conversation.messages.order(:created_at).map do |message|
        {
          role: message.role,
          content: message.content
        }
      end
    ]
  end
end

Now our database becomes the source of conversation history.

3. Update Ai::ChatService

Change it to:

class Ai::ChatService
  def initialize(
    ai_client: Ai::Client.new,
    prompt_builder_class: Ai::PromptBuilder
  )
    @ai_client = ai_client
    @prompt_builder_class = prompt_builder_class
  end

  def call(conversation:, user_message:)
    conversation.transaction do
      conversation.messages.create!(
        role: :user,
        content: user_message
      )

      messages = @prompt_builder_class
        .new(conversation: conversation)
        .build

      result = @ai_client.chat(messages: messages)

      conversation.messages.create!(
        role: :assistant,
        content: result[:content],
        model: result[:model],
        input_tokens: result[:input_tokens],
        output_tokens: result[:output_tokens]
      )
    end
  end
end

Notice the order:

1. Save user message
2. Load conversation history
3. Build LLM messages
4. Call LLM
5. Save assistant response

4. Test it manually

Run:

bin/rails c

Create a fresh conversation:

conversation = Conversation.create!(title: "Memory Test")

First question:

Ai::ChatService.new.call(
conversation: conversation,
user_message: "My name is Abhilash."
)

Then:

Ai::ChatService.new.call(
conversation: conversation,
user_message: "What is my name?"
)

Now, we should see approximately:

ai-assistant(dev):031> puts conversation.messages.map {|m| "Role: #{m.role}\n Content: #{m.content}" }.join("\n")
Role: user
 Content: My name is Adam Bean
Role: assistant
 Content: Hello Adam Bean! How can I assist you today?

Role: user
 Content: What is my name?
Role: assistant
 Content: Your name is Adam Bean.
=> nil

This is our first real conversation memory implementation.

The LLM did not magically remember the first request.

Rails retrieved the previous messages and sent them again.

That’s a very important int. concept.

5. Understand the architecture

We now have:

                    Conversation
                         │
                         ▼
                    ChatService
                         │
             ┌───────────┴───────────┐
             ▼                       ▼
       PromptBuilder            Ai::Client
             │                       │
             │ messages              │
             └───────────┬───────────┘
                         ▼
                       LLM
                         │
                         ▼
                  Assistant Message
                         │
                         ▼
                    PostgreSQL

The responsibilities are now nicely separated:

Conversation

Persistence.

PromptBuilder

Converts application state into LLM input.

Ai::Client

Talks to the provider.

ChatService

Orchestrates the workflow.

Now we built a solid Rails architecture.

6. Important problem: context growth

Our current implementation sends:

every previous message

on every request.

That eventually becomes:

Message 1
Message 2
...
Message 500
+
New Message

Problems:

  • more tokens
  • more cost
  • more latency
  • eventually context-window limits

This is one of the reasons production AI systems eventually introduce:

conversation summarization
+
recent-message window
+
RAG

Note: We’ll address this later.

Next Major Step – Chat UI

Now we have the backend flow:

User
ChatService
PromptBuilder
LLM
PostgreSQL

The next thing we’ll build is the actual Rails chat interface:

┌──────────────────────────────┐
│ AI Assistant │
├──────────────────────────────┤
│ You: What is Ruby? │
│ │
│ AI: Ruby is... │
│ │
│ You: Explain blocks. │
│ │
│ AI: A block is... │
├──────────────────────────────┤
│ [ Ask something... ] [Send] │
└──────────────────────────────┘

We’ll use Rails + Turbo/Stimulus, then add streaming immediately after that.

That will turn the backend we’ve built into an actual usable AI application.


Let’s move straight to the Chat UI + controller flow, then we can add streaming. We’ll keep this as one cohesive implementation step.

Step 8 – Build the Rails Chat UI

Our backend already does:

Conversation
ChatService
PromptBuilder
Ai::Client
LLM
Message

Now we’ll expose it through HTTP.

8.1 Generate the controller

Run:

bin/rails g controller Conversations show

This gives us a starting point:

app/controllers/conversations_controller.rb
app/views/conversations/show.html.erb

But we also need an endpoint for sending messages.

8.2 Define routes

Open:

config/routes.rb

Use:

Rails.application.routes.draw do
  resources :conversations, only: [:create, :show] do
    resources :messages, only: [:create]
  end

  root "conversations#new"
end

We don’t have new yet, so let’s instead make a simple root action ourselves.

Change to:

Rails.application.routes.draw do
  resources :conversations, only: [:create, :show] do
    resources :messages, only: [:create]
  end

  root "conversations#new"
end

Then generate new:

bin/rails g controller Conversations new

8.3 Conversation controller

Open:

app/controllers/conversations_controller.rb

Use:

class ConversationsController < ApplicationController
  def new
    @conversation = Conversation.new
  end

  def create
    @conversation = Conversation.create!(title: params[:title].presence || "New conversation")

    redirect_to conversation_path(@conversation)
  end

  def show
    @conversation = Conversation.find(params[:id])
    @messages = @conversation.messages.order(:created_at)
  end
end

For now we’re deliberately keeping authentication out of the project.

Later we’ll add authorization when we make this production-oriented.


8.4 Create the messages controller

Run:

bin/rails g controller Messages

Open:

app/controllers/messages_controller.rb

Add:

class MessagesController < ApplicationController
  def create
    conversation = Conversation.find(params[:conversation_id])

    Ai::ChatService.new.call(
      conversation: conversation,
      user_message: params.require(:content)
    )

    redirect_to conversation_path(conversation)
  end
end

The request flow is now:

POST /conversations/:id/messages
MessagesController
Ai::ChatService
LLM

8.5 Build the new conversation page

Open:

app/views/conversations/new.html.erb
<h1>AI Assistant</h1>
<%= form_with model: @conversation, local: true do |form| %>
<%= form.text_field :title, placeholder: "Conversation title" %>
<%= form.submit "Start conversation" %>
<% end %>

Now run:

bin/rails server

Open:

http://localhost:3000

Create a conversation.


8.6 Build the chat page

Open:

app/views/conversations/show.html.erb

Use:

<h1><%= @conversation.title %></h1>

<div id="messages">
  <% @messages.each do |message| %>
    <div>
      <strong><%= message.role.capitalize %>:</strong>
      <%= message.content %>
    </div>
  <% end %>
</div>

<hr>

<%= form_with url: conversation_messages_path(@conversation), method: :post, local: true do |form| %>
  <%= form.text_area :content, rows: 4, placeholder: "Ask something..." %>

  <%= form.submit "Send" %>
<% end %>

Now we have an actual chat interface.


8.7 Test the complete flow

Open:

http://localhost:3000

Create:

Ruby Questions

Then ask:

What is a Ruby block?

The flow should be:

Browser
   ↓
POST /conversations/1/messages
   ↓
MessagesController
   ↓
Ai::ChatService
   ↓
PromptBuilder
   ↓
OpenRouter
   ↓
Assistant response
   ↓
Message saved
   ↓
Redirect
   ↓
Conversation page

You should see:

User: What is a Ruby block?
Assistant: ...

Then ask:

Can you show me an example?

Rails should send the previous conversation history through PromptBuilder.


8.8 One important issue with our current implementation

We’re currently doing:

Ai::ChatService.new.call(...)

inside the HTTP request.

That means:

Browser
  ↓
Rails request
  ↓
wait for LLM
  ↓
save response
  ↓
response

If the LLM takes 8 seconds, our web request can take 8 seconds.

That’s acceptable for our learning version, but not what we ultimately want.

The next step is streaming.


8.9 Also notice an architectural limitation

Right now we’re doing:

redirect_to conversation_path(conversation)

After the LLM finishes.

That’s why the user sees:

wait...
wait...
wait...
complete response

ChatGPT-style applications instead do:

User message
      ↓
LLM starts generating
      ↓
token
      ↓
token
      ↓
token
      ↓
browser updates

We’ll implement that next.


8.10 Add a little UI structure

We can improve the view slightly now:

<h1><%= @conversation.title %></h1>

<div id="messages">
  <% @messages.each do |message| %>
    <article class="message <%= message.role %>">
      <strong><%= message.role.capitalize %></strong>
      <p><%= simple_format(message.content) %></p>
    </article>
  <% end %>
</div>

<%= form_with url: conversation_messages_path(@conversation), method: :post, local: true do |form| %>
  <%= form.text_area :content,
      rows: 4,
      placeholder: "Ask something..." %>

  <%= form.submit "Send" %>
<% end %>

Don’t spend time on styling yet. We care about architecture first.


Fix Chat UI Markdown problem

If we use the following for showing the content:

<p><%= simple_format(message.content) %></p>
Or
<p><%= sanitize(message.content) %></p>

The issue is that sanitize is not a Markdown renderer.

Our LLM is returning Markdown:

**Ruby block**
### Key Characteristics
* Not an object

Rails’ sanitize only sanitizes HTML that already exists. It doesn’t convert Markdown → HTML.

So this:

<%= sanitize(message.content) %>

won’t turn:

**Ruby**

into:

<strong>Ruby</strong>

Recommended approach

For an AI chat application, use:

LLM Markdown
Markdown renderer
HTML
sanitize
Browser

1. Add a Markdown gem

For Rails, a simple choice is commonmarker.

Add to Gemfile:

gem "commonmarker"

Then:

bundle install

2. Create a Markdown helper

Create:

app/helpers/markdown_helper.rb
module MarkdownHelper
  def render_markdown(text)
    html = Commonmarker.to_html(text.to_s)

    sanitize(
      html,
      tags: %w[
        p
        br
        strong
        em
        del
        h1
        h2
        h3
        h4
        ul
        ol
        li
        blockquote
        pre
        code
        a
      ],
      attributes: %w[href title]
    )
  end
end

The important distinction is:

Commonmarker.to_html(...)

does the Markdown conversion.

Then:

sanitize(...)

does the HTML security filtering.

3. Change your view

Currently you probably have:

<p><%= simple_format(message.content) %></p>

or:

<%= sanitize(message.content) %>

Change it to:

<div class="message-content">
<%= render_markdown(message.content) %>
</div>

Now your response:

A **Ruby block** is...
### Key Characteristics
* Not an object
* Can be passed to a method

will render approximately as:

A Ruby block is…

4. Important security point

Do not do this:

<%= raw(Commonmarker.to_html(message.content)) %>

without sanitization.

The LLM output is still untrusted input.

Keep:

sanitize(Commonmarker.to_html(text))

as your pipeline.

That’s a good senior-level AI security practice:

LLM output
Markdown parser
HTML
Sanitizer
Browser

What we’ve built so far

We’re no longer just experimenting with an API.

We now have:

                    Rails AI Assistant

Browser
   │
   ▼
Conversation UI
   │
   ▼
MessagesController
   │
   ▼
Ai::ChatService
   │
   ├── Conversation history
   │
   ▼
Ai::PromptBuilder
   │
   ▼
Ai::Client
   │
   ▼
OpenRouter
   │
   ▼
Free LLM
   │
   ▼
Message
   │
   ▼
PostgreSQL

That is already something we can discuss in a senior int.

Check our code in this repo: https://github.com/abhilashak/ai_assistant


Next: Step 9 – Streaming

We’ll now replace:

submit → wait → redirect

with:

submit
Rails
LLM streaming
token-by-token response
browser

We’ll use the Rails 8.1 stack appropriately and discuss SSE vs Turbo Streams vs Action Cable, rather than merely copying a ChatGPT-style implementation.

Happy AI Integration!

Integrate AI with Rails: AI bootcamp for Developers – Day 5 –Use OpenRouter API, Create AI Chat service

We had a problem making a LLM request to get the response due to the lack of remaining credits in the last part. Let’s solve it in this part using OpenRouter APIs. You can read more about this here: Openrouter ai- one api for multiple ai models

Let’s switch now to OpenRouter’s free-model tier rather than DeepSeek directly. As of April 2026, OpenRouter offers free models at $0 input/output pricing and its openrouter/free router automatically selects an available free model; the free plan currently has a 50-requests/day limit. (OpenRouter)

This is actually a useful improvement for our bootcamp because OpenRouter exposes an OpenAI-compatible API, so we can keep the openai Ruby SDK and change only the endpoint + API key + model. (OpenRouter)

Step 5.17 – Switch Ai::Client to OpenRouter Free

We are not changing our Rails architecture:

Rails
Ai::Client
OpenAI-compatible SDK
OpenRouter
Free LLM

1. Create an OpenRouter API key

Create an account at OpenRouter and create an API key.

It should look approximately like:

sk-or-v1-...

OpenRouter documents this flow in its free-model quickstart. (OpenRouter)

Do not paste the key here.

2. Change Rails credentials

We currently have:

openai:
api_key: ...

Let’s change this to:

openrouter:
api_key: OUR_OPENROUTER_KEY

Run:

bin/rails credentials:edit

Change:

openai:
api_key: ...

to:

openrouter:
api_key: ...

Save and exit.

3. Update Ai::Client

Open:

app/services/ai/client.rb

For now, use:

class Ai::Client
  MODEL = "openrouter/free"
  BASE_URL = "https://openrouter.ai/api/v1"

  def initialize
    @api_key = Rails.application.credentials.dig(:openrouter, :api_key)

    raise "OpenRouter API key is missing" if @api_key.blank?

    @client = OpenAI::Client.new(
      api_key: @api_key,
      base_url: BASE_URL
    )
  end

  def chat(message:)
    @client.chat.completions.create(
      model: MODEL,
      messages: [
        {
          role: "user",
          content: message
        }
      ]
    )
  end
end

OpenRouter explicitly documents using an OpenAI-compatible client by changing the base URL to:

https://openrouter.ai/api/v1

and then using the OpenAI-style chat completions API. (OpenRouter)

Important change

Previously we were using:

@client.responses.create(...)

Now we’re using:

@client.chat.completions.create(...)

That’s intentional. OpenRouter supports Responses API for its free router, but its OpenAI-compatible chat-completions interface is the simplest and most broadly compatible path for this exercise.

4. Test credentials first

Run:

bin/rails c

Then:

Rails.application.credentials.dig(:openrouter, :api_key)

Make sure it returns a value.

Don’t paste it here.

Then:

exit

5. Make the first free LLM request

Run:

bin/rails c

Then:

client = Ai::Client.new

And:

response = client.chat(
message: "Explain Ruby blocks in simple terms."
)

Now inspect:

response

Then:

response.choices.first.message.content

You should get the model’s response.

6. Inspect usage

Run:

response.usage

Then:

response.usage.prompt_tokens

and:

response.usage.completion_tokens

The exact response shape depends on the model/provider, so we’re intentionally inspecting it rather than assuming the field names.

OpenRouter Dashboard – token usage

7. What did we just accomplish?

Our application has now become provider-independent at the architecture level:

                    Ai::Client
                        │
                 ┌──────┴──────┐
                 │             │
              Provider       Provider
                 │             │
              OpenAI       OpenRouter
                                │
                           Free Models

And later we can support:

OpenRouter
  ├── gpt-oss-20b
  ├── Nemotron
  ├── other free models
  └── paid models


OpenRouter currently lists multiple free models, including OpenAI’s gpt-oss-20b and NVIDIA Nemotron variants. (OpenRouter)

We won’t hard-code a specific free model yet because the free-model pool changes over time. openrouter/free is specifically designed to route requests to an available free model.

8. One important lesson

This change demonstrates a valuable architectural idea:

The LLM provider should be an implementation detail behind our AI service boundary.

Today:

Ai::Client → OpenRouter

Later:

Ai::Client → OpenAI

or:

Ai::Client → Anthropic

without changing:

Conversation
Message
ChatService
Controllers
UI

That’s exactly why we created Ai::Client before integrating the provider.


Stop here

Do these steps in order:

bin/rails credentials:edit

Set:

openrouter:
api_key: OUR_OPENROUTER_KEY

Then update Ai::Client as shown above and run:

bin/rails c
client = Ai::Client.new
response = client.chat(
message: "Explain Ruby blocks in simple terms."
)

Then:

response.choices.first.message.content

Once that works, check the output:

➜  ai_assistant git:(main) ✗ rails c
Loading development environment (Rails 8.1.3.1)
ai-assistant(dev):001> client = Ai::Client.new
=> 
#<Ai::Client:0x000000012d5ca138
...
ai-assistant(dev):002* response = client.chat(
ai-assistant(dev):003*   message: "How can I become an expert in Ruby language"
ai-assistant(dev):004> )
=> 
#<OpenAI::Models::Chat::ChatCompletion:0x22c8 {id: "gen-1786952686-y1YoZ2KFkNMw6Le1xdp5", choices: [{finish_reason: :stop, index: 0, logpr...
ai-assistant(dev):005> response.choices.first.message.content
ai-assistant(dev):006> 
=> "User Safety: safe" # our api not started working
ai-assistant(dev):002> conversation = Conversation.first
ai-assistant(dev):003* conversation.messages.order(:created_at).each do |message|
ai-assistant(dev):004*   puts "#{message.role}: #{message.content}"
ai-assistant(dev):005> end
  Message Load (9.9ms)  SELECT "messages".* FROM "messages" WHERE "messages"."conversation_id" = 1 ORDER BY "messages"."created_at" ASC /*application='AiAssistant'*/
user: What is Ruby? # our api not started working
user: What is Ruby? in 20 words
assistant: Ruby is a dynamic, object‑oriented language emphasizing developer happiness, known for elegant syntax and powerful, full‑featured, open‑source web framework Rails.

OpenRouter free model works!

Then we’ll immediately proceed to the next step: cleanly extracting the provider response and mapping it into our Message model, which is where the application starts becoming a real AI chat application rather than just an API experiment.


Create AI Chat Service, Store Messages

Now make the LLM response usable by Rails, persist it as a Message and introduce Ai::ChatService.

This is the point where our app changes from:

Rails → LLM API

to:

Rails
ChatService
Ai::Client
LLM
ChatService
Message
PostgreSQL

OpenRouter’s OpenAI-compatible API returns the normal chat-completions shape with choices[0].message.content, and the OpenAI Ruby SDK exposes typed response objects with hash-style access as well. (OpenRouter)

Step 6 – Clean up Ai::Client

We don’t want the rest of the application knowing about:

response.choices.first.message.content

That’s provider/SDK-specific knowledge.

Change app/services/ai/client.rb to:

class Ai::Client
  MODEL = "openrouter/free"
  BASE_URL = "https://openrouter.ai/api/v1"

  def initialize
    api_key = Rails.application.credentials.dig(:openrouter, :api_key)

    raise "OpenRouter API key is missing" if api_key.blank?

    @client = OpenAI::Client.new(
      api_key: api_key,
      base_url: BASE_URL
    )
  end

  def chat(message:)
    response = @client.chat.completions.create(
      model: MODEL,
      messages: [
        {
          role: "user",
          content: message
        }
      ]
    )

    {
      content: response.choices.first.message.content,
      model: response.model,
      input_tokens: response.usage.prompt_tokens,
      output_tokens: response.usage.completion_tokens
    }
  end
end

Now Ai::Client has a clean contract:

{
content: "...",
model: "...",
input_tokens: 123,
output_tokens: 456
}

The rest of Rails doesn’t care whether the provider uses choices, output_text, or something else.

Why this abstraction matters

Today:

Ai::Client → OpenRouter

Tomorrow:

Ai::Client → OpenAI

The rest of your application doesn’t change.


Step 7 – Test the new client

Run:

bin/rails c

Then:

client = Ai::Client.new

Then:

result = client.chat(message: "Explain Ruby blocks in two sentences.")

Inspect:

result

You should get something like:

{
content: "...",
model: "...",
input_tokens: 20,
output_tokens: 40
}

This is our internal application-level response.


Step 8 – Create Ai::ChatService

Now create:

app/services/ai/chat_service.rb

Code:

class Ai::ChatService
  def initialize(ai_client: Ai::Client.new)
    @ai_client = ai_client
  end

  def call(conversation:, user_message:)
    user_message_record = conversation.messages.create!(
      role: :user,
      content: user_message
    )

    result = @ai_client.chat(message: user_message)

    assistant_message = conversation.messages.create!(
      role: :assistant,
      content: result[:content],
      model: result[:model],
      input_tokens: result[:input_tokens],
      output_tokens: result[:output_tokens]
    )

    {
      user_message: user_message_record,
      assistant_message: assistant_message
    }
  end
end

This class is now responsible for the application workflow.

Notice the separation:

Ai::Client

How do I talk to the LLM provider?

Ai::ChatService

What should happen when a user sends a chat message?

That’s a very important Rails design boundary.


Step 9 – Test the full flow

Start console:

bin/rails c

Find your conversation:

conversation = Conversation.first

Then:

service = Ai::ChatService.new

Now:

result = service.call(
conversation: conversation,
user_message: "What is Ruby?"
)

Inspect:

result[:user_message]

and:

result[:assistant_message]

Now:

conversation.messages.order(:created_at).each do |message|
puts "#{message.role}: #{message.content}"
end

You should now have:

user: What is Ruby?
assistant: Ruby is ...

Now we have a real persistent AI conversation.


Step 10 – Inspect PostgreSQL

Exit console:

exit

Then:

bin/rails dbconsole

Run:

SELECT
  id,
  conversation_id,
  role,
  model,
  input_tokens,
  output_tokens,
  content
FROM messages
ORDER BY id;

This is important because you’re seeing the complete lifecycle:

User input
Rails
LLM
AI response
Message record
PostgreSQL

Step 11 – Add a transaction

There’s a subtle production problem in our current service.

Imagine:

Save user message ✅
Call AI ✅
Save assistant message ❌

Now the conversation is incomplete.

At minimum, make the persistence workflow transactional:

class Ai::ChatService
  def initialize(ai_client: Ai::Client.new)
    @ai_client = ai_client
  end

  def call(conversation:, user_message:)
    conversation.transaction do
      user_message_record = conversation.messages.create!(
        role: :user,
        content: user_message
      )

      result = @ai_client.chat(message: user_message)

      assistant_message = conversation.messages.create!(
        role: :assistant,
        content: result[:content],
        model: result[:model],
        input_tokens: result[:input_tokens],
        output_tokens: result[:output_tokens]
      )

      {
        user_message: user_message_record,
        assistant_message: assistant_message
      }
    end
  end
end

Important nuance

The database transaction does not roll back an external LLM API call.

That’s a classic distributed-system issue:

PostgreSQL transaction
+
External API

The DB transaction protects your local writes, but it can’t undo the provider request.

Step 12 – Write the first test

Since you have a real service now, let’s test it.

Create:

test/services/ai/chat_service_test.rb

because Rails 8 defaults to Minitest.

Example:

require "test_helper"

class Ai::ChatServiceTest < ActiveSupport::TestCase
  test "persists user and assistant messages" do
    conversation = Conversation.create!(title: "Test")

    fake_client = Minitest::Mock.new

    fake_client.expect(
      :chat,
      {
        content: "Ruby is a programming language.",
        model: "test-model",
        input_tokens: 10,
        output_tokens: 8
      },
      [{ message: "What is Ruby?" }]
    )

    service = Ai::ChatService.new(ai_client: fake_client)

    service.call(
      conversation: conversation,
      user_message: "What is Ruby?"
    )

    assert_equal 2, conversation.messages.count
    assert conversation.messages.user.exists?
    assert conversation.messages.assistant.exists?

    fake_client.verify
  end
end

Run:

bin/rails test test/services/ai/chat_service_test.rb

The important idea is:

The test doesn’t call OpenRouter.

We replace the external dependency with a fake.

That’s exactly how we should test AI integrations.

Update the test

require "test_helper"

class Ai::ChatServiceTest < ActiveSupport::TestCase
  test "persists user and assistant messages" do
    conversation = Conversation.create!(title: "Test")

    fake_client = Minitest::Mock.new

    fake_client.expect(
      :chat,
      {
        content: "Ruby is a programming language.",
        model: "test-model",
        input_tokens: 10,
        output_tokens: 8
      },
      message: "What is Ruby?"
    )

    service = Ai::ChatService.new(ai_client: fake_client)

    service.call(
      conversation: conversation,
      user_message: "What is Ruby?"
    )

    assert_equal 2, conversation.messages.count

    user_message = conversation.messages.user.first
    assistant_message = conversation.messages.assistant.first

    assert_equal "What is Ruby?", user_message.content
    assert_equal "Ruby is a programming language.", assistant_message.content
    assert_equal "test-model", assistant_message.model
    assert_equal 10, assistant_message.input_tokens
    assert_equal 8, assistant_message.output_tokens

    fake_client.verify
  end
end

What We Have Now

We have crossed a significant milestone:

                ┌──────────────────┐
                │   Conversation   │
                └────────┬─────────┘
                         │
                         ▼
                ┌──────────────────┐
                │  ChatService     │
                └────────┬─────────┘
                         │
                         ▼
                ┌──────────────────┐
                │    Ai::Client    │
                └────────┬─────────┘
                         │
                         ▼
                ┌──────────────────┐
                │    OpenRouter    │
                │   Free LLM       │
                └────────┬─────────┘
                         │
                         ▼
                ┌──────────────────┐
                │ Assistant Msg    │
                └────────┬─────────┘
                         │
                         ▼
                    PostgreSQL

This gives you several int. concepts already:

LLM integration, service objects, provider abstraction, persistence, token tracking, transactions, external API boundaries, and testing.

Check our code in this repo: https://github.com/abhilashak/ai_assistant


Next: Step 7 – Conversation Memory + Prompt Builder

Right now, every request is independent.

We’ll change:

"What is Ruby?"

into:

System Prompt
+
Previous Messages
+
Current User Message
LLM

Then we’ll build Ai::PromptBuilder, add conversation history, and after that move quickly into the Chat UI + streaming.

to be continued …

Integrate AI with Rails: AI bootcamp for Developers – Day 4 -Practical Course – Part 3

Great. Now we can make the first real LLM request.

We’ll keep this step deliberately small. Our goal is not to build the complete AI assistant yet.

The goal is simply:

Rails
Ai::Client
OpenAI API
LLM
Response

Once this works, we’ll build the Rails service layer around it.

Step 5.11 – Add the OpenAI Ruby SDK

Rather than manually constructing HTTP requests, we’ll start with the official Ruby SDK.

1. Add the gem

Open our Gemfile and add:

gem "openai"

Then run:

bundle install

Verify:

bundle info ruby-openai

You should see where Bundler installed the gem.

Why use an SDK?

We could use Ruby’s Net::HTTP ourselves:

Ruby
Net::HTTP
HTTP request
OpenAI

But then we’d have to manually handle:

  • authentication headers
  • JSON encoding
  • HTTP errors
  • response parsing
  • request formatting

The SDK gives us:

Ruby
OpenAI Ruby SDK
HTTP
OpenAI

Important point: An SDK doesn’t eliminate the HTTP API. It is an abstraction over it.

Step 5.12 – Verify the gem

Run:

bin/rails console

Then:

require "openai"

It should return:

=> true

or possibly:

=> "openai"

depending on the gem’s load behavior.

Then:

OpenAI

should resolve without a NameError.

Exit:

exit

Step 5.13 – Let’s inspect the SDK before using it

This is something I want you to develop as a senior Ruby developer habit.

Instead of blindly copying code from a blog, let’s see what API the installed gem exposes.

Run:

bundle info ruby-openai

Then:

bin/rails console

Inside console:

require "openai"

Then:

OpenAI::Client.instance_method(:initialize).parameters

This tells us what the client’s constructor expects.

Also try:

OpenAI::Client.instance_methods(false)

We’re learning to inspect a Ruby library rather than treating it as magic.

Step 5.14 – Create the OpenAI client

Now let’s modify:

app/services/ai/client.rb

We’ll start with:

class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?

    @client = OpenAI::Client.new(api_key: @api_key)
  end
end

Now we have:

Ai::Client
   │
   ├── reads Rails credentials
   │
   └── creates OpenAI SDK client

Step 5.15 – Test initialization

Run:

bin/rails console

Then:

client = Ai::Client.new

It should return something similar to:

#<Ai::Client:0x...>

No request has happened yet.

That’s important.

We’ve only done:

Rails credentials
API key
OpenAI::Client

Stop here

Don’t call the LLM yet.

I want you to complete these steps first:

1. Gemfile

gem "openai"

2. Install

bundle install

3. Verify

bundle info ruby-openai

4. Update

app/services/ai/client.rb

with the code above.

5. Test

bin/rails c
client = Ai::Client.new

One note

The Ruby OpenAI SDK’s API can change between versions, so don’t blindly copy the exact request syntax from older tutorials. That’s why we’re checking the version we’ve actually installed before writing the API call.

Now we’ve:

“OpenAI client initialized.”

We’ll make our first actual LLM request and inspect the complete response, including:

response
model
output
usage
input tokens
output tokens

That will lead directly into why we added those fields to our Message model.


@client = OpenAI::Client.new(api_key: @api_key)

We’ll use our installed SDK’s API, not older ruby-openai examples. The current official openai Ruby SDK documents OpenAI::Client.new(api_key: ...) and the Responses API as the current interface. (GitHub)

Step 5.16 – Make the First Real LLM Request

For this step, we’ll do one simple request and inspect the response.

We are not integrating it with Conversation or Message yet.

Our goal is:

Rails console
Ai::Client
OpenAI Responses API
LLM
Response

1. Add a chat method

Open:

app/services/ai/client.rb

Change it to:

class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?

    @client = OpenAI::Client.new(api_key: @api_key)
  end

  def chat(message)
    @client.responses.create(
      model: "gpt-5.2",
      input: message
    )
  end
end

The SDK’s current Responses API accepts model and input for creating a response. (GitHub)

Why input: message?

We’re deliberately starting with the simplest possible request:

input: "Explain Ruby blocks in simple terms"

Later we’ll send structured conversation history:

input: [
{ role: :system, content: "..." },
{ role: :user, content: "..." }
]

The Responses API supports both simple input and structured message input. (GitHub)

2. Start Rails console

bin/rails c

Create the client:

client = Ai::Client.new

Now make the request:

response = client.chat(
message: "Explain Ruby blocks in simple terms."
)

This is the moment our application makes an actual network request.

3. Inspect the response

First:

response.class

Then:

response

Don’t worry if the output is large.

The current official Ruby SDK returns typed response objects and the response contains the generated output plus metadata such as usage. (GitHub)

But if you get the following output, we can change the model which has free API calls:

ai-assistant(dev):013> client = Ai::Client.new
ai-assistant(dev):003> res = ai.chat('I want to be a expert in Ruby language')
app/services/ai/client.rb:11:in 'Ai::Client#chat': {url: "https://api.openai.com/v1/responses", status: 429, body: {error: {message: "You have no credits remaining. Add credits to continue using the API at https://platform.openai.com/settings/organization/billing/.", type: "insufficient_quota", param: nil, code: "credit_balance_exhausted"}}} (OpenAI::Errors::RateLimitError)
        from (ai-assistant):3:in '<compiled>'

Yes – the error makes sense and there is an important distinction here:

Our ChatGPT subscription and OpenAI API billing are separate.

So even if you can use ChatGPT normally, that does not give your Ruby application free API calls. OpenAI explicitly says ChatGPT and API billing are managed separately. (OpenAI Help Center)

Why you’re seeing You have no credits remaining

Your Rails code is calling the OpenAI API, not ChatGPT:

Rails app
OpenAI API
API billing / credits

The API account associated with your key currently has no usable credits. OpenAI’s current prepaid-billing documentation says API requests stop once the available credit balance is exhausted. (OpenAI Help Center)

“But aren’t basic models free?”

Not generally for the API.

There may be specific free/trial allocations or products with included usage, but you should not assume that a model being available in ChatGPT means the API is free.

For our Rails application, we’re using:

OpenAI::Client

which consumes API usage and is metered separately.


What I recommend for our course

I don’t think we should spend money just to continue learning unless you’re comfortable doing so.

We have three practical paths:

Option 1 – Add a small API balance

Open your OpenAI API billing overview and check your balance. New API users currently use prepaid billing and the documented minimum purchase is $5, with $10 as the default purchase amount. (OpenAI Help Center)

For this course a small balance should be plenty for experimentation because our prompts will be tiny.

Option 2 – Use another provider with a free tier

We could temporarily use a provider that offers some free API usage, while keeping the same architecture:

Ai::Client
Provider
LLM

This is actually useful because later we’ll make our architecture provider-agnostic.

Option 3 – Run a local model

We can install something like Ollama and run an LLM locally:

Rails
Ai::Client
localhost
Local LLM

Advantages:

  • no API credits
  • no network dependency
  • no per-token cost
  • great for development

The downside is that the model quality may differ from hosted models, and local inference requires reasonable hardware.


One important thing for our architecture

Don’t change this:

Ai::Client

The fact that OpenAI isn’t currently usable doesn’t mean we should redesign the application.

We specifically created:

Rails
Ai::Client
Provider

so that later we can switch:

Ai::Client
OpenAI

to:

Ai::Client
Anthropic

or:

Ai::Client
Ollama

without rewriting our Rails application.

That’s actually an important senior-level design lesson.


What we can do now?

Since our objective is learning AI engineering, not spending money on API calls, first check your API billing page.

If it shows:

Free trial credit remaining: $0.00

then the error is fully explained. OpenAI’s billing documentation uses exactly this sort of balance indicator. (OpenAI Help Center)

We can then decide between a small API credit or a local/free-tier provider.

For this course, I slightly prefer keeping OpenAI as the first provider so you learn the real production API flow, then later we’ll add a second provider/local model to demonstrate the abstraction properly.

4. Get the generated text

Try:

response.output_text

You should get a normal answer such as:

A Ruby block is a chunk of code that can be passed to a method...

This is the first important distinction:

response
entire API response
response.output_text
just the model's text

Don’t immediately throw away the full response. We need the metadata later.

5. Inspect the model

Try:

response.model

This tells you which model actually generated the response.

That’s relevant to our messages.model column.

6. Inspect usage

Now:

response.usage

You should see token-related information.

Inspect it:

response.usage.input_tokens

and:

response.usage.output_tokens

These are directly related to the fields we added earlier:

messages
-------------------
input_tokens
output_tokens

So our database design is now connected to a real API response.

LLM response
├── model
├── output text
└── usage
├── input_tokens
└── output_tokens

The SDK’s response models expose usage information as part of the response. (GitHub)

7. One very important experiment

Ask a second question:

response2 = client.chat(
message: "What is my name?"
)

You’ll probably notice the model doesn’t know your name from the previous request.

That’s intentional.

We made two independent requests:

Request 1
"Explain Ruby blocks"
Request 2
"What is my name?"

The LLM does not automatically receive our previous request.

This is going to become extremely important when we implement:

Conversation
Messages
Prompt Builder
LLM

Our Rails application will be responsible for providing the appropriate conversation context.

8. One thing to notice

We’ve built:

app/services/ai/client.rb

and now:

Ai::Client.new.chat(...)

works.

That’s already a valuable architectural boundary:

Rails application
Ai::Client
OpenAI SDK
OpenAI API

Our controllers won’t need to know:

  • how authentication works,
  • how the SDK works,
  • which API endpoint is used,
  • how OpenAI responses are represented.

That’s why we created the abstraction.

Check our code in this repo: https://github.com/abhilashak/ai_assistant


Stop Here

Run these commands one by one:

bin/rails c
client = Ai::Client.new
response = client.chat(
message: "Explain Ruby blocks in simple terms."
)

Then inspect:

response.output_text
response.model
response.usage
response.usage.input_tokens
response.usage.output_tokens

Don’t paste our API key or any sensitive output anywhere.

Now: “Our First LLM request works.”

Then we’ll do the next important step: inspect the raw response structure and improve Ai::Client so it returns a clean Ruby object to the rest of our Rails application.


Integrate AI with Rails: AI bootcamp for Developers – Day 4 -Practical Course – Part 2

Now let’s move to the next step: make the Message model production-friendly.

We’ll start with the most important field: role.

Step 3 – Design Message.role

Currently our database allows:

role = anything

For example:

"user"
"assistant"
"system"
"foo"
"hello"
"something-invalid"

That’s not what we want.

Our AI application has a defined set of roles:

user
assistant
system

Later, when we introduce tool calling, we may also need to represent tool messages depending on the provider/API design. But for our current application, we’ll keep the persisted roles to these three.

Why use a string instead of an integer?

You may remember our previous discussion about Rails enums.

We could store:

0 = user
1 = assistant
2 = system

But for an AI application, I prefer a string-backed enum.

Database:

role
---------
user
assistant
system

instead of:

role
---------
0
1
2

Why?

1. Database is self-describing

When you run:

SELECT role FROM messages;

you immediately see:

user
assistant
assistant
user
system

2. Easier debugging

When you’re debugging an AI conversation, the actual value is obvious.

3. Safer for external APIs

LLM APIs already use strings such as:

{
"role": "user"
}

So our database representation matches the domain.

Step 3A – Add the Rails enum

Open:

app/models/message.rb

Currently you should have something like:

class Message < ApplicationRecord
belongs_to :conversation
end

Change it to:

class Message < ApplicationRecord
belongs_to :conversation
enum :role, {
user: "user",
assistant: "assistant",
system: "system"
}, validate: true
end

Understand this carefully

This:

enum :role, {
user: "user",
assistant: "assistant",
system: "system"
}, validate: true

doesn’t mean PostgreSQL has an enum type. We’re using a Rails enum backed by a string column.

PostgreSQL still has:

role character varying

Rails gives us a domain API on top of it.

Step 3B – Test the enum

Start Rails console:

bin/rails console

Find our message:

message = Message.first

Check:

message.role

You should get:

"user"

Now:

message.user?

Expected:

true

And:

message.assistant?

Expected:

false

Step 3C – Test the scopes

Rails also gives us useful scopes.

Try:

Message.user

and:

Message.assistant

and:

Message.system

For example:

Message.user

roughly translates to:

SELECT *
FROM messages
WHERE role = 'user';

This is one of the benefits of using an enum.

Step 3D – Test invalid values

Now try:

Message.new(
conversation: Conversation.first,
role: "something_else",
content: "test"
)

Because we specified:

validate: true

Rails should treat the role as invalid.

Check:

message = Message.new(
conversation: Conversation.first,
role: "something_else",
content: "test"
)
message.valid?

Expected:

false

Then:

message.errors.full_messages

You should see an error indicating that the role is not included in the allowed values.

Why validate: true?

This is worth understanding: Without validation, Rails enum behavior can raise an ArgumentError when assigning an invalid value.

With:

validate: true

we get normal ActiveRecord validation behavior:

message.valid?
false

and:

message.errors

contains the validation error.

That’s generally more convenient when the model is receiving user/application input.

Step 3E – One more important layer: Database constraint

There is a subtle issue here.

Rails validation protects you when data enters through Rails.

But PostgreSQL doesn’t know that only these values are valid:

user
assistant
system

Someone could execute:

INSERT INTO messages (conversation_id, role, content)
VALUES (1, 'invalid', '...');

directly against PostgreSQL.

The database would currently allow it.

This leads to an important senior-engineering principle:

Application-level validation and database-level integrity are complementary.

We’ll add a database constraint.

But don’t do that yet. First make sure the Rails enum works.

After that, we’re finally ready for the exciting part:

Rails
Ai::Client
LLM API
Real AI response

Now let’s strengthen the model at the database level.

You currently have Rails validation:

enum :role, {
user: "user",
assistant: "assistant",
system: "system"
}, validate: true

That’s good, but a senior Rails application shouldn’t rely only on model validation for important data integrity.

Step 4 – Add Database Constraints

We want PostgreSQL itself to enforce:

role MUST be:
user
assistant
system

and:

content MUST NOT be NULL
role MUST NOT be NULL

This gives us two layers:

Rails
Model validation
PostgreSQL
Database constraint

4.1 Why NULL matters

Currently this is possible at the database level:

role = NULL

But an AI message without a role doesn’t make sense.

Likewise:

content = NULL

doesn’t represent a meaningful message.

So we’ll make both required.

4.2 Create a new migration

Don’t modify the old migration because it has already been executed and committed.

Generate a new migration:

bin/rails generate migration AddMessageConstraints

Rails should create:

db/migrate/XXXXXXXXXXXXXX_add_message_constraints.rb

Open that file.

4.3 Add NOT NULL constraints

Put this inside change:

class AddMessageConstraints < ActiveRecord::Migration[8.1]
def change
change_column_null :messages, :role, false
change_column_null :messages, :content, false
end
end

So conceptually:

def change
change_column_null :messages, :role, false
change_column_null :messages, :content, false
end

4.4 Add PostgreSQL CHECK constraint

Now we want PostgreSQL to enforce:

role IN ('user', 'assistant', 'system')

Add:

add_check_constraint(
:messages,
"role IN ('user', 'assistant', 'system')",
name: "messages_role_check"
)

Our migration becomes:

class AddMessageConstraints < ActiveRecord::Migration[8.1]
def change
change_column_null :messages, :role, false
change_column_null :messages, :content, false
add_check_constraint(
:messages,
"role IN ('user', 'assistant', 'system')",
name: "messages_role_check"
)
end
end

4.5 Run the migration

Execute:

bin/rails db:migrate

You should see Rails successfully applying the migration.

4.6 Inspect PostgreSQL

This is worth doing because understand what’s actually happening underneath Rails.

Run:

bin/rails dbconsole

Then:

\d messages

Look toward the bottom.

You should see a check constraint similar to:

messages_role_check
CHECK ((role)::text = ANY (...))

The exact display can vary by PostgreSQL version.

Also check:

\d+ messages

4.7 Test the database constraint

Now let’s prove that PostgreSQL protects us even if Rails is bypassed.

Inside psql, try:

INSERT INTO messages
(conversation_id, role, content, created_at, updated_at)
VALUES
(1, 'invalid', 'This should fail', NOW(), NOW());

You should get an error similar to:

ERROR: new row for relation "messages" violates check constraint "messages_role_check"

That’s exactly what we want.

The database is now protecting the data.

Why is this important?

Suppose an int. asks:

“Why do you have both Rails validation and a PostgreSQL constraint?”

A strong senior-level answer would be:

“Rails validations provide application-level feedback and are useful for normal model operations, but they’re not a database integrity guarantee because data can enter through other paths. For important invariants such as message roles, I also enforce the constraint at the PostgreSQL level.”

That’s a much stronger answer than:

“Because Rails has validations.”

4.8 One more design question: content

We’re making:

change_column_null :messages, :content, false

But should an AI message be allowed to contain an empty string?

For example:

content: ""

NOT NULL allows that.

So:

NULL NO
"" technically allowed
"Hello" YES

Whether empty content should be allowed is an application-level business rule.

We can later decide whether to add:

validates :content, presence: true

But don’t add that yet.

There are legitimate AI API situations where a message may not have ordinary text content – for example, tool-related or structured content. We’ll revisit our message representation when we implement tool calling.

4.9 Test a valid message

Exit psql:

\q

Then:

bin/rails c

Run:

conversation = Conversation.first

Then:

message = conversation.messages.create(
role: :user,
content: "What is Ruby?"
)

Check:

message.persisted?

You should get:

true

And:

message.role

should return:

"user"

Stop Here

Please do these in order:

bin/rails generate migration AddMessageConstraints

Edit the migration with the constraints above.

Then:

bin/rails db:migrate

Verify with:

bin/rails dbconsole
\d messages

Then test the invalid role directly in PostgreSQL.

Finally:

git add app/models/message.rb db/migrate
git commit -m "feat: validate message roles"
git push

NOW: “Message constraints are done.”

Then we move to the big milestone: Our First Real LLM API Call


Excellent. We now have a clean foundation:

Ruby 3.4.1
Rails 8.1
PostgreSQL
Conversation
└── Message
├── role
├── content
├── model
├── input_tokens
└── output_tokens
Ai::Client

Now we reach the first real AI step.

Step 5 – Make Our First LLM API Call

We’re going to do this in a deliberately controlled way.

Don’t build the Chat UI yet.

First, we need to understand:

Ruby
Ai::Client
HTTP request
LLM provider
HTTP response
Ruby

Once we understand this, we’ll wrap it nicely into Rails architecture.

5.1 First decision – which provider?

For this practical course, let’s start with OpenAI.

Not because you must use OpenAI in production, but because it gives us a straightforward API to understand the fundamentals.

Later we’ll discuss:

Rails
├── OpenAI
├── Anthropic
└── Gemini

and how to design our Ai::Client so that we’re not tightly coupled to one provider.

5.2 Before writing code – understand the request

Conceptually, we’re going to send something like:

POST /v1/responses
{
"model": "...",
"input": "Explain Ruby blocks in simple terms."
}

The provider’s server processes the request:

Rails
│ HTTPS
OpenAI API
LLM
Response

The important thing to understand is:

An LLM API is an HTTP API.

The Ruby SDK is just a convenient abstraction around HTTP.

5.3 Check our Ai::Client

You already created:

app/services/ai/client.rb

Open it.

If it currently contains nothing useful, that’s completely fine.

For now, make it:

# app/services/ai/client.rb

class Ai::Client
end

Don’t add API code yet.

5.4 Configure the API key securely

Do not put our API key in Ruby source code.

We have two common approaches:

Environment variables

or:

Rails encrypted credentials

For this project, I’m going to use Rails encrypted credentials because it’s a good opportunity to understand how Rails handles secrets.

5.5 Create Rails encrypted credentials

Run:

➜  ai_assistant git:(main) ✗ VISUAL="code --wait" rails credentials:edit

Rails will open our configured editor.

Add:

openai:
api_key: OUR_OPENAI_API_KEY

For example:

openai:
api_key: sk-xxxxxxxxxxxxxxxx

Use our actual API key locally, but never paste it into this conversation or commit it to GitHub.

Save and close the editor

What’s actually happening?

Rails creates/uses:

config/credentials.yml.enc

This file is encrypted.

Our encryption key is stored separately in:

config/master.key

The important rule is:

config/credentials.yml.enc
COMMIT
GitHub

is okay.

But:

config/master.key

should never be committed to GitHub.

Check:

git status

You should not see:

config/master.key

as a file to commit.

5.6 Verify Rails can read the key

Run:

bin/rails console

Then:

Rails.application.credentials.dig(:openai, :api_key)

You should get our key back, just verify that it returns a string rather than nil.

Then:

exit

5.7 Why use dig?

Our credentials structure is:

openai:
api_key: ...

which Rails exposes approximately as:

{
openai: {
api_key: "..."
}
}

So:

Rails.application.credentials.dig(:openai, :api_key)

means:

credentials
openai
api_key

This is cleaner than accessing nested values manually.

5.8 Now configure Ai::Client

Open:

app/services/ai/client.rb

Change it to:

class Ai::Client
def initialize
@api_key = Rails.application.credentials.dig(:openai, :api_key)
end
end

Now the client knows how to retrieve its secret.

5.9 Add a safety check

We don’t want the application to fail mysteriously later.

Add:

class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?
  end
end

Now:

Ai::Client.new

will fail immediately if the key isn’t configured. This is called fail-fast configuration.

5.10 Test the client

Run:

bin/rails console

Then:

client = Ai::Client.new

If everything is configured correctly, it should return:

#<Ai::Client:0x...>

No API request has happened yet.

We’re only testing:

Rails credentials
Ai::Client

Check our code in this repo: https://github.com/abhilashak/ai_assistant


Stop Here

Don’t make the API request yet.

complete only these steps first:

1. Configure credentials

bin/rails credentials:edit

with:

openai:
api_key: OUR_KEY

2. Verify:

bin/rails console
Rails.application.credentials.dig(:openai, :api_key)

Don’t show me the key.

3. Update:

app/services/ai/client.rb

to:

class Ai::Client
def initialize
@api_key = Rails.application.credentials.dig(:openai, :api_key)
raise "OpenAI API key is missing" if @api_key.blank?
end
end

4. Test:

client = Ai::Client.new

Now: “Ai::Client credentials is done.”

Next topic: Step 5.11: install/configure the OpenAI Ruby client and make the first actual LLM request.

to be continued ..

Integrate AI with Rails: AI bootcamp for Developers – Day 4 -Practical Course – Part 1

For a Senior Rails developer, simply knowing what RAG, LLM, Agents, and embeddings mean is not enough. In an int., you may be asked:

“Okay, let’s build an AI feature in Rails. How would you structure it?”

You should be able to open your laptop and actually build one.

So let’s turn Day 4 into a hands-on mini-project in this blog that we’ll build incrementally. We won’t rush through the whole application in one answer.

Build an AI Application with Ruby on Rails

Project: AI Chat Assistant

We’re going to build a real Rails application that evolves throughout this course.

The final architecture will look approximately like this:

                         ┌──────────────────┐
│ Browser │
│ Chat UI │
└────────┬─────────┘


┌──────────────────┐
│ Rails Controller │
└────────┬─────────┘


┌──────────────────┐
│ Chat Service │
└────────┬─────────┘

┌────────────┴────────────┐
▼ ▼
Conversation Prompt Builder
DB │

┌──────────────────┐
│ AI Client │
└────────┬─────────┘


┌──────────────────┐
│ LLM │
│ OpenAI / Claude │
└────────┬─────────┘


Response Formatter


Rails / Browser

And later we’ll evolve it into:

                         AI Rails Application

┌──────────────────────────┼──────────────────────────┐
│ │ │
▼ ▼ ▼
Chat RAG Agents
│ │ │
▼ ▼ ▼
LLM API pgvector Tools
│ │
▼ ▼
Documents Business APIs

That will give you practical experience across LLM → RAG → Agents.


What We Are Going to Build

Our application will start simple.

Version 1

User
Rails
LLM API
Response

Then we’ll progressively add:

Version 2

Conversation
├── User message
├── Assistant response
├── User message
└── Assistant response

Version 3

Streaming:

LLM
token
token
token
Browser

Version 4

Production architecture:

Controller
Chat Service
Prompt Builder
AI Client
Provider

Version 5

RAG:

Question
Embedding
pgvector
Relevant Documents
Prompt
LLM

Version 6

Agent:

User
Agent
├── Search Product
├── Find Order
├── Search Documentation
└── Create Support Ticket

This is why I recommend we build one application throughout the AI bootcamp, rather than writing isolated examples.


Practical Course Roadmap

We’ll divide the practical Day 4 into 10 stages.

StageWhat we’ll buildMain skill
1Rails project setupAI Rails environment
2First LLM requestLLM API
3AI service objectRails architecture
4Chat UIRails frontend
5Conversation persistencePostgreSQL
6Prompt BuilderPrompt architecture
7StreamingReal-time AI UX
8Error handling & retriesProduction engineering
9TestingAI application testing
10Production architectureSenior-level system design

Then Day 5 can build on this application to introduce agents.


Stage 1 – Create the Rails Application

We’ll use:

  • Ruby
  • Rails
  • PostgreSQL
  • OpenAI API initially
  • RSpec/Minitest depending on your preference
  • dotenv/credentials for secrets
  • Turbo/Stimulus where useful

The important thing is:

We won’t use a huge AI framework initially.

I want you to understand what is actually happening underneath.

Later we can compare this approach with Ruby AI libraries/frameworks.

Step 1 – Create Rails App

Assuming Rails is installed:

rails new ai_assistant -d postgresql

Move into the application:

cd ai_assistant

Create database:

bin/rails db:create

Run it:

bin/rails server

Then open:

http://localhost:3000

At this point:

Browser
Rails
PostgreSQL

works.

No AI yet.

Why Start This Way?

This is important for ints.

We don’t want to hide everything behind an AI gem.

You need to understand:

HTTP Request
Rails
Ruby
HTTP Client
AI Provider

Once you understand this, an SDK becomes just an abstraction.


Stage 2 – Configure AI Credentials

Never do this:

api_key = "sk-xxxxx"

Never commit API keys to Git.

We’ll use Rails credentials or environment variables.

Conceptually:

Rails Application
Configuration
OPENAI_API_KEY

For local development, we’ll configure the key securely.


Stage 3- Make Your First LLM Request

This is our first major milestone.

We’ll create:

app/
└── services/
└── ai/
└── client.rb

Initially:

class Ai::Client
def initialize
...
end
def chat(messages:)
...
end
end

Then:

client = Ai::Client.new
response = client.chat(
messages: [
{
role: "user",
content: "Explain Ruby blocks in simple terms"
}
]
)

And eventually:

Ruby
Ai::Client
OpenAI API
LLM
JSON Response
Ruby

This is the most important practical exercise of Day 4.

You will see exactly what an LLM API actually returns.


Stage 4 – Understand the Raw API Response

We’re not immediately going to hide the response.

We’ll inspect things like:

response
├── id
├── model
├── choices
│ └── message
│ ├── role
│ └── content
└── usage
├── input tokens
└── output tokens

This connects directly with Day 1.

Remember:

Tokens
Cost
Latency
Context

You’ll actually see token usage in a real application.


Stage 5 – Build the Rails Chat Application

Now we’ll create:

User
Chat page
POST /conversations/:id/messages
Rails Controller
AI Service
LLM
Response
Browser

We’ll create models such as:

User
Conversation
Message

A conversation:

Conversation
├── Message
│ role: user
│ content: "What is Ruby?"
├── Message
│ role: assistant
│ content: "Ruby is..."
├── Message
│ role: user
│ content: "Who created it?"
└── Message
role: assistant
content: "Yukihiro Matsumoto..."

Stage 6 – Database Design

We’ll design this properly rather than putting everything into one table.

For example:

conversations
-----------------
id
user_id
title
created_at
updated_at

and:

messages
-----------------
id
conversation_id
role
content
model
input_tokens
output_tokens
created_at

Potentially later:

total_tokens
latency_ms
finish_reason

Now you’re thinking like a senior engineer.


Stage 7 – Build Conversation Context

This is where you’ll see something very important.

The LLM doesn’t automatically remember our database conversation.

If we have:

User:
My name is Abhilash.
Assistant:
Nice to meet you.
User:
What's my name?

Rails must send appropriate history back to the LLM:

[
{
role: "user",
content: "My name is Abhi."
},
{
role: "assistant",
content: "Nice to meet you."
},
{
role: "user",
content: "What's my name?"
}
]

Therefore:

Your Rails application manages conversation memory.

This is a very important int. concept.


Stage 8 – Prompt Builder

Eventually we don’t want:

messages = [
...
]

scattered everywhere.

We’ll create:

Ai::PromptBuilder

Architecture:

Conversation
Prompt Builder
System Prompt
+
Conversation History
+
Current User Message
LLM

For example:

Ai::PromptBuilder.new(
conversation: conversation,
user_message: message
).build

This is where your Rails architecture skills become important.


Stage 9 – Streaming

After normal request/response works, we’ll make it feel like ChatGPT.

Instead of:

User
[wait 5 seconds]
↓ Complete response

we’ll have:

User
Rails
LLM
"Ruby"
" is"
" a"
" programming"
" language"

The browser updates progressively.

We’ll investigate Rails approaches such as:

SSE
Turbo Streams
Action Cable

And we’ll discuss when each is appropriate.


Stage 10 – Production Concerns

Then we’ll deliberately break our application.

We’ll simulate:

LLM timeout
LLM rate limit
Invalid response
API unavailable
Malformed JSON

We’ll build:

Ai::Client
├── timeout
├── retry
├── rate limit
└── provider error

We’ll also add:

Authentication
Authorization
Rate limiting
Logging
Token tracking
Cost tracking

This is where my 15 years of backend experience can help.


Stage 11 – Testing

We’ll write tests around:

Ai::Client

Does it call the provider?
Does it handle errors?
Does it parse the response?

Ai::PromptBuilder

Does it create the correct messages?
Does it include conversation history?

Ai::ChatService

Does it save the user message?
Does it call the AI?
Does it save the response?

We’ll mock the external AI service.

The tests should not depend on a live LLM API.


Final Day 4 Application

At the end of the practical course, you’ll have something approximately like:

                         Browser


┌───────────────┐
│ Chat UI │
└───────┬───────┘


┌───────────────┐
│ Controller │
└───────┬───────┘


┌───────────────┐
│ Chat Service │
└───────┬───────┘

┌─────────┴─────────┐
▼ ▼
┌──────────────┐ ┌──────────────┐
│ Conversation │ │Prompt Builder│
│ PostgreSQL │ └──────┬───────┘
└──────────────┘ │

┌──────────────┐
│ AI Client │
└──────┬───────┘


┌──────────────┐
│ LLM │
└──────┬───────┘


Response


Browser

But We Won’t Stop There

This application will become our AI laboratory for the remaining bootcamp.

Day 5

We’ll add:

AI Agent
├── Product Search Tool
├── Order Lookup Tool
└── Documentation Search Tool

Day 6

We’ll add:

RAG
Documents
Chunks
Embeddings
pgvector
Semantic Search
LLM

and discuss production concerns.

Day 7

We’ll turn everything into:

                         AI Rails Application

┌───────────────────┼───────────────────┐
│ │ │
▼ ▼ ▼
LLM RAG Agent
│ │ │
▼ ▼ ▼
Prompting pgvector Tools
│ │ │
└───────────────────┼───────────────────┘

Production System

Then we’ll do AI int. questions + AI system design + coding exercises.


How I Suggest We Learn Each Stage

This is important.

I don’t want to dump 500 lines of Rails code on you.

For every stage, we’ll follow:

1. Understand

I’ll explain:

What are we building?

2. Why

Why do we need this architecture?

3. Build

We’ll create the files/commands one at a time.

4. Run

You’ll execute it on your Mac.

5. Inspect

We’ll look at:

Rails logs
HTTP requests
API responses
PostgreSQL records
LLM responses
Token usage

6. Break it

I’ll give you scenarios such as:

What happens if the AI provider times out?

You solve it.

7. Questions

We’ll turn what you just built into question / answers.

This is particularly important for you because your objective isn’t merely to build an AI app – it’s to be able to explain the architecture during a senior-level discussions.


Our Practical Course

So I suggest we proceed in this exact order:

DAY 4 PRACTICAL
Part 1
├── 1. Create Rails app
├── 2. Configure AI API credentials
├── 3. Make first LLM API request
├── 4. Inspect raw response
├── 5. Build Ai::Client
├── 6. Build Chat UI
├── 7. Conversation + Message models
├── 8. Build Ai::ChatService
├── 9. Build PromptBuilder
├── 10. Conversation memory
├── 11. Streaming
├── 12. Error handling
├── 13. Token/cost tracking
├── 14. Security
├── 15. Tests
└── 16. Production architecture

Start Here: Part 1

Your first assignment is simply to create the application.

On your Mac:

ruby -v
rails -v
psql --version

Then:

rails new ai_assistant -d postgresql
cd ai_assistant
bin/rails db:create
bin/rails server

Verify:

http://localhost:3000

Once that works, don’t start building anything else yet.

Since we’ve already created:

app/services/ai/client.rb

we’ll now build the database layer.

For now, don’t create all models at once. We’ll create one model, migrate it, inspect the database, understand why we designed it this way, and only then move to the next model.


Part 1 – Create Conversation

Our AI application needs to remember conversations.

Think of ChatGPT:

Conversation
├── User message
├── AI response
├── User message
└── AI response

So we’ll have two main models:

Conversation
└── has_many :messages

and later:

Message
└── belongs_to :conversation

For the moment, we’ll create only Conversation.


Step 1 – Check your current directory

From your Rails application’s root:

pwd

You should be somewhere like:

.../ai_assistant

Then:

ls

You should see something similar to:

Gemfile
Gemfile.lock
app
config
db
lib
public
...

If you’re already in your ai_assistant directory, continue.


Step 2 – Generate the Conversation model

Run:

bin/rails generate model Conversation title:string

You can also use:

bin/rails g model Conversation title:string

Both commands do the same thing.

Rails should generate something similar to:

invoke active_record
create db/migrate/XXXXXXXXXXXXXX_create_conversations.rb
create app/models/conversation.rb

Step 3 – Understand what Rails created

Open:

app/models/conversation.rb

You’ll initially see:

class Conversation < ApplicationRecord
end

At this point, the model doesn’t have any associations.

That’s okay.


Step 4 – Inspect the migration

Open:

db/migrate/XXXXXXXXXXXXXX_create_conversations.rb

You’ll see something like:

class CreateConversations < ActiveRecord::Migration[8.1]
def change
create_table :conversations do |t|
t.string :title
t.timestamps
end
end
end

The exact Rails migration version will depend on your Rails version.

What does this mean?

Rails is asking PostgreSQL to create approximately:

conversations
-------------------------
id
title
created_at
updated_at

Step 5 – Run the migration

Now execute:

bin/rails db:migrate

You should see something similar to:

== ... CreateConversations: migrating =====================
-- create_table(:conversations)
-> 0.00xxs
== ... CreateConversations: migrated ======================

Now the table exists in PostgreSQL.


Step 6 – Verify using Rails

Open Rails console:

bin/rails console

or:

bin/rails c

Then:

Conversation

You should get:

Conversation (call 'Conversation.connection' to establish a connection)

Now:

Conversation.column_names

You should see something similar to:

[
"id",
"title",
"created_at",
"updated_at"
]

This is a good habit for you as a senior Rails developer:

Don’t blindly trust generated migrations. Inspect what Rails actually created.


Step 7 – Create a Conversation

Still inside Rails console:

conversation = Conversation.create(title: "My first AI conversation")

You should get something like:

#<Conversation id: 1, title: "My first AI conversation", ...>

Now:

conversation.id

You should get:

1

And:

Conversation.all

should return your conversation.


Step 8 – Check PostgreSQL directly

This is particularly useful for your int. preparation because I want you to understand both Rails and the database underneath it.

Exit Rails console:

exit

Then connect to your database:

bin/rails dbconsole

You’ll enter psql.

Run:

\d conversations

You should see something approximately like:

Column | Type
-------------+--------------------------
id | bigint
title | character varying
created_at | timestamp
updated_at | timestamp

Then:

SELECT * FROM conversations;

You should see your test conversation.

Exit:

\q

Why are we starting with Conversation?

Eventually our application will look like:

Conversation
│ has_many
Messages
├── user
├── assistant
├── user
└── assistant

For example:

Conversation #1
Title: Ruby Question
Message #1
role: user
content: "What is a Ruby block?"
Message #2
role: assistant
content: "A Ruby block is..."
Message #3
role: user
content: "Can you give me an example?"
Message #4
role: assistant
content: "Sure..."

The Conversation represents the container, while Message represents each individual interaction.


One Important Design Decision

You may notice that our earlier architecture discussed:

Conversation
user_id
title

We’re deliberately not adding user_id yet.

Why?

Your newly created Rails app may not have an authentication/User model yet.

We don’t want to introduce Devise/authentication just to learn AI.

We’ll first make the AI application work.

Later we can add:

User
└── has_many :conversations

That keeps today’s exercise focused.


Your Current State

You should now have:

app/
├── models/
│ └── conversation.rb
└── services/
└── ai/
└── client.rb
db/
└── migrate/
└── XXXXX_create_conversations.rb

And PostgreSQL:

conversations
-------------------------
id
title
created_at
updated_at

Stop Here

Don’t create Message yet.

First execute these steps:

bin/rails g model Conversation title:string
bin/rails db:migrate
bin/rails c

Then inside Rails console:

Conversation.column_names

and:

conversation = Conversation.create(title: "My first AI conversation")

Then verify:

Conversation.all

Now Our “Conversation model is done.”

Next step: create the Message model and I’ll explain why role, content, model and token-related columns belong there.

Now I’ll create the Message model. This is the most important model in our AI chat application because it represents the actual conversation between the user and the LLM.

Step 2 – Create the Message model

Our structure will become:

Conversation
├── Message
├── Message
├── Message
└── Message

For example:

Conversation #1
├── User → "What is Ruby?"
├── Assistant → "Ruby is a programming language..."
├── User → "Who created it?"
└── Assistant → "Ruby was created by..."

The Message table needs to know:

  • which conversation it belongs to
  • who/what produced it (user or assistant)
  • the actual message
  • which AI model generated the response
  • token usage, which we’ll use later for cost tracking

Step 1 – Generate the model

From your Rails application’s root directory:

bin/rails generate model Message \
conversation:references \
role:string \
content:text \
model:string \
input_tokens:integer \
output_tokens:integer

You can also write it as one line:

bin/rails g model Message conversation:references role:string content:text model:string input_tokens:integer output_tokens:integer

Rails should generate:

app/models/message.rb
db/migrate/XXXXXXXXXXXXXX_create_messages.rb

Step 2 – Inspect the generated migration

Open:

db/migrate/XXXXXXXXXXXXXX_create_messages.rb

You’ll see something similar to:

class CreateMessages < ActiveRecord::Migration[8.0]
def change
create_table :messages do |t|
t.references :conversation, null: false, foreign_key: true
t.string :role
t.text :content
t.string :model
t.integer :input_tokens
t.integer :output_tokens
t.timestamps
end
end
end

Your Rails migration version may differ.

Understand conversation:references

This is important.

When we wrote:

conversation:references

Rails generated:

t.references :conversation, null: false, foreign_key: true

This creates:

conversation_id

in the messages table.

So our database relationship becomes:

conversations
----------------
id
title
messages
----------------
id
conversation_id
role
content
model
input_tokens
output_tokens
created_at
updated_at

The important connection is:

messages.conversation_id
conversations.id

That’s a standard relational database foreign key.

Step 3 – Run the migration

Execute:

bin/rails db:migrate

You should see something like:

== CreateMessages: migrating ===============================
-- create_table(:messages)
-> ...
== CreateMessages: migrated ================================

Now PostgreSQL has the messages table.

Step 4 – Inspect PostgreSQL

Let’s verify what actually happened.

Run:

bin/rails dbconsole

Then:

\d messages

You should see something approximately like:

Column | Type
----------------+--------------------------
id | bigint
conversation_id | bigint
role | character varying
content | text
model | character varying
input_tokens | integer
output_tokens | integer
created_at | timestamp
updated_at | timestamp

And importantly, you’ll see a foreign key from:

conversation_id

to:

conversations.id

You can also run:

SELECT * FROM messages;

Currently there should be no records.

Exit:

\q

Step 5 – Inspect the generated Rails model

Open:

app/models/message.rb

Rails should have generated:

class Message < ApplicationRecord
belongs_to :conversation
end

Rails automatically added:

belongs_to :conversation

because we used:

conversation:references

Now we need the other side of the relationship.

Step 6 – Add has_many to Conversation

Open:

app/models/conversation.rb

Currently it probably looks like:

class Conversation < ApplicationRecord
end

Change it to:

class Conversation < ApplicationRecord
has_many :messages, dependent: :destroy
end

Now our Rails relationship is:

Conversation
│ has_many
Messages

and:

Message
│ belongs_to
Conversation

Step 7 – Test the association

Open Rails console:

bin/rails console

First find your conversation:

conversation = Conversation.first

Then:

conversation.messages

It should return:

[]

because we haven’t created any messages yet.

Now create a user message:

message = conversation.messages.create(
role: "user",
content: "What is Ruby?"
)

Now:

message

You should get something similar to:

#<Message
id: 1,
conversation_id: 1,
role: "user",
content: "What is Ruby?",
...
>

Step 8 – Check the relationship

Now run:

conversation.messages

You should see your message.

And:

message.conversation

should return the conversation.

This demonstrates the two-way ActiveRecord relationship:

conversation.messages
Message
message.conversation
Conversation

Why do we need role?

This is extremely important for an AI application.

The LLM needs to distinguish between:

user
assistant
system

For example:

{
role: "user",
content: "What is Ruby?"
}

and:

{
role: "assistant",
content: "Ruby is a programming language..."
}

Later, Rails will retrieve these database records and transform them into the messages we send to the LLM.

So:

PostgreSQL
Message
role = "user"
content = "What is Ruby?"
Rails transforms it
LLM API
{
role: "user",
content: "What is Ruby?"
}

This is the bridge between our database and the LLM API.

Why model?

Suppose today we use one model:

some-current-model

Later we change to another model.

We want to know which model generated each response.

For example:

Message #1
model = model-A
Message #2
model = model-B

This becomes valuable for:

  • debugging
  • cost analysis
  • performance analysis
  • comparing models
  • auditing

We don’t need to populate it for user messages.

Why input_tokens and output_tokens?

Remember Day 1?

Input tokens
+
Output tokens
=
Usage

Suppose an AI response used:

input_tokens = 500
output_tokens = 200

We can store that information.

Later we can calculate:

How much did this conversation cost?
How much did this user cost?
Which model is expensive?
Which endpoint consumes the most tokens?

This is exactly the kind of thing you should do in a senior-level AI system design.

One thing we’re deliberately NOT doing yet

You may wonder:

Why don’t we add validations for role?

For example:

validates :role, inclusion: {
in: %w[user assistant system]
}

We’re going to discuss this next.

There is an interesting design question here:

Should role be a Ruby enum?

For example:

enum :role, {
user: "user",
assistant: "assistant",
system: "system"
}

We’ll discuss why a string enum is useful here, what gets stored in PostgreSQL, and what tradeoffs exist before finalising the model.

Our Current Database

After completing this step, you should have:

conversations
-------------------------
id
title
created_at
updated_at
│ 1 → many
messages
-------------------------
id
conversation_id
role
content
model
input_tokens
output_tokens
created_at
updated_at

And Rails:

class Conversation < ApplicationRecord
has_many :messages, dependent: :destroy
end
class Message < ApplicationRecord
belongs_to :conversation
end

Stop Here

Please execute only these steps now:

bin/rails g model Message conversation:references role:string content:text model:string input_tokens:integer output_tokens:integer
bin/rails db:migrate
bin/rails console

Then test:

conversation = Conversation.first
message = conversation.messages.create(
role: "user",
content: "What is Ruby?"
)
conversation.messages
message.conversation

Now Our “Message model done.”

Next step: properly design Message.role and validations, and after that we’ll make our first real LLM API call through your Ai::Client.

to be continued..

Learn AI with Rails: AI Bootcamp for Developers – Building AI Applications in Ruby on Rails – Day 4

Up to now:

  • Day 1: What is AI, LLM, Tokens, Context Window
  • Day 2: Prompt Engineering, APIs, Tool Calling
  • Day 3: RAG, Embeddings, Vector Databases

Now we’ll answer the question:

“How would you integrate AI into a Ruby on Rails application?”

Goal

By the end of today, you should be able to answer:

  • How should AI code be organized in Rails?
  • Which Ruby gems should I use?
  • Where should prompts live?
  • How should conversations be stored?
  • How should streaming work?
  • Where should Sidekiq be used?
  • How should errors be handled?
  • How do we control AI costs?
  • What architecture would you use in production?

Part 1 – AI is Just Another External Service

One of the biggest mindset shifts is this:

Treat an LLM exactly like any other external service.

You’ve probably integrated:

  • Stripe
  • Twilio
  • AWS S3
  • SendGrid
  • Google Maps

AI providers are similar.

Rails
AI Service Object
OpenAI / Anthropic / Gemini
Response

The LLM should never become your application’s business logic.


Part 2 – High-Level Architecture

A production Rails application might look like:

Browser
ChatsController
Ai::ChatService
PromptBuilder
LLM Client
LLM API
ResponseFormatter
Browser

Notice how each class has a single responsibility.


Part 3 – Recommended Folder Structure

A clean structure could look like:

app/
controllers/
chats_controller.rb
services/
ai/
chat_service.rb
prompt_builder.rb
response_formatter.rb
embedding_service.rb
moderation_service.rb
jobs/
ai_response_job.rb
embedding_job.rb
models/
conversation.rb
message.rb

Avoid putting AI logic directly in controllers.


Part 4 – Service Objects

Bad:

class ChatsController < ApplicationController
def create
# 300 lines
# prompt
# API call
# parse JSON
# save db
# stream response
end
end

Good:

class ChatsController < ApplicationController
def create
response =
Ai::ChatService.new(
current_user
).reply(params[:message])
render json: response
end
end

Everything else belongs inside the service layer.


Part 5 – Prompt Builder Pattern

Don’t concatenate strings all over the application.

Bad

prompt =
"You are..." +
params[:message] +
"..."

Better

Ai::PromptBuilder.new(
user: current_user,
message: params[:message]
).build

Why?

Because prompts evolve.

Keeping them centralized makes testing and maintenance much easier.

Answer

Prompts should be generated by dedicated classes or templates rather than being embedded in controllers.


Part 6 – LLM Client Wrapper

Never call the provider SDK from multiple places.

Instead:

Ai::Client

Example:

client.chat(messages)
client.embed(text)
client.moderate(text)

If your company later switches providers, only this layer needs to change.


Why This Matters

Imagine:

Today

Rails
OpenAI

Next year

Rails
Anthropic

If you’ve wrapped the provider behind Ai::Client, the rest of the application barely changes.


Part 7 – Conversation Storage

Should you store conversations?

Usually, yes.

Typical schema:

Conversation
id
user_id
Message
conversation_id
role
content
token_count
model
created_at

Why store them?

  • Resume chats
  • Analytics
  • Auditing
  • Cost tracking
  • User history

Part 8 – Streaming

Modern AI applications stream responses.

Instead of:

Waiting...
Waiting...
Entire response

Users see:

Hel
Hello
Hello Abhi
Hello Abhi,

Rails options:

  • Turbo Streams
  • Action Cable
  • Server-Sent Events (SSE)

tip:

Streaming improves perceived responsiveness and user experience.


Part 9 – Where Sidekiq Fits

Not every AI request should happen synchronously.

Good candidates:

  • PDF indexing
  • Embedding generation
  • Large summaries
  • Batch document processing
  • Scheduled AI reports
  • Email generation

Example:

User uploads PDF
Rails
Sidekiq
Extract
Chunk
Embeddings
pgvector

This keeps request latency low.


Part 10 – Error Handling

AI APIs can fail.

Examples:

  • Timeout
  • Rate limit
  • Invalid API key
  • Network failure
  • Provider outage

Don’t expose raw errors.

Bad:

HTTP 500
Internal Server Error

Better:

The AI service is temporarily unavailable.
Please try again shortly.

Retry transient failures where appropriate, but avoid retrying indefinitely.


Part 11 – Cost Optimization

This is increasingly asked in senior ints.

Every request costs money.

Strategies:

Cache repeated responses

Same question.

Same answer.

No need to regenerate every time if appropriate for the use case.

Choose the right model

Simple spelling correction?

Use a smaller, cheaper model.

Complex legal reasoning?

Use a more capable model.

Limit Conversation History

Don’t always send 200 previous messages.

Summarize older context when needed.

Stream

Streaming doesn’t reduce token costs, but it improves user experience.

Background Processing

Large AI tasks shouldn’t block web requests.

Part 12 – Security

Never trust AI output blindly.

Consider:

  • Prompt injection
  • User permissions
  • Sensitive data
  • PII
  • Secrets
  • Output validation

Example:

Suppose an AI suggests:

DROP TABLE users;

Your application should never execute generated SQL automatically.

AI output should be treated like any other untrusted input.


Part 13 – Logging

Useful things to log:

  • Model used
  • Response time
  • Token usage
  • API cost
  • Errors
  • Retry count

Avoid logging sensitive prompts or user data unless your privacy requirements allow it.


Part 14 – Monitoring

Production systems should track:

  • latency
  • token usage
  • failures
  • rate limits
  • provider availability
  • cost trends

Ints appreciate developers who think beyond implementation.


Part 15 – Testing AI Code

This surprises many developers.

Don’t write tests like:

expect(response)
.to eq(...)

LLM output isn’t deterministic.

Instead:

Test:

  • service objects
  • prompt builder
  • JSON parsing
  • fallback behaviour
  • tool invocation
  • retries
  • error handling

Stub the AI provider in unit tests.

Rails Example

allow(ai_client)
.to receive(:chat)
.and_return(mock_response)

Test your code – not the provider’s model.


Part 16 – Complete Production Architecture

Notice:

Rails orchestrates everything.

The LLM is just one component.

Questions

Practice answering these.

Architecture

  1. Where should AI code live?
  2. Why use service objects?
  3. Why create an AI client wrapper?

Rails

  1. Should prompts live inside controllers?
  2. How should conversations be stored?
  3. Where would Sidekiq fit?

Production

  1. How do you reduce AI costs?
  2. How would you monitor an AI service?
  3. How should AI failures be handled?
  4. How should AI code be tested?

System Design

  1. Design an AI chat architecture.
  2. How would you support multiple AI providers?
  3. How would you stream responses?
  4. How would you secure AI endpoints?

Practical Exercise 1 – Design a Service Layer

Imagine you’re adding an AI feature to an existing Rails e-commerce application.

Sketch service classes such as:

Ai::ChatService
Ai::PromptBuilder
Ai::Client
Ai::OrderAssistant
Ai::RecommendationService

For each class, define its single responsibility.


Practical Exercise 2 – Design Your Database

Design tables for:

users
conversations
messages

Ask yourself:

  • Should token usage be stored?
  • Should the model name be stored?
  • How will you calculate costs later?

Practical Exercise 3 – Failure Scenarios

Suppose the AI provider:

  • returns a timeout,
  • returns invalid JSON,
  • hits a rate limit,
  • is temporarily unavailable.

For each scenario, decide:

  • Should the request be retried?
  • Should it fail fast?
  • What should the user see?
  • What should be logged?

Thinking through these operational details is a hallmark of senior engineering.


Homework

  1. Draw the full Rails AI architecture from memory.
  2. Explain why AI belongs behind service objects.
  3. Explain why an Ai::Client abstraction is valuable.
  4. Design a conversation schema.
  5. Explain how you would reduce token costs.
  6. Describe how you would test AI features without depending on live API calls.
  7. Answer all 14 questions aloud.

Senior System Design Challenge

Imagine this question:

“Build ChatGPT inside a Rails application.”

A strong answer would cover:

  • Authentication and authorization
  • Conversation and message storage
  • Prompt builder
  • AI client abstraction
  • Streaming responses
  • Background jobs for long-running tasks
  • Rate limiting
  • Caching
  • Monitoring and observability
  • Retry policies
  • Cost tracking
  • Security (prompt injection, access control, PII handling)
  • Multi-provider support (OpenAI, Anthropic, Gemini)
  • Testing strategy

Notice that only one piece of this architecture is the LLM itself. The rest is the kind of software engineering expertise expected from a senior Rails developer.


Day 5 Preview – AI Agents

The next topic is one of the fastest-growing areas in AI.

We’ll answer questions such as:

  • What exactly is an AI Agent?
  • How is an agent different from ChatGPT?
  • What is an agentic workflow?
  • What are tools?
  • What is agent memory?
  • What is planning?
  • When do you need an agent versus a simple LLM call?
  • How do you build an agent in a Rails application?
  • How can an agent interact safely with your business logic?

By the end of Day 5, you’ll understand the concepts behind agent-based systems and be able to discuss and design simple AI agents confidently in Rails ints.

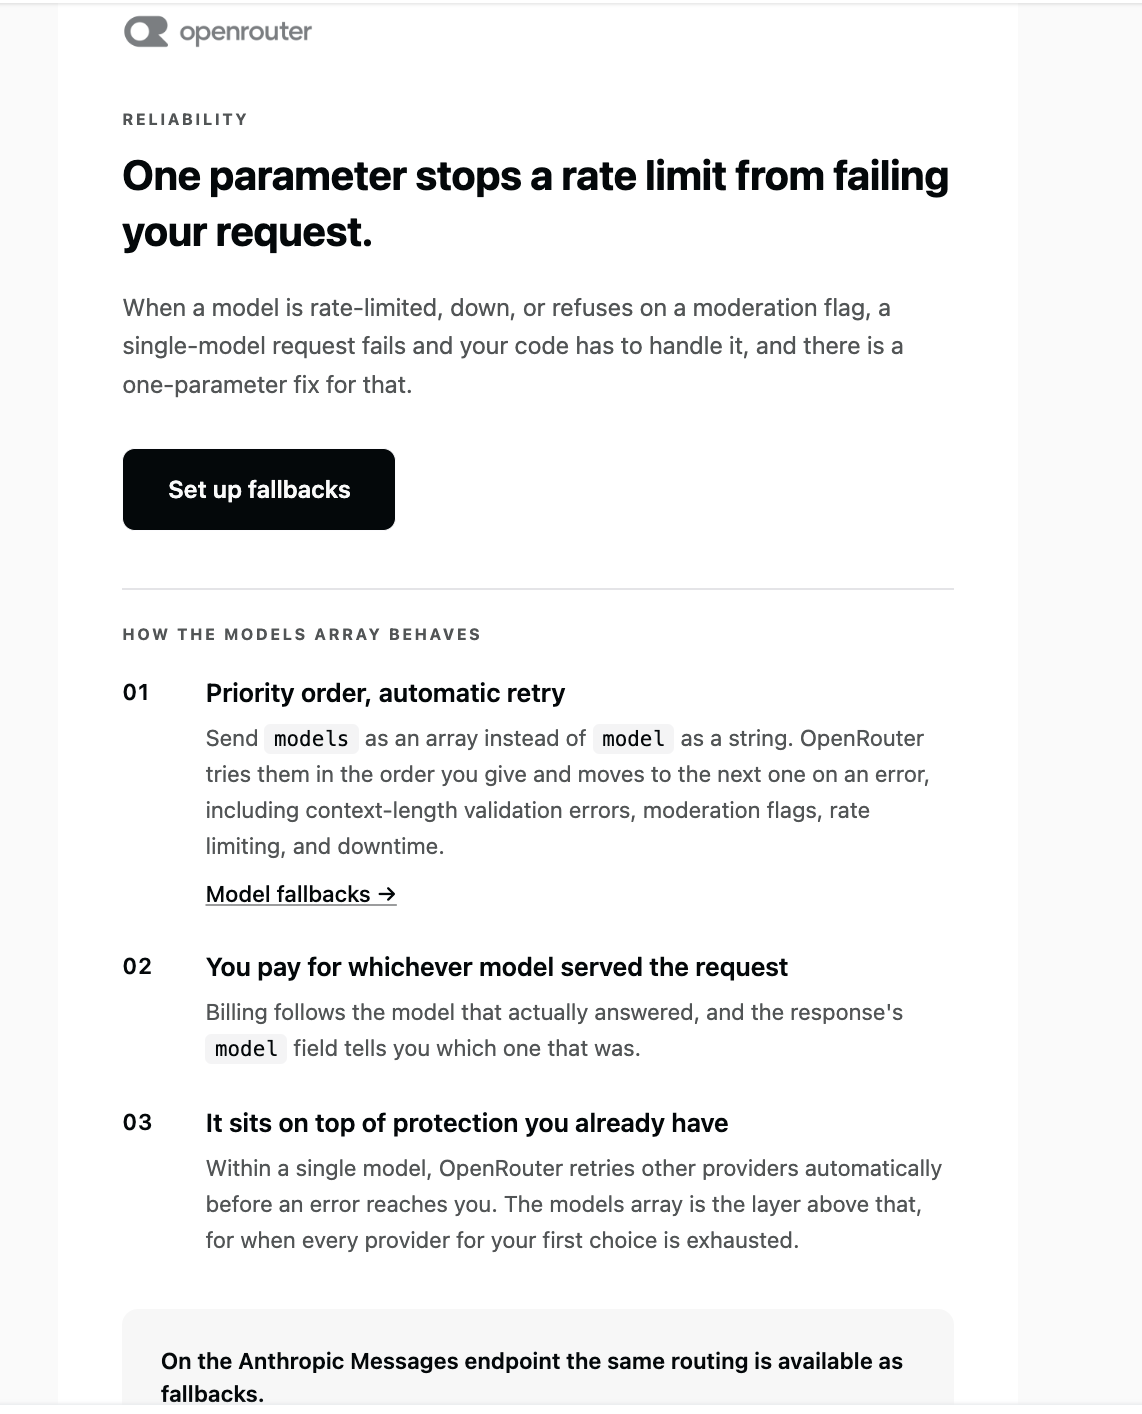
Happy AI Learning!