Before building Task CRUD endpoints, let’s establish our API structure and see how Rails handles HTTP requests.
One important decision: We’ll implement JWT authentication before exposing task data. I don’t want us to build an endpoint that returns every user’s tasks and later re-fit authorization.
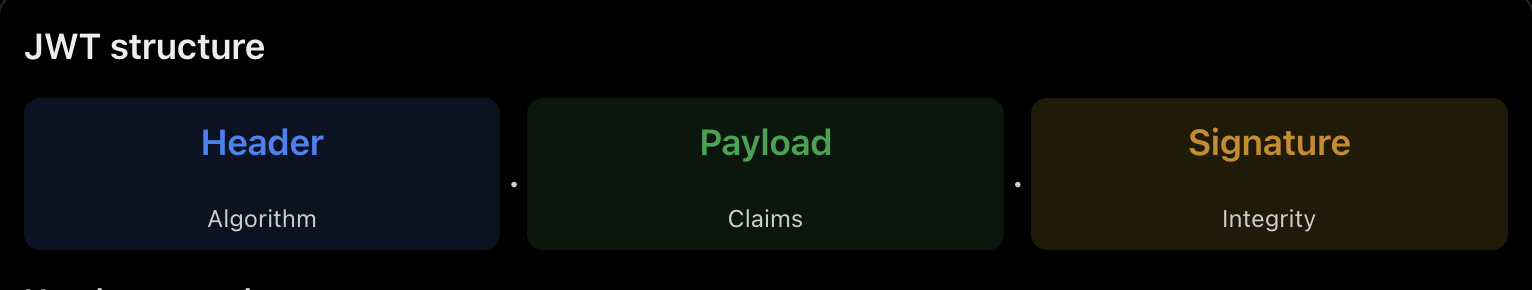
Signature: Generated using the encoded header, encoded payload and signing secret. It allows Rails to detect token modification.
The complete token looks like: xxxxx.yyyyy.zzzzz
Each part is Base64URL encoded, and the signature is cryptographically generated.
Important: JWT is not encrypted by default. Anyone who obtains a JWT can decode its header and payload. The signature protects integrity, not confidentiality. Never put passwords or sensitive personal information in the payload.
Understand the claims we will use
Claims are the information carried inside the JWT payload.
Claim
Meaning
Our usage
sub
Subject
User ID
iss
Issuer
Our Rails API
aud
Audience
Our React application
iat
Issued at
Token creation time
exp
Expiration
Token expiry
jti
JWT ID
Unique token identifier
Two important concepts:
sub– Subject – Identifies the user associated with the token.
We’ll use: { "sub": "42" }
When Rails receives the token, it can identify user ID 42 after verifying the signature.
exp– Expiration – Defines when the access token expires.
Our initial policy:
10 min – Access token lifetime – Short-lived JWT
7 days – Refresh session lifetime – Initial policy, configurable
We’ll implement refresh-token expiration and rotation separately.
Which signing algorithm should we use?
We’ll start with HS256.
Algorithm
Description
HS256
HMAC using SHA-256 and a shared secret
RS256
RSA with SHA-256, using private/public keys
ES256
ECDSA with SHA-256
Why HS256?
Our architecture currently has one Rails application that both generates and verifies tokens.
Rails has the signing secret.
Rails verifies signatures using the same secret.
We don’t need public/private key infrastructure yet.
One security rule: the verification algorithm must be explicitly allowlisted. Never trust the alg value supplied in an unverified token header to choose the verification algorithm.
Q) Why use JWT? How we trust the JWT payload/header? JWT vs Opaque token
Now let’s start building our actual Rails application.
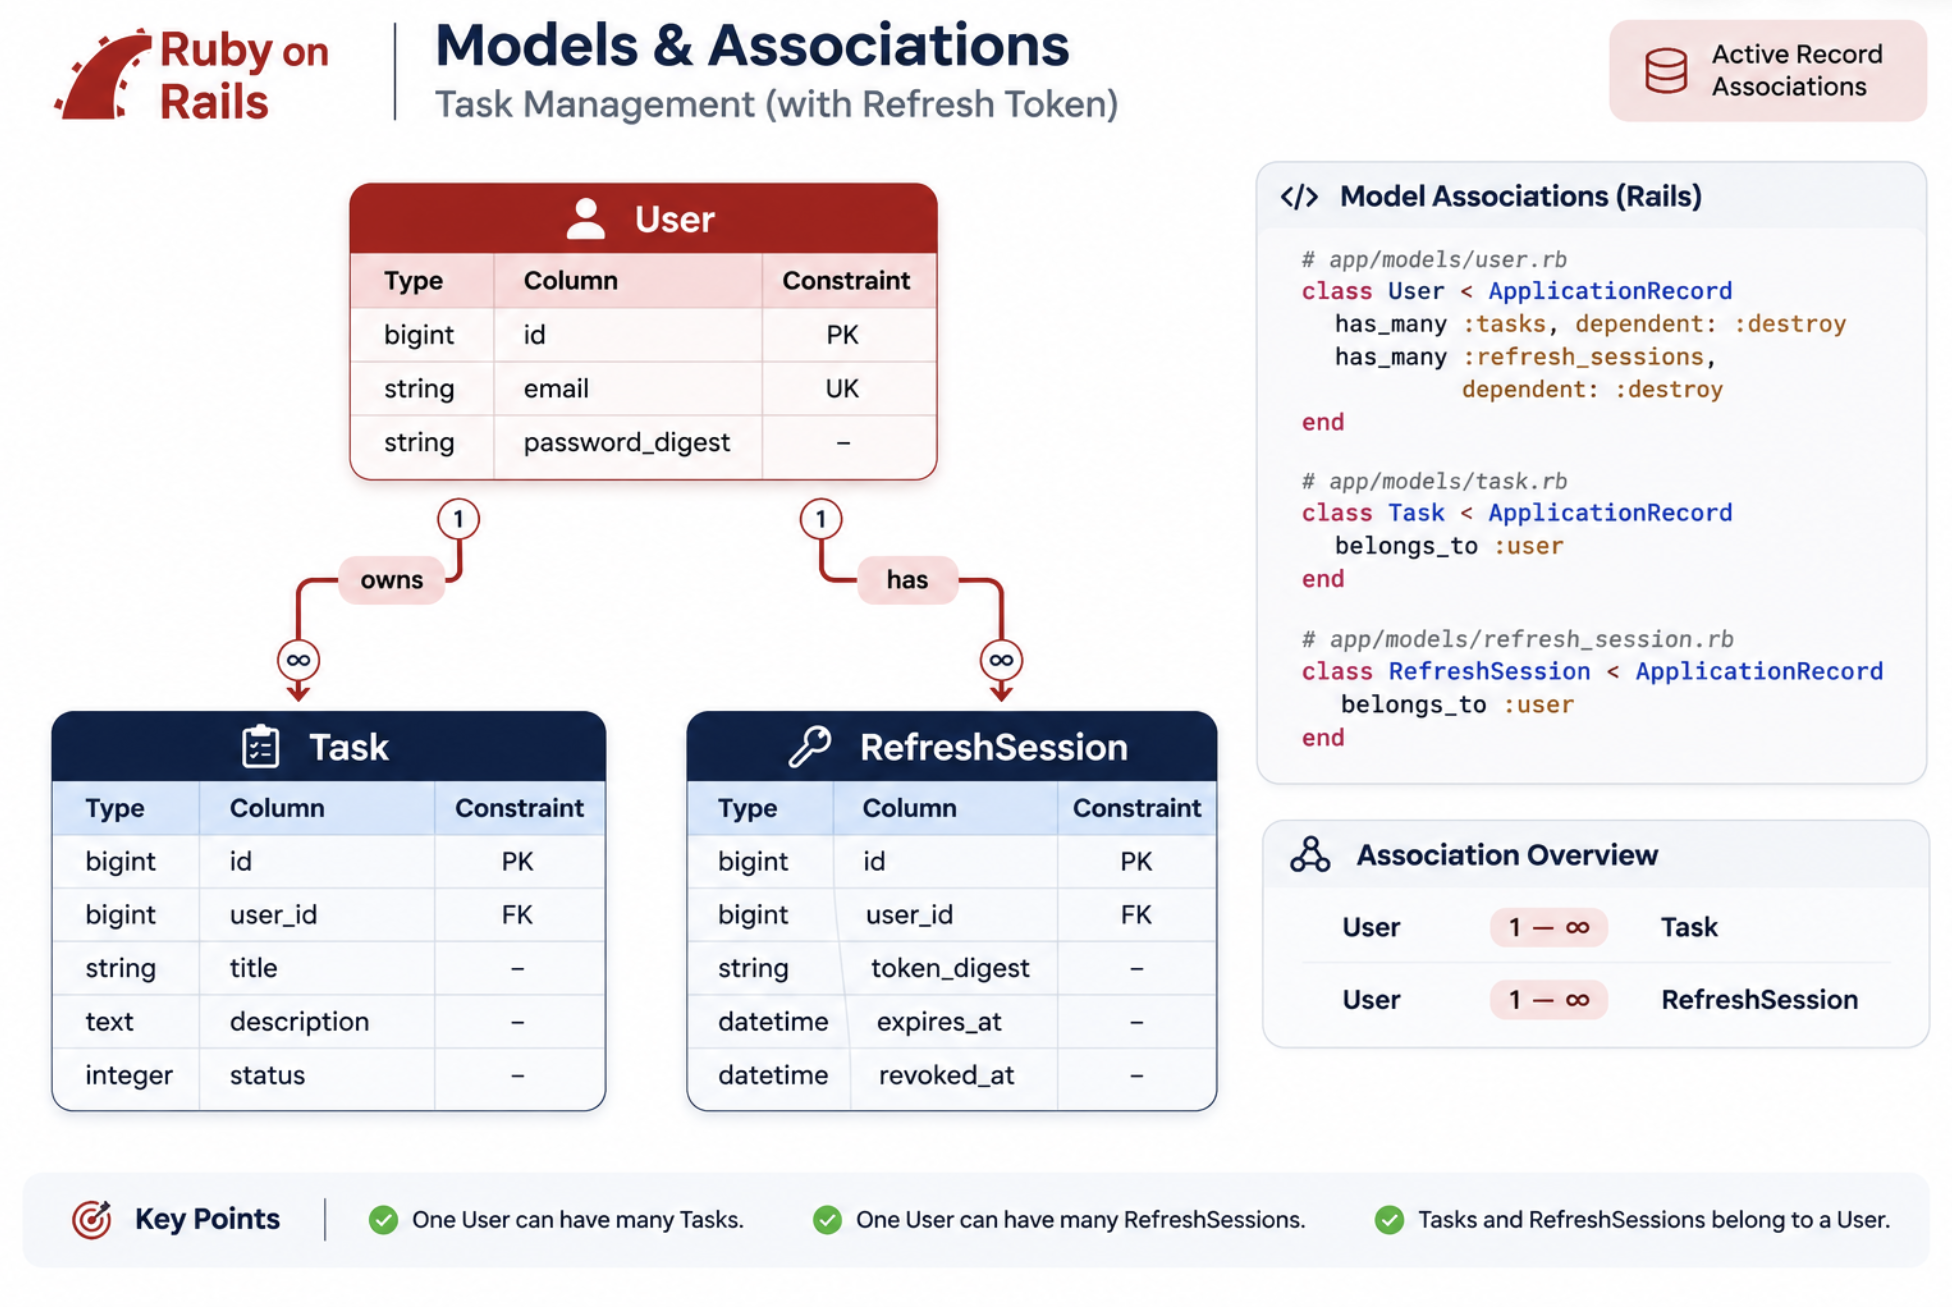
I want to start with the User model rather than Task, because our application will have JWT authentication and every task must belong to an authenticated user. We’ll introduce RefreshSession when we implement JWT refresh tokens.
Install bcrypt
Rails provides has_secure_password, which uses bcrypt for password hashing.
Uncomment this to backend/Gemfile: gem "bcrypt", "~> 3.1.7" and do bundle install
Why bcrypt?
We should never store users’ actual passwords in the database. Instead, bcrypt hashes the password using a salt. Rails provides password authentication functionality through has_secure_password. We’ll explore password hashing, verification and authentication in detail when implementing JWT login.
Generate User model
rails g model User email:string password_digest:string
      invoke  active_record
      create    db/migrate/20261117085319_create_users.rb
      create    app/models/user.rb
      invoke    rspec
      create      spec/models/user_spec.rb
Notice invoking rspec, because we configured rspec generators. Notice that we’re using password_digest, not password. has_secure_password provides a virtual password attribute and stores its hash in password_digest
Review the migration
Make these database-level changes:
email must not be NULL.
password_digest must not be NULL.
Add a unique, case-insensitive index for email.
class CreateUsers < ActiveRecord::Migration[8.1]
  def change
    create_table :users do |t|
      t.string :email, null: false
      t.string :password_digest, null: false

      t.timestamps
    end

    add_index :users, "lower(email)", unique: true, name: :idx_users_lower_email
  end
end
Run:
rails db:prepare -t
Inspect db/schema.rb. You should see the users table with the expected columns and index.
Checklist
Add bcrypt to Gemfile.
Generate User model.
Add database constraints.
Add case-insensitive unique email index.
Run migrations successfully.
Inspect schema.rb.
Commit changes.
We’ll introduce has_secure_password, email normalization, validations, described_class, build_stubbed vs new and proper model specs. We’ll also begin understanding how RSpec interacts with ActiveRecord and PostgreSQL.
Let’s implement our first real Rails model behaviour and write meaningful RSpec tests against it.
User model, validations and password security
in User model add: has_secure_password
What does this provide? When you assign: user.password = "my-secret-password" Rails automatically generates a bcrypt password digest and stores it in: user.password_digest
It also provides: user.authenticate("my-secret-password")
The behaviour is:
Input
Result
Correct password
Returns the user object
Incorrect password
Returns false
Important things to understand:
has_secure_password provides these validations automatically:
Password must be present when creating a new record.
Password cannot exceed 72 bytes.
Password confirmation is checked when you supply password_confirmation.
It does not enforce a minimum password length or complexity. We’ll discuss our password policy when implementing registration. Also, bcrypt’s 72-byte limit is a byte limit, not necessarily a 72-character limit.
Normalization happens when an attribute is assigned or validated.
It keeps email representation consistent.
You don’t need to remember to call .strip.downcase in every controller.
Rails has supported normalizes since Rails 7.1.
Add email validations
Add validations for:
Email presence.
Email uniqueness, case-insensitive.
Use Rails validations rather than implementing custom validation methods for these requirements.
Important architectural distinction:
We’re using two protections for uniqueness:
ActiveRecord uniqueness validation – provides a useful validation error to the application.
PostgreSQL unique index – protects the database against concurrent duplicate inserts.
Neither replaces the other.
Note: Our earlier lower(email) unique index is important here. The validation and database constraint must enforce the same case-insensitive uniqueness rule.
Understand the complete model behaviour
Your model should now have three responsibilities:
inside every example, we can use: described_class.new(...)
When we write: RSpec.describe User do
described_class refers to User
Why is this useful?
Imagine we later rename the model or move the spec. Using described_class reduces unnecessary references to the class name.
Open:backend/spec/models/user_spec.rb
newvscreate!
We’ll use native ActiveRecord methods for now, before introducing FactoryBot.
Method
Behaviour
User.new
Creates an unsaved ActiveRecord object
User.create
Creates and attempts to persist a record
User.create!
Persists or raises an exception if validations fail
user = User.new(email: "test@example.com")
user.persisted? # false

# whereas:
user = User.create!(...)
user.persisted? # true
For a model uniqueness test, we need a persisted record to check against. We’ll introduce FactoryBot later and understand build, create and build_stubbed.
Remember: Rails only checks confirmation when password_confirmation is supplied.
User Spec spec/models/user_spec.rb:
require 'rails_helper'

RSpec.describe User, type: :model do
  let(:valid_user) { described_class.create!(email: "email@example.com", password: "password@1") }
  let(:non_persisted_user) { described_class.new(email: "  EMAIL@example.com  ", password: "Pass12#") }

  describe "validations" do
    context "valid user" do
      it "check valid user" do
        expect(non_persisted_user.valid?).to be_truthy
      end

      it "check email, password presence" do
        non_persisted_user.valid?
        expect(non_persisted_user.email).not_to be_empty
        expect(non_persisted_user.password).not_to be_empty
      end
    end

    context "invalid user" do
      it "missing email, password, password digest" do
        invalid_user = described_class.new(email: "", password: "")
        invalid_user.valid?
        expect(invalid_user.errors.full_messages).to include("Email can't be blank")
        expect(invalid_user.errors.full_messages).to include("Password can't be blank")
        expect(invalid_user.errors.full_messages).to include("Password digest can't be blank")
      end

      it "throw error email not unique" do
        valid_user
        invalid_user = described_class.new(email: " EMAIL@EXAMPLE.com", password: "password@1")
        invalid_user.valid?
        expect(invalid_user.errors.full_messages).to include("Email has already been taken")
      end
    end
  end

  describe "email normalization" do
    it "email normalization when validation happens" do
      non_persisted_user.valid?
      expect(non_persisted_user.email).to eq("email@example.com")
    end

    it "email normalization when assignment" do
      new_user = described_class.new
      new_user.email = "  MYEMAIL@GMAIL.COM "
      expect(new_user.email).to eq("myemail@gmail.com")
    end

    it "checks email normalized after saving" do
      non_persisted_user.save!
      expect(non_persisted_user.email).to eq("email@example.com")
    end
  end

  describe "Passwords" do
    context "Passwords authentication" do
      it "checks valid authentication if email and password provided" do
        result = valid_user.authenticate("password@1")
        expect(result).to equal(valid_user)
      end

      it "checks invalid authentication if wrong password given" do
        result = valid_user.authenticate("wrong-pass12")
        expect(result).to be(false)
      end
    end

    context "Password digest" do
      it "checks password digest is present" do
        expect(valid_user.password_digest).not_to be_empty
      end

      it "password digest does not equal the original password" do
        expect(valid_user.password_digest).not_to eq(valid_user.password)
      end

      it "The password digest is stored, not the plain-text password" do
        # expect(valid_user.password_digest).
      end
    end
  end
end
Q): How doesletcaching work?
This is an important concept.
RSpec memoizesletvalues per example (it), not across examples.
Consider:
let(:user) do
  puts "Creating user"
  described_class.create!(
    email: "test@example.com",
    password: "password123"
  )
end
Now imagine three examples:
it "example 1" do
  user
  user
end

it "example 2" do
  user
end

it "example 3" do
  user
end
The execution looks like this:
Example 1
   |
   v
Access user
   |
   v
Execute let block (1st time)
   |
   v
Cache the result
   |
   v
Access user again
   |
   v
Return cached object
   |
   v
Example ends - cache discarded

Example 2
   |
   v
Access user
   |
   v
Execute let block again (2nd time)
   |
   v
Cache the result
   |
   v
Example ends - cache discarded

Example 3
   |
   v
Access user
   |
   v
Execute let block again (3rd time)
   |
   v
Cache the result
So the output will be:
Creating user
Creating user
Creating user
Key concept The user object is cached within one example, but a new object is created for every subsequent example that accesses user.
What aboutlet!?
Exactly the same memoization, but with eager evaluation.
let!(:user) do
  puts "Creating user"
  described_class.create!(...)
end
The block executes automatically before every example.
Even if you never reference user inside the example, it is still created.
Behaviour
let
let!
Lazy evaluation
Yes
No
Automatic evaluation
No
Yes
Memoized within example
Yes
Yes
Cached across examples
No
No
Executes again in next example
When referenced
Always
Important: RSpec’s memoization is unrelated to Rails caching (Rails.cache) or database caching. It only caches the helper’s return value for the current example.
There is too much test cases for a small user model snippet. So how big the test will be if the user model evolves and becomes big.
Q) Is it worth spending these much time spending test examples or do we write only the major ones in real world?
We deliberately wrote more examples than we’d probably write for such a small model in a real project. The objective was to teach you RSpec matchers, setup, validations, memoization and password testing.
In real-world development, we don’t write tests for every possible combination just to increase the test count.
What do we actually test in production?
My recommendation is:
Test behaviour and business rules, not every line of code.
For our current User model, I’d consider these the important behaviours:
Behaviour
Should we test?
Reason
Email presence
Yes
Business requirement
Email normalization
Yes
Data consistency
Case-insensitive uniqueness
Yes
Business requirement
Password authentication
Yes
Security-critical
Incorrect password
Yes
Security-critical
Password hashing
Yes
Security-critical
Password confirmation
If enabled
Registration requirement
Every possible email format
Not necessarily
Avoid redundant tests
Every possible password string
No
Test meaningful boundaries
Notice that we don’t necessarily need a separate example for every assertion. For example, password hashing could be tested in one example:
Create a user.
Reload the user from the database.
Verify that the password digest exists.
Verify that the original password isn’t stored as the password attribute.
Verify that authentication still works.
That’s one meaningful behaviour test rather than several fragmented tests.
How do we decide whether to write a separate test?
I generally follow these principles.
Rule 1: Different behaviour deserves different examples.
For example:
Correct password authenticates.
Incorrect password doesn’t authenticate.
These should be separate examples because they represent different outcomes.
Rule 2: Don’t test every framework feature.
For example, Rails already implements has_secure_password. We don’t need to test every internal operation of bcrypt. We need to test that our application uses it correctly.
Rule 3: Test security boundaries thoroughly.
Authentication, authorization, permissions, data ownership and input validation deserve more attention than simple getters and setters.
Rule 4: Test regressions.
Suppose a developer changes email normalization and accidentally removes .downcase. A good test should catch that regression.
Regression testing is a type of software testing performed to ensure that a recent code change, bug fix, new feature, or system update has not broken existing functionality.
When is it Performed?
You typically trigger regression testing in situations such as:
After bug fixes: To confirm that fixing one issue did not inadvertently create another.
After adding new features: To make sure new code plays nicely with legacy code.
After code refactoring: When the underlying code is cleaned up or restructured without changing its external behavior.
Before a major release: As a final baseline check across critical user journeys
What happens when a model becomes bigger?
Imagine our User model eventually supports:
class User < ApplicationRecord
  has_secure_password

  has_many :tasks
  has_many :refresh_sessions

  # Email normalization
  # Password validations
  # Account status
  # Roles
  # Account locking
  # Email verification
end
We shouldn’t put every possible test into one enormous example group.
We organize them by behaviour:
spec/
└── models/
    └── user_spec.rb
Inside:
RSpec.describe User, type: :model do
  describe "validations" do
    # Relevant validation examples
  end

  describe "associations" do
    # Association behaviour
  end

  describe "authentication" do
    # Password authentication
  end

  describe "email normalization" do
    # Normalization behaviour
  end

  describe "account locking" do
    # Account locking behaviour
  end
end
If the model becomes excessively complex, we should also consider extracting responsibilities into service objects or dedicated domain components instead of continuing to grow the model indefinitely.
What about 100% test coverage?
Don’t chase 100% coverage blindly.
Consider:
100% line coverage doesn’t guarantee that your application works correctly.
A test can execute a line without checking its result.
Critical security behaviour deserves tests even if the overall coverage is already high.
I prefer meaningful test coverage over a high coverage percentage.
My recommendation for our project
We’ll follow a practical testing strategy.
Our testing strategy
Model specs: Validate business rules, model behaviour, associations and important edge cases.
Request specs: Test HTTP requests, authentication, authorization, status codes and JSON responses.
Service specs: Test independent business logic such as JWT generation, verification and refresh-token rotation.
Integration testing: Verify that important application workflows work together.
Introduce FactoryBot
Let’s introduce FactoryBot, one of the most commonly used tools in Rails testing. Our goal is to stop manually constructing User records in every RSpec example and create reusable test data instead.
FactoryBot setup and fundamentals
1. Why do we need FactoryBot?
Consider our existing RSpec code:
let(:valid_user) do
  User.create!(
    email: "email@example.com",
    password: "password@1"
  )
end
Imagine we have 50 test examples involving users. We might repeatedly write: User.create!(email: "...", password: "...")
This creates several problems:
Repeated test data.
Duplicate attribute definitions.
Difficulties maintaining tests when models evolve.
Unintentional duplicate email addresses.
Complex setup when models have associations.
FactoryBot solves this by allowing us to define reusable object blueprints called factories.
In spec/support/factory_bot.rb, add this configuration:
RSpec.configure do |config|
  config.include FactoryBot::Syntax::Methods
end
Now open: spec/rails_helper.rb
Find this line (it may be commented out):
# Dir[Rails.root.join('spec', 'support', '**', '*.rb')].sort.each { |f| require f }
Uncomment it. See the comment above. This ensures that our support files are loaded when RSpec starts. This is fine for us as we only load the Rspec configuration from the support folder.
Why usespec/support?
As our testing infrastructure grows, we’ll add reusable configuration and helpers here.
Remember our unique email constraint in PostgreSQL. Without sequences, creating multiple users with the same email could result in uniqueness validation errors.
password – Provides a default password that satisfies our current User model requirements.
One important practice: a factory should provide the minimum attributes necessary to create a valid object. We’ll introduce optional attributes and traits later.
Understand FactoryBot build strategies
This is probably the most important FactoryBot concept.
FactoryBot supports four commonly used strategies.
1.build(:user)
In memory user = build(:user)
Creates a User instance.
Does not save it to PostgreSQL.
Does not execute database persistence callbacks.
Returns an unsaved ActiveRecord object.
Equivalent in concept to: User.new(...)
Use when: Testing validations and model behaviour without requiring database persistence.
2. create(:user)
Persisted user = create(:user)
Builds a User instance.
Saves it to PostgreSQL.
Runs validations and persistence callbacks.
Returns a persisted record.
Equivalent in concept to: User.create!(...)
Use when: Testing uniqueness, database queries, associations and persistence-related behaviour.
3.build_stubbed(:user)
Stubbed object user = build_stubbed(:user)
Does not save the record to PostgreSQL.
Assigns simulated persistence attributes such as an ID.
Stubs database-related behaviour.
Use when: You need an object that behaves like a persisted record but don’t need actual database interaction.
Be careful: it isn’t a substitute for a real persisted record in integration or database-dependent tests.
4.attributes_for(:user)
Hash only attributes = attributes_for(:user)
Returns an attribute hash rather than a User object.
Use when: Building request payloads or testing API input handling.
An important performance consideration: unnecessary database writes make large test suites slower. Choose the lightest strategy that actually tests the behaviour you care about.
FactoryBot traits and list factories
Now let’s learn two features that become particularly useful when application models grow.
build_list – users = build_list(:user, 5) – Creates five User objects without saving them.
create_list – users = create_list(:user, 5) – Creates five User records and persists them to PostgreSQL.
Method
Objects
Database
build_list
5
No records
create_list
5
5 records
Both methods return arrays.
Exercise
Create a new spec: touch spec/learning/factory_bot_lists_spec.rb Write two examples.
Exercise A – build_list – Create three users and verify:
Array contains three users.
None of the users is persisted.
All three emails are unique.
Exercise B – create_list – Create three users and verify:
Array contains three users.
All three are persisted.
All three have unique IDs
describe "Factory Bot: Build list" do
    context "create three users and verify" do
      it "contains 3 users" do
        users = build_list(:user, 3)
        expect(users.size).to eq(3)
      end
      it "3 users are not persisted and emails are unique" do
        users = build_list(:user, 3)
        emails = []
        users.each do |user|
          emails << user.email
          expect(user.persisted?).to eq(false)
        end
        expect(emails.uniq.size).to eq(3)
      end
    end
  end

  describe "Factory Bot: Create list" do
    context "create three users and verify" do
      it "contains 3 users" do
        users = create_list(:user, 3)
        expect(users.size).to eq(3)
      end
      it "all users are persisted and have unique ids" do
        users = create_list(:user, 3)
        user_ids = []
        users.each do |user|
          user_ids << user.id
          expect(user.persisted?).to eq(true)
        end
        expect(user_ids.uniq.size).to eq(3)
      end
    end
  end
FactoryBot traits
Now imagine our User model supports password confirmation. We may need different user states in different tests:
User with matching password confirmation.
User with mismatched password confirmation.
User without password.
We don’t want to create a separate factory for every scenario. This is where traits are useful. A trait represents a reusable variation of an existing factory. For example:
Both reuse the same :user factory but apply different attributes.
Assignment
Open: spec/factories/users.rb Add two traits:
Trait
Behaviour
:with_password_confirmation
Sets password confirmation equal to password
:with_invalid_password_confirmation
Sets a different password confirmation
Don’t add any new model validations. Rails’ has_secure_password already supports password confirmation validation when confirmation is supplied.
Test these traits
In your new spec file, create examples that:
Build a user with matching password confirmation and verify that it is valid.
Build a user with mismatched password confirmation and verify that it is invalid.
Verify that the second user has the expected validation error.
Important: Use build, not create for these tests. We are testing validation behaviour, not database persistence.
# spec/models/user_spec.rb

context "With Traits" do
      it "verify with password confirmation" do
        user = build(:user, :with_password_confirmation)
        expect(user.valid?).to eq(true)
      end
      it "verify with invalid password confirmation" do
        user = build(:user, :with_invalid_password_confirmation)
        expect(user.valid?).to eq(false)
        expect(user.errors.full_messages).to include("Password confirmation doesn't match Password")
      end
    end
Understanding when to use traits vs overrides
This distinction is useful in real projects.
Requirement
Preferred approach
Change email for one example
Attribute override
Create multiple users
create_list
Reuse an admin user state
Trait
Reuse an inactive user state
Trait
Change password for one example
Attribute override
Reuse a specific authentication state
Trait
Don’t create traits for every possible attribute combination. Traits are most useful for meaningful, reusable object states.
Create the Task model and database relationship
Now we’re moving into the actual Task Management application.
Our first important domain relationship:
One User can create multiple Tasks.
Every Task belongs to exactly one User.
Database relationship
User1 : NTasks -> user_id (FK) – Each task stores the ID of its owner.
1. Decide our Task attributes
Let’s start with a simple schema.
Column
Type
Configuration
id
bigint
Primary key
user_id
bigint
Foreign key, NOT NULL
title
string
NOT NULL
description
text
Nullable
status
integer
NOT NULL, default 0
created_at
datetime
Automatically generated
updated_at
datetime
Automatically generated
For the status, we’ll eventually support:
pending
in_progress
completed
Why integer?
Rails supports enums that map readable status names to integer values in the database. We’ll implement the enum separately and understand its advantages and pitfalls, particularly why explicitly mapping enum values is important.
Generate the Task model
From your backend directory:
bin/rails generate model Task title:string description:text status:integer user:references
Because we’ve configured RSpec generators, you should get (notice invoking Rspec and FactoryBot):
Inspect the actual migration and make the necessary adjustments.
Configure the associations
Open: app/models/user.rb – Add the one-to-many association. Open: app/models/task.rb – Inspect the generated belongs_to association.
# migration
class CreateTasks < ActiveRecord::Migration[8.1]
  def change
    create_table :tasks do |t|
      t.string :title, null: false
      t.text :description
      t.integer :status, null: false, default: 0
      t.references :user, null: false, foreign_key: true

      t.timestamps
    end
  end
end

# user model
class User
  has_many :tasks, dependant: :destroy
  ....
end

# task model
class Task < ApplicationRecord
  belongs_to :user
end
We’ll discuss the difference between destroy, delete, dependent: :delete_all and database-level cascading deletion later.
This is particularly useful because real applications rarely have isolated models. Most models have relationships, and our tests need to create related records efficiently.
1. Create the Task factory
Open: spec/factories/tasks.rb
Our Task model has:
title
description
status
user_id
We want every generated Task to have an associated User. Your factory should follow this structure:
FactoryBot.define do
  factory :task do
    title { "Improve Product" }
    description { "Improve the product page by minimizing dependancies" }

    association :user
  end
end
Understandassociation :user
FactoryBot understands that the Task factory needs a User factory to construct its associated User. It automatically resolves the :user factory. You could also write: user. But I prefer association :user for now.
How does FactoryBot handle associated objects?
This is an important concept. FactoryBot uses the parent’s build strategy for associations by default.
Consider: task = build(:task)
Expected behaviour:
build(:task)
     |
     v
Build Task object
     |
     v
Build associated User
     |
     v
Return Task
     |
     v
Neither record persisted
Now consider: task = create(:task)
Expected behaviour:
create(:task)
     |
     v
Create associated User
     |
     v
Create Task with user_id
     |
     v
Both records persisted
This is controlled by FactoryBot’s use_parent_strategy configuration, which defaults to true
An important mistake to avoid:
Don’t write this inside the Task factory: user { create(:user) }
Why? Even when you call build(:task), this explicitly creates and persists the User. You lose the advantage of build. Use association :user instead.
Attribute override for associations
Let’s say we already have a User and want to assign that specific User to a Task.
We can override the association:
user = create(:user)

task = build(:task, user: user)
Now the Task belongs to the User you supplied. This is useful when testing ownership, permissions and authorization later. For example, we’ll eventually have multiple users, each with their own tasks.
RSpec assignment
open: backend/spec/models/task_spec.rb
Use:
RSpec.describe Task, type: :model do
  describe "associations" do
    it "belongs_to" do
      task = create(:task)
      expect(task.user).to be_truthy
      expect(task.user_id).to be_truthy
    end
    it "has_many" do
      user = create(:user)
      create_list(:task, 3, user: user)

      expect(user.tasks.count).to eq(3)
    end
  end
end
Implement these four examples.
Exercise 1 – Build associated User
Use build(:task). Verify:
Task is not persisted.
Task has a User object.
Associated User is not persisted.
Exercise 2 – Create associated User
Use create(:task). Verify:
Task is persisted.
Associated User is persisted.
task.user_id matches task.user.id.
Exercise 3 – Override association
Create a User separately. Pass that User into build(:task, user: user). Verify that the Task belongs to the exact User object supplied. Hint: Think about the difference between eq and equal.
Exercise 4 – Multiple Tasks for one User
Create one User and three Tasks associated with that User. Verify:
There are three Tasks.
All three belong to the same User.
All three Tasks are associated with the User through the has_many relationship.
Hint: create_list(:task, 3, user: user).
Run your tests: rspec spec/models/task_spec.rb --format documentation
If your test database hasn’t been prepared since the Task migration: You could use bin/rails db:test:prepare
Task model validations
Now let’s implement actual business rules for our Task model.
1. Define our validation requirements
For our application, let’s establish these rules:
Attribute
Requirement
title
Required
title
Maximum 120 characters
description
Optional
description
Maximum 2,000 characters
user
Required
status
We’ll handle separately using Rails enums
Why these requirements?
A task without a title doesn’t provide meaningful information.
A title should be reasonably short because it appears in the task list.
Description should be optional because sometimes users only need a task title.
Every task must belong to a user.
Rails automatically validates the presence of the associated user by default. You generally don’t need to add another validates :user, presence: true. Remember that we also have a database foreign key and NOT NULL constraint. These protect the database independently of model validations.
RSpec.describe Task, type: :model do
  describe "validations" do
    it "a valid task" do
      task = build(:task)
      expect(task.valid?).to eq(true)
    end

    it "title presence, check nil, empty, space contents" do
      task = build(:task, title: nil)
      task.valid?
      expect(task.errors.full_messages).to include("Title can't be blank")
      task = build(:task, title: '')
      task.valid?
      expect(task.errors.full_messages).to include("Title can't be blank")
      expect(task.errors.full_messages).to include("Title is too short (minimum is 2 characters)")
      task = build(:task, title: '  ')
      task.valid?
      expect(task.errors.full_messages).to include("Title can't be blank")
    end

    it "title length" do
      task = build(:task, title: "my " * 40) # 120 chars
      expect(task.valid?).to eq(true)
      task = build(:task, title: "my " * 40 + "q") # 121 chars
      expect(task.valid?).to eq(false)
    end

    it "valid description" do
      task = build(:task, description: nil)
      expect(task.valid?).to eq(true)
      task = build(:task, description: "my" * 1000) # 2000 chars
      expect(task.valid?).to eq(true)
      task = build(:task, description: "my" * 1000 + 'm') # 2001 chars
      expect(task.valid?).to eq(false)
    end

    it "user association" do
      task = build(:task, user: nil)
      expect(task.valid?).to eq(false)
    end
  end
end
Use FactoryBot for test data.
Exercise 1 – Valid task Exercise 2 – Title presence – Title is nil. Title is an empty string. Exercise 3 – Title length Exercise 4 – Description – Description is nil – valid. Description is empty – valid.
Exercise 1 – User has many tasks – Create a user and three associated tasks. Verify that:
The user has three tasks.
All tasks belong to that user.
All returned tasks are persisted.
Exercise 2 – Destroy dependent tasks – Create a user and three associated tasks. Destroy the user. Verify:
The user is destroyed.
All three tasks are destroyed.
The task records no longer exist in the database.
Hint: You can use reload carefully or Task.exists? to verify database state.
Exercise 3 – Task belongs to User – Create a task. Verify:
task.user returns a User.
task.user_id matches task.user.id.
The association can be reloaded successfully.
Let’s move to an important Rails feature: ActiveRecord Enums.
task.user returns a User.
task.user_id matches task.user.id.
Rails Enums
We’ll implement task statuses using Rails enums and learn how Rails maps human-readable values to integers in PostgreSQL.
1. Why do we need enums?
Our Task model has a status integer column. Without enums, we might write:
Rails also supports: enum :status, [:pending, :in_progress, :completed]
This automatically maps values based on their positions:
pending => 0
in_progress => 1
completed => 2
However, consider adding another status in the middle later. The integer mapping could change, potentially corrupting the interpretation of existing records.
My recommendation: Always use explicit integer mappings for database-backed enums in production applications. Keep existing mappings stable.
Understand what Rails generates automatically
This is where enums become interesting. Once you define the enum, Rails generates several methods automatically.
Useful when you need to inspect the database mapping or build queries.
Important: What doesvalidate: truedo?
Notice that we used: validate: true This is an important option. By default, assigning an unsupported enum value raises an ArgumentError immediately.
For example:
task.status = :unknown
But with validate: true:
task.status = :unknown
task.valid?
# false
Rails adds an inclusion validation instead.
Why did we choose this?
Eventually, our React application will send status values to Rails through API requests. Suppose React sends:
{
"status": "invalid_status"
}
We want to handle this as a model validation failure and return a proper 422 Unprocessable Entity response, rather than accidentally returning a server error because of an exception.
Now let’s test the actual enum functionality. Open: backend/spec/models/task_spec.rb
Add a new group:
describe "status" do
it "default status" do
task = build(:task)
expect(task.status).to eq('pending')
expect(task.pending?).to eq(true)
expect(task.completed?).to eq(false)
end
it "status assignment" do
task = build(:task, status: :in_progress)
expect(task.status).to eq('in_progress')
expect(task.in_progress?).to eq(true)
expect(task.pending?).to eq(false)
end
it "status bang methods" do
task = create(:task)
task.completed!
expect(task.status).to eq('completed')
expect(task.completed?).to eq(true)
expect(task.pending?).to eq(false)
task.reload # confirm db persistence
expect(task.completed?).to eq(true)
end
it "Enum mapping" do
status = described_class.statuses
expect(status['pending']).to eq(0)
expect(status['in_progress']).to eq(1)
expect(status['completed']).to eq(2)
end
it "Invalid status" do
task = build(:task)
task.status = :invalid
expect(task.valid?).to eq(false)
not_included_msg = "Status is not included in the list"
expect(task.errors.full_messages).to include(not_included_msg)
task.status = nil
task.valid?
expect(task.errors.full_messages).to include(not_included_msg)
end
it "Enum scopes" do
pending = create(:task)
in_progress = create(:task, status: :in_progress)
completed = create(:task, status: :completed)
expect(Task.pending).to contain_exactly(pending)
expect(Task.in_progress).to contain_exactly(in_progress)
expect(Task.completed).to contain_exactly(completed)
end
end
Implement these six scenarios.
Exercise 1 – Default status
Build a new Task without specifying its status. Verify:
task.status returns "pending".
task.pending? returns true.
task.completed? returns false.
Remember, this depends on the database default being 0.
Exercise 2 – Status assignment
Build a Task with: status: :in_progress Verify:
Its status is "in_progress".
in_progress? returns true.
pending? returns false.
Exercise 3 – Bang methods
Create a persisted Task and call: task.completed! Verify:
completed? returns true.
The updated status is "completed".
Reloading the record still gives "completed".
Why do we reload? We want to verify that the database was actually updated.
Exercise 4 – Enum mapping
Verify the mapping returned by: described_class.statuses
Check that each status maps to the expected integer.
Exercise 5 – Invalid status
Build a Task and assign: task.status = :invalid_status
Because we enabled validate: true, verify that:
No ArgumentError is raised.
task.valid? returns false.
A status validation error is present.
Also check what happens when status is explicitly assigned nil.
Exercise 6 – Enum scopes
Create three Tasks:
One pending.
One in progress.
One completed.
Verify that:
Task.pending
Task.in_progress
Task.completed
each returns only the matching Task. Use contain_exactly or match_array where appropriate.
One database configuration check
Before running the tests, inspect your original Task migration and schema.rb. We should have: t.integer "status", default: 0, null: false
This is important for two reasons:
Every new task starts as pending.
The database doesn’t allow a NULL status.
If you already configured this earlier, no changes are necessary. If the migration has already been applied and the constraint is missing, generate a new migration rather than silently changing an already-applied migration.
Q) Why do you use Enums? and integer-backed enums instead of storing strings directly?
Rails enums provide a convenient interface for managing a fixed set of values, including generated predicate methods, scopes and update methods. Integer-backed enums also use less storage and generally produce more compact indexes than string-backed equivalents.
However, string-backed enums are also supported. The choice depends on database readability, maintainability and performance requirements. I wouldn’t choose integer-backed enums solely for performance without measuring the actual workload.
We shouldn’t use integers just because Rails supports enums.
You can absolutely store"pending","in_progress"and"completed"directly as strings in PostgreSQL. There are legitimate reasons to choose either approach.
Let’s understand the actual trade-offs.
1. Three ways to store status
There are three approaches worth understanding.
Option A: Store strings directly
Database:
tasks
--------------------------------
id | title       | status
--------------------------------
1  | Learn Rails | pending
2  | Learn React | in_progress
3  | Write tests | completed
Rails supports both integer-backed and string-backed enums. Its documentation notes that string-backed enums will likely result in slower database queries.
2. Does storing integers improve performance?
Yes, there can be storage and indexing advantages. But let’s understand how significant they are.
Approximate column value storage, excluding row and index overhead.
Imagine you have 10 million tasks.
For illustration, assuming every record has the same status:
Storage
Approximate size
Integer (4 bytes)
38.1 MiB
String pending (8 bytes)
76.3 MiB
That difference becomes meaningful at scale. For our small Task Management application, however, the difference is practically irrelevant.
B. Index performance
This is where your question becomes interesting. Suppose we create an index:
add_index :tasks, :status
With an integer-backed enum, the database indexes integer values.
With a string-backed enum, the database indexes string values.
Both can use PostgreSQL B-tree indexes.
Integer index keys are more compact and integer comparisons are generally cheaper than string comparisons. However, don’t assume that integer storage automatically makes every query faster.
Consider: SELECT * FROM tasks WHERE status = 0;
versus: SELECT * FROM tasks WHERE status = 'pending';
Both can use an appropriate index.
An important point: Our status column has only three possible values. This is called low cardinality.
If 60% of your records are pending, an index on status alone might not be particularly useful. PostgreSQL may prefer a sequential scan because so many rows match.
We need to consider actual queries and their execution plans. For our application, a query such as: Task.where(user_id: current_user.id, status: :pending)
might benefit from a composite index: add_index :tasks, [:user_id, :status]
We shouldn’t add it blindly, though. We’ll later examine EXPLAIN ANALYZE and understand whether it helps.
3. What is the actual benefit of Rails enums?
In my opinion, this is the more important reason to use them. Regardless of whether you choose integer or string storage, Rails enums provide a convenient interface for working with a fixed set of values.
You also get the status mapping through: Task.statuses
So enums provide:
A defined set of allowed values.
Generated predicate methods.
Generated update methods.
Generated database query scopes.
Consistent mapping between application values and stored values.
This is why enums are useful even when storage performance isn’t important.
One distinction: a Rails enum is not the same thing as PostgreSQL’s native ENUM data type. Rails’ integer-backed enum is an application-level mapping to a normal integer column.
4. What would I choose for our Task Management application?
Here’s the recommendation.
Consideration
Integer-backed
String-backed
Storage efficiency
Better
Slightly larger
Index key size
Smaller
Larger
Database readability
Less readable
More readable
Rails generated methods
Yes
Yes
Adding statuses
Maintain mappings
More straightforward
SQL debugging
Requires mapping
Directly readable
For our project, both are perfectly reasonable.
I would actually lean towards string-backed Rails enums for this particular application if we were prioritizing database readability and simplicity over storage optimization.
We only have three statuses, and there’s no meaningful performance bottleneck here.
However, we’ll retain the integer-backed implementation for our current exercise so you understand the conventional Rails approach, its generated methods, its mapping and its trade-offs.
One takeaway for our project: Enums are primarily about representing and managing a fixed set of domain values conveniently. Integer storage is an additional benefit, not the fundamental reason to use enums.
Let’s create an application for managing Tasks that are created by different users. Let’s use React UI for quick data response. The app consists of CRUD operations of Tasks, User Authentication using JWT-Tokens, User Authorization for their particular tasks.
Technology stack
Here’s the list of technology stack we use in our application.
Download the one of the latest one if you have currently installed the old version.
$ brew install postgresql@18

Installing postgresql@18
==> Pouring postgresql@18--18.7.arm64_tahoe.bottle.tar.gz
Warning: postgresql@18 was installed but not linked because postgresql@14 is already linked.
To link this version, run:
brew link postgresql@18

$ brew link postgresql@18
Unlinking /opt/homebrew/Cellar/postgresql@14/14.17_1... 2165 symlinks removed.
Linking /opt/homebrew/Cellar/postgresql@18/18.7... 812 symlinks created.
$ psql --version
psql (PostgreSQL) 18.7 (Homebrew)
Update node js:
$ node -v
v24.14.0
install the latest Long-Term Support release
$ nvm install --lts
Installing latest LTS version.
Downloading and installing node v26.13.1...
Downloading https://nodejs.org/dist/v26.13.1/node-v26.13.1-darwin-arm64.tar.xz...
Computing checksum with sha256sum
Checksums matched!
Now using node v26.13.1 (npm v11.20.0)
Create app folder:
$ mkdir rails-react-task-manager
$ cd rails-react-task-manager
$ git init -b main
We want to manage the backend, frontend, Docker configuration and CI/CD workflows in one repository.
Update ruby gems:
A new release of RubyGems is available: 4.0.20 → 4.0.24!
See https://github.com/ruby/rubygems/blob/v4.0.24/CHANGELOG.md for the changes since 4.0.20.
Run `gem update --system 4.0.24` to update your installation
Note: Pessimistic version constraint. Using -v “~> 8.1.0” installs the latest patch release within the 8.1 series (such as 8.1.4.1) while avoiding unintended jumps to future minor or major versions
Started GET "/" for ::1 at 2026-11-15

ActiveRecord::StatementInvalid (PG::InvalidParameterValue: ERROR:  invalid value for parameter "TimeZone": "UTC"
)
Caused by: PG::InvalidParameterValue (ERROR:  invalid value for parameter "TimeZone": "UTC"
)

Information for: ActiveRecord::StatementInvalid (PG::InvalidParameterValue: ERROR:  invalid value for parameter "TimeZone": "UTC"
):
Solution: check which PostgreSQL server is actually running
psql --version
brew services list
brew services stop postgresql@14
brew services restart postgresql@18
# then do
rails db:prepare -t # recommended
Restart the rails server. Also check:
curl -i http://localhost:3000/up
Install RSpec
Add RSpec to Gemfile
group :development, :test do
  gem "rspec-rails", "~> 8.1"
end
Install the gem
cd backend
bundle install
bundle exec rspec --version
spec_helper.rb can be used for tests that don’t require Rails.
rails_helper.rb loads the Rails application and integrates Rails testing functionality.
Verify:
bundle exec rspec
No examples found.

Finished in 0.00022 seconds (files took 0.05449 seconds to load)
0 examples, 0 failures
Minitest is still present: Your Rails application probably already has: backend/test/. That’s because Rails generated its default Minitest structure. We’ll configure Rails generators to use RSpec automatically, so that when we generate a model, Rails creates: spec/models/task_spec.rb instead of: test/models/task_test.rb. We’ll also decide how to handle the existing Minitest files cleanly.
Configure Rails generators to use RSpec
Currently, Rails uses Minitest as its default testing framework. For example, when you generate a model: bin/rails generate model Task title:string, Rails normally generates: app/models/task.rb test/models/task_test.rb
But we want: app/models/task.rb spec/models/task_spec.rb
RSpec Rails integrates with Rails generators to do exactly this.
Open: backend/config/application.rb and add:
config.generators do |g|
  g.test_framework :rspec
end
Important: This does not remove Minitest or disable its test runner. It changes the default generator behaviour.
We don’t want to generate our actual Task model just to test the configuration.
Instead, use Rails --pretend option:
rails g model Task title:string --pretend
      invoke  active_record
      create    db/migrate/20261115171837_create_tasks.rb
      create    app/models/task.rb
      invoke    rspec
      create      spec/models/task_spec.rb
For our Rails API, we’ll primarily use request specs instead of controller specs. A request spec tests the application from the HTTP client’s perspective. This lets us test the complete API behaviour rather than testing controller methods in isolation. RSpec Rails recommends request specs as the higher-level alternative to controller specs.
An RSpec test typically consists of four important building blocks:
RSpec syntax
Purpose
RSpec.describe
Defines the top-level example group
describe
Groups related examples
context
Describes a particular condition or scenario
it
Defines an individual test example
expect
Defines an expectation
to
Specifies the expected matcher
Let’s look at a simple example.
RSpec.describe "RSpec basics" do
  describe "equality matcher" do
    it "compares two values" do
      result = 2 + 3

      expect(result).to eq(5)
    end
  end
end
Understand each line
RSpec.describe "RSpec basics" – Creates an example group. This is the outermost container for our tests.
describe "equality matcher" – Groups tests related to equality. You can nest multiple describe blocks to organize tests logically.
it "compares two values" – Defines an individual test example. The string describes the expected behaviour. RSpec uses it when displaying test results.
expect(result).to eq(5) – This is the actual expectation.
expect(result) – the actual value.
to – tells RSpec we’re checking a positive expectation.
eq(5) – matcher checking whether the actual value equals 5 using Ruby’s == operator.
If the expectation fails, RSpec reports a failure with the actual and expected values.
Understand RSpec matchers
Matchers are one of the most important parts of RSpec.
They determine how RSpec compares actual and expected values.
Here are some commonly used matchers:
Matcher
Purpose
Example
eq
Value equality (==)
eq(10)
be
Object identity (equal?)
be(true)
include
Collection contains value
include("Rails")
be_nil
Checks nil
be_nil
be_empty
Checks empty collection
be_empty
be_truthy
Checks truthiness
be_truthy
be_falsey
Checks falsiness
be_falsey
match
Regular expression matching
match(/rails/i)
raise_error
Checks raised exception
raise_error(ArgumentError)
A particularly important distinction: expect("Rails").to eq("Rails")
This checks value equality. Whereas: expect(object).to be(other_object)
This checks whether both references point to the same object. Don’t confuse eq and be. You can also write negative expectations: expect(result).not_to eq(10) This verifies that the result isn’t equal to 10.
One principle to remember: Good tests should make the behaviour obvious, minimize duplicated setup and remain independent of one another. That’s the mindset I want you to develop while learning RSpec.
Understanddescribevscontext
They look similar, but they serve slightly different organizational purposes. Consider a future Task model.
RSpec.describe Task do
  describe "validations" do
    context "when title is present" do
      # Examples go here
    end

    context "when title is missing" do
      # Examples go here
    end
  end
end
Preferred convention:
describe: What behaviour are we testing?
context: Under what circumstances are we testing it?
it: What should happen?
Technically, describe and context create the same kind of RSpec example group. The difference is semantic and improves readability.
hands-on exercise
Let’s create a temporary learning spec. We aren’t creating the Task model or touching the database yet. From your backend directory:
Start with the previous equality example. Now add your own examples to cover these requirements:
Exercise 1 – Equality
Write an example that checks whether 10 + 20 equals 30.
Exercise 2 – Collection
Given: languages = ["Ruby", "JavaScript", "Python"]
Write an expectation that verifies the array includes "Ruby".
Exercise 3 – Nil
Given a variable whose value is nil, verify that it is nil.
Exercise 4 – Boolean
Given a variable whose value is false, verify that it is exactly false.
Exercise 5 – Negative expectation
Verify that the languages array does not include "Java".
Execute your tests: bundle exec rspec spec/learning/rspec_basics_spec.rb
For more readable output: bundle exec rspec spec/learning/rspec_basics_spec.rb --format documentation , The documentation formatter displays the example descriptions and their results.
RSpec.describe "Rspec Basics learning" do
  describe "Equality" do
    let(:languages) { ["Ruby", "JavaScript", "Python"] }

    it "check addition" do
      expect(10 + 20).to eq(30)
    end

    it "include in the list" do
      expect(languages).to include "Ruby"
    end

    it "checks nil value" do
      nil_value = nil
      expect(nil_value).to be_nil
    end

    it "checks false value" do
      false_value = false
      true_value = true
      expect(false_value).to be false
      expect(false_value).to be_falsey
      expect(true_value).to be_truthy
      expect(true_value).to be true
    end

    it "checks negative expectation" do
      expect(languages).not_to include "Scala"
    end
  end
end

# run
$ rspec spec/
Note: be falsevsbe_falsey These are different expectations.
expect(false).to be false
expect(false).to be_falsey
expect(nil).to be_falsey
expect(true).to be_truthy
be_truthy accepts anything other than false or nil. be false checks that the value is exactly false. be_falsey accepts either false or nil. let is lazily evaluated and memoized within an individual example.
We’ll apply these concepts to our first actual Rails model spec. No need to rush into FactoryBot yet. We should understand native RSpec first.
RSpec hooks: before, after, let and let!
This is one of the most frequently used parts of RSpec in real Rails projects. When writing model and request specs, we often need to prepare test data before executing an example.
For example:
Create a user before testing authentication.
Create a task before testing task updates.
Prepare some data before testing associations.
Clean up resources after an example.
RSpec provides hooks and helper methods for this.
beforehook
RSpec.describe "Task" do
  before do
    puts "Running before hook"
  end

  it "checks something" do
    puts "Running example"
  end

  it "checks something else" do
    puts "Running another example"
  end
end

# output
Running before hook
Running example

Running before hook
Running another example
before executes before every example by default. These are equivalent:
before do
  # Setup
end

# and

before(:each) do
  # Setup
end
When do we use it?
When every example needs some common setup. For example, imagine we need a variable initialized before each test.
Imagine we have 10 test examples and every example requires the same initial setup.
# Without hooks, you might repeat:

it "example 1" do
  languages = ["Ruby", "JavaScript"]
  # Test logic
end

it "example 2" do
  languages = ["Ruby", "JavaScript"]
  # Test logic
end

# This creates unnecessary duplication. RSpec provides hooks to solve this problem.
Understandletvsbefore
This distinction is particularly important.
before
let
Setup hook
Defines a helper method
Executes automatically
Executes only when referenced
Runs before every example by default
Evaluates once per example
Useful for setup actions
Useful for reusable test data
afterhook: after executes after each example.
after(:each) do
  puts "Cleaning up"
end
Typical use cases:
Cleaning up temporary resources.
Restoring modified environment variables.
Closing external resources.
Removing temporary files.
RSpec Rails and transactional tests will handle much of our database cleanup automatically, so we shouldn’t manually delete every test record in after
let– lazy evaluation
Let’s understand its behaviour: let(:languages) { ["Ruby", "JavaScript", "Python"] } . And if you call it multiple times within the same example, RSpec reuses its cached value. This is called lazy evaluation and memoization.
Hands-on exercise
Let’s create another learning spec: touch spec/learning/rspec_setup_hooks_spec.rb
RSpec.describe "RSpec setup hooks" do
  let(:execution_log) { [] }

  let(:languages) do
    execution_log << :languages_created
    ["Ruby", "JavaScript", "Python"]
  end

  before(:each) do
    execution_log << :before_hook
  end

  # Write your examples here
  it "Test lazy evaluation" do
    puts "execution_log: #{execution_log}"
  end

  it "Access let variable and check lazy evaluation when referenced" do
    expect(languages).to include("Ruby")
    puts "execution_log: #{execution_log}"
  end

  it "Access let variables twice within this example and verify lazy loading" do
    expect(languages).to include("Python")
    expect(languages).not_to include("Rust")
    puts "execution_log: #{execution_log}"
  end
end
We’ll now cover three important RSpec concepts that you’ll use extensively when writing Rails model specs and request specs:
let! – eager evaluation.
subject – defining the primary object under test.
before(:all) vs before(:each) – setup lifecycle and execution order.
RSpec execution lifecycle
1.letvslet!
We already understand let. let!(:user) { "Abhilash" } The ! changes the behaviour.
# let - Lazy

Start example
    |
    v
Before hook
    |
    v
Execute example
    |
    v
Access user?
   /    \
  Yes     No
  |       |
Evaluate  Never
# let! - Eager

Start example
    |
    v
Execute let! setup
    |
    v
Before hooks (according to declaration order)
    |
    v
Execute example
Technically, let! is implemented by defining a let helper and registering a before hook that invokes it.
When should we uselet!?
Consider a Rails model spec. Suppose we want to test whether a user has three tasks. We need those three tasks to exist before the example executes. This is a good use case for let!. let!(:task) { create(:task) }
We’ll eventually use FactoryBot’s create method here.
My recommendation: Prefer let by default. Use let! when the setup must happen before the example, regardless of whether the helper is explicitly accessed.
2.subject– the primary object under test
This is another important RSpec concept. Suppose we’re testing a method that normalizes a task title. Instead of repeatedly creating or referencing the main result, we can define it using subject.
subject(:normalized_title) do
  title.strip.downcase
end
Now we can use: expect(normalized_title).to eq("learn rails")
Why usesubject?
Imagine testing a Task model with many examples. The primary object being tested is usually a Task instance. We can define:
subject(:task) do
  Task.new(title: "Learn Rails")
end
Then use: expect(task).to be_valid
Notice the difference:
let
subject
Defines reusable test data
Defines the primary object under test
Can define multiple helpers
Usually one primary subject per example group
Access using its name
Access using its name or subject
Lazy and memoized
Lazy and memoized
A named subject such as subject(:task) also creates a helper called task.
What is the implicit subject?
RSpec also provides a default subject. For example:
RSpec.describe Array do
  it "starts empty" do
    expect(subject).to be_empty
  end
end
When the described class is an Array, RSpec’s implicit subject is a new instance of that class. You can also explicitly use: subject { described_class.new }
described_class refers to the class being tested.
Best practice: Prefer named subjects when they improve readability, especially in model specs.
3.before(:each)vsbefore(:all)
This is particularly important when working with database records.
Hook
Execution
State
before(:each)
Before every example
Isolated per example
before(:all)
Once before the example group
Shared across examples
before without arguments is equivalent to before(:each).
Example: before each
before(:each) do
  puts "Before each example"
end
Suppose there are three examples. Output:
Before each example
Example 1

Before each example
Example 2

Before each example
Example 3
Example: before all
before(:all) do
  puts "Before all examples"
end
Output:
Before all examples

Example 1
Example 2
Example 3
Important: Be careful withbefore(:all)and ActiveRecord
This is something I want you to remember for Rails development. RSpec Rails normally manages database transactions around individual examples. before(:all) runs outside that normal per-example transaction lifecycle. Consequently, database records created in before(:all) can leak between examples or require manual cleanup.
It can also result in shared mutable objects, making tests order-dependent.
My recommendation: For our Rails model and request specs, prefer let, let! and before(:each).
Use before(:all) only when you have a specific reason and understand its lifecycle implications.
Understand hook execution order
Suppose we have:
RSpec.describe "Outer" do
  before do
    puts "Outer before"
  end

  describe "Inner" do
    before do
      puts "Inner before"
    end

    it "runs example" do
      puts "Example"
    end
  end
end
What do you think the output will be?
It is: Outer before → Inner before → Example
The general rule is:
Parent group hooks run before nested group hooks.
Hooks registered within the same group run in declaration order.
let! internally registers a before hook at the point where it is declared, so declaration order can matter.
Practical assignment
Let’s combine what we’ve learned.
Let’s create another learning spec: touch spec/learning/rspec_lifecycle_spec.rb Implement the following exercises.
Exercise 1 –let!
Create an execution log. Define one let and one let!. Both should append different symbols to the execution log when evaluated.
Write an example verifying that:
The let! value is evaluated before the example.
The let value is not evaluated until referenced.
Exercise 2 –subject
Define a named subject called normalized_title. Its implementation should remove leading/trailing whitespace and convert a string to lowercase.
RSpec.describe "Test rspec lifecycle hooks" do
  let(:execution_log) { [] }
  let(:title) { "  LEARN RSPEC  " }

  subject(:normalized_title) do
    execution_log << :subject_executed
    puts "subject execution_log: #{execution_log}"
    title.downcase.strip
  end

  let(:animal) do
    execution_log << :animal
    "Lion"
  end

  let!(:bird) do
    execution_log << :bird
    "Eagle"
  end

  describe "let and let!" do
    it "test let! evaluation" do
      expect(execution_log.count(:animal)).to eq(0)
      expect(execution_log.count(:bird)).to eq(1)
      expect(execution_log.count(:subject_executed)).to eq(0)
    end
  end

  describe "test subject lazyness" do
    it "call subject and check the counter" do
      normalized_title
      subject
      expect(execution_log.count(:subject_executed)).to eq(1)
    end
  end

  before do
    p "Outer hook"
  end

  describe "Test hook ordering" do
    before do
      p "Inner hook"
    end
    it "test inner hook" do
      expect(execution_log.count(:subject_executed)).to eq(0)
      expect(execution_log.count(:animal)).to eq(0)
      expect(execution_log.count(:bird)).to eq(1)
    end
  end
end
This is a good demonstration of eager versus lazy evaluation.
Remember this distinction:
Location
Syntax
Declaration
subject(:normalized_title) { ... }
Access inside example
normalized_title
Access using default name
subject
A few observations before moving on:
subject(:normalized_title) is lazy. It executes only when accessed.
Calling normalized_title and then subject accesses the same memoized subject. The block executes only once per example.
let!(:bird) executes automatically before each example, including examples in nested groups.
let(:animal) never executes in your current examples because you don’t access it.
Ruby 4.0 introduced two fascinating runtime capabilities:
Ractors, significantly improved for parallel execution
Ruby Box, an experimental mechanism for isolating definitions inside one Ruby process
For a Rails developer, the obvious question is:
Can I take my existing Rails application and simply add Ractors and Ruby Box to make it faster or more scalable?
The answer is not yet that simple.
Ractors can be extremely useful for carefully isolated CPU-heavy work, but a conventional Rails application is deeply interconnected through global state, constants, classes, ActiveSupport, ActiveRecord, gems, configuration and caches.
Ruby Box is a completely different concept. It is not primarily a parallelism mechanism. It provides in-process isolation of definitions and loaded code, with potential applications such as running multiple application versions in one Ruby process. Ruby 4.0 documents it as experimental.
Let’s look at both from a Rails perspective.
1. First: what problem does a Ractor solve?
A normal Ruby thread looks roughly like this:
Rails process
│
├── Thread 1
├── Thread 2
├── Thread 3
└── Thread 4
│
└── same Ractor / same GVL
Threads within a Ractor still share that Ractor’s GVL, so they don’t execute Ruby code in parallel with one another.
Ractors change the model:
Rails process
│
├── Ractor A ── GVL ── Thread(s)
│
├── Ractor B ── GVL ── Thread(s)
│
└── Ractor C ── GVL ── Thread(s)
Different Ractors can execute Ruby code in parallel on different CPU cores. Ruby 4.0 also reduced internal contention and introduced Ractor::Port for communication.
That makes Ractors especially interesting for CPU-bound work.
2. What should NOT be your first Ractor experiment?
Suppose you have:
class ReportsController < ApplicationController
  def show
    @report = Report.generate
  end
end
It is tempting to write:
def show
  r = Ractor.new do
    Report.generate
  end

  @report = r.value
end
This is exactly the kind of approach that exposes the biggest problem.
A Rails application has a huge amount of shared framework state.
For example:
Rails
│
├── ActiveSupport
├── ActiveRecord
├── Zeitwerk
├── configuration
├── caches
├── logging
├── autoloading
├── class/module definitions
└── gems
Ractors deliberately restrict access to non-shareable objects across Ractors.
The Ruby documentation says that most objects are unshareable and communication between Ractors is intended to happen through shareable objects or message passing.
That makes a normal Rails application a poor candidate for simply wrapping arbitrary Rails calls inside Ractor.new.
There has also been a real Rails issue demonstrating Ractor::IsolationError when attempting to instantiate or use Rails application state from a non-main Ractor.
3. The better idea: use Ractors around isolated computation
Instead of:
Ractor
↓
Entire Rails application
think:
Rails
│
├── request
│
├── database work
│
└── isolated CPU calculation
↓
Ractor
For example, imagine a report containing millions of values.
class ReportCalculator
  def self.calculate(numbers)
    numbers.sum { |n| expensive_calculation(n) }
  end

  def self.expensive_calculation(n)
    # CPU-heavy calculation
    n ** 3
  end
end
You could partition the data:
chunks = numbers.each_slice(10_000).to_a

ractors = chunks.map do |chunk|
  Ractor.new(chunk) do |values|
    values.sum { |n| n ** 3 }
  end
end

result = ractors.sum(&:value)
The important architectural boundary is:
Rails
│
│ plain data
▼
Ractor 1 ── CPU work ──┐
Ractor 2 ── CPU work ──┼──→ results
Ractor 3 ── CPU work ──┘
│
▼
Rails
This is much more promising.
The Ractors don’t need to manipulate:
ActiveRecord::Relation
Rails.application
ActiveSupport::Cache
Controller
request
response
They receive isolated data and return isolated results.
4. A practical Rails use case: analytics
Imagine:
orders=Order
.where(created_at:30.days.ago..)
.pluck(:amount)
The database query happens normally.
Then:
chunks = orders.each_slice(50_000).to_a

ractors = chunks.map do |chunk|
  Ractor.new(chunk) do
    {
      total: chunk.sum,
      average: chunk.sum.to_f / chunk.length
    }
  end
end

results = ractors.map(&:value)

total = results.sum { |r| r[:total] }
The database remains Rails’ responsibility.
The CPU-heavy aggregation becomes parallel work.
That is the mental model I’d recommend:
Use Rails for orchestration; use Ractors for isolated computation.
5. Another good candidate: document/image processing
Suppose your application performs CPU-heavy transformations:
PDF
↓
parse
↓
transform
↓
calculate
↓
generate result
Instead of letting one Ruby execution stream process everything:
Rails
│
└── CPU-heavy processing
you can potentially build:
                    Rails
                      │
               Job / Service
                      │
          ┌───────────┼───────────┐
          ▼           ▼           ▼
       Ractor      Ractor      Ractor
         │           │           │
       file A      file B      file C
          └──────────┬──────────┘
                     ▼
                   result
The same principle applies to:
compression
large JSON transformations
encryption-related computation
parsing
ranking/scoring
simulations
large in-memory calculations
The exact benefit depends heavily on whether the work is CPU-bound and whether the cost of copying/moving data outweighs the parallelism benefit.
Ruby’s Ractor documentation explicitly notes that unshareable objects may be copied or moved between Ractors, so data-transfer overhead must be considered.
6. Ractor is not a replacement for ActiveJob
It is important not to confuse these abstractions.
For example:
SomeJob.perform_later(order.id)
and:
Ractor.new(...)
solve different problems.
ActiveJob/Sidekiq/GoodJob/etc. solve background job execution and process-level application architecture.
Ractors solve parallel execution inside one Ruby process.
You could potentially combine them:
Rails
│
▼
Background Job
│
▼
Ruby Process
│
├── Ractor 1
├── Ractor 2
├── Ractor 3
└── Ractor 4
But this is an advanced optimization, not the default architecture.
7. So where does Ruby Box fit?
Ruby Box is much less about CPU parallelism.
Its purpose is definition isolation.
Suppose you have:
classUser
defrole
"admin"
end
end
Now imagine loading another piece of code that reopens User:
classUser
defrole
"guest"
end
end
Normally, that’s a global change to the Ruby process.
Ruby Box lets those definitions exist in separate boxes.
Conceptually:
Ruby process
│
├── Main box
│ └── User#role → "admin"
│
└── Box B
└── User#role → "guest"
Ruby’s documentation describes this as isolation of class/module definitions, monkey patches, constants, global/class variables and loaded Ruby/native libraries.
This is a very different problem from Ractors.
8. A simple Ruby Box example
Ruby Box must be enabled at process startup:
RUBY_BOX=1 ruby app.rb
Setting the variable after Ruby has already started does not enable it.
Then:
box=Ruby::Box.new
box.require("./legacy_user.rb")
Suppose legacy_user.rb contains:
classUser
defrole
"legacy"
end
end
The definition is loaded into the box.
Conceptually:
Main box
│
└── User
Legacy box
│
└── User
└── role → "legacy"
The definition in the box is isolated from the corresponding definition in other boxes. Ruby’s documentation demonstrates this with constants, classes and methods.
9. This has a fascinating Rails use case: blue-green application versions
This is one of the use cases Ruby itself proposes.
Imagine:
One Ruby process
┌─────────────────────────────┐
│ Ruby Process │
│ │
│ Box A │
│ Rails App v1 │
│ │
│ Box B │
│ Rails App v2 │
└─────────────────────────────┘
Ruby 4.0 explicitly lists running web-app boxes in parallel as a potential blue-green deployment use case.
Theoretically, this gives you the ability to have:
/app-v1
/app-v2
loaded in separate definition environments inside the same Ruby process.
Then requests could be directed to:
traffic
│
├──→ Box A
│
└──→ Box B
This could eventually enable interesting deployment and migration strategies.
But there is a huge caveat.
10. Ruby Box is experimental
This is not currently something I’d take into a normal Rails production deployment simply because Ruby 4 has it.
The official documentation lists known issues, including:
Keep Rails state out of the Ractors wherever possible.
Design explicit boundaries:
input= {
values:values,
options:options
}
rather than:
ractor=Ractor.newdo
Order.where(...)
end
The first is an isolated computation.
The second makes the Ractor responsible for Rails state.
That’s where the complexity explodes.
13. How I would introduce Ractors into an existing Rails app
Start with one measurable CPU bottleneck.
For example:
Before
request
↓
large calculation
↓
1 CPU core
↓
response
Then extract:
classPricingCalculator
defself.calculate(input)
# pure Ruby calculation
end
end
Make it as pure as possible:
result=PricingCalculator.calculate(
prices:prices,
rules:rules
)
Then experiment with:
Ractor.new(input) do |data|
PricingCalculator.calculate(data)
end
Benchmark both:
single-threaded
vs
multiple Ractors
Don’t assume parallelism automatically means faster execution.
You need to measure:
CPU time
wall-clock time
memory usage
object copying
Ractor startup
throughput
latency
14. Rails architecture: where each feature fits
A useful mental model is:
                    Rails
                      │
     ┌────────────────┼─────────────────┐
     │                │                 │
     ▼                ▼                 ▼
   Web              Data             Jobs
     │                │                 │
     └────────────────┴────────┐        │
                               ▼        ▼
                       Application services
                               │
                       CPU-heavy workload
                               │
                         ┌─────┴─────┐
                         ▼           ▼
                      Ractor      Ractor
Ruby Box sits at a different architectural layer:
Ruby Process
│
├── Main / Application Box
│
├── Application Box A
│
└── Application Box B
So:
Ractor = parallel execution
while:
Ruby Box = definition/environment isolation
They solve different problems.
15. The big Rails limitation today
This is the part worth remembering.
A conventional Rails application is built around a substantial amount of shared application state.
That doesn’t fit naturally with Ractor’s isolation model.
There has been an explicit Rails issue requesting Ractor support and that issue was closed as “not planned.” The discussion showed Ractor::IsolationError arising from Rails class-level state.
That architecture gives you a much better chance of benefiting from parallel Ruby.
For Ruby Box:
Development/testing first
↓
isolated definitions
↓
experimentation
↓
specialized deployment scenarios
rather than immediately attempting:
"Let's run the whole Rails app in 10 Ruby Boxes."
Final takeaway
Ruby 4 did something more interesting than simply making threads faster.
It is giving Ruby developers more explicit runtime tools:
Ractor
↓
parallel Ruby computation
Ruby Box
↓
isolated Ruby definitions
YJIT / ZJIT
↓
faster execution
GC/runtime improvements
↓
less overhead
For Rails, however, the winning strategy isn’t:
“Convert Rails to Ractors.”
It is:
“Keep Rails responsible for application orchestration and isolate carefully chosen CPU-heavy computations behind Ractor boundaries.”
And Ruby Box is even more experimental.
Its long-term Rails potential may actually be more architectural than performance-oriented: isolating application versions, tests, plugins, or dependency environments inside one Ruby process.
The exciting thing is that Ruby 4 gives us primitives that make these designs possible.
The engineering challenge is deciding where the boundary belongs.
That is ultimately the same lesson we’ve been following through this series:
Ruby gives us abstractions. Understanding the runtime lets us decide when to cross them.
A useful next post in this series would be “Ractor vs Thread vs Process in Rails: when should a senior Rails developer choose each?” – with real benchmarks, memory/CPU trade-offs and a Sidekiq/Puma/Ractor architecture comparison.
If you have been developing Rails applications for years, there’s a good chance you’ve used:
bin/rails credentials:edit
hundreds of times.
You probably know that Rails stores encrypted credentials in:
config/credentials.yml.enc
and keeps the encryption key separately in:
config/master.key
But did you know that Rails can make:
git diff
show the decrypted, human-readable changes to credentials.yml.enc?
I recently discovered this while working on a Rails 8.1.3.1 application and it was one of those:
“I’ve been using Rails every day for years, and I didn’t know Rails could do this!”
moments.
Let’s see how it works.
First: What is credentials.yml.enc?
Rails encrypted credentials allow us to keep secrets such as:
openai:
  api_key: ...
or:
aws:
  access_key_id: ...
  secret_access_key: ...
inside:
config/credentials.yml.enc
The file is encrypted.
The encryption key is stored separately in:
config/master.key
Rails documentation explicitly states that the encrypted credentials file can be stored in version control as long as the master key remains secure. (Ruby on Rails Guides)
So our repository can contain:
config/
├── credentials.yml.enc ← encrypted, safe to commit
└── master.key ← secret, NEVER commit
Editing Rails Credentials
Normally we edit credentials with:
bin/rails credentials:edit
Rails decrypts the credentials, opens them in your configured editor, and encrypts them again when you save.
Rails then ensures the Git diff driver is configured to use:
bin/rails credentials:diff
Rails’ application generator includes this credentials diff enrollment as part of application setup and Rails 7.0 already contained the credentials diffing implementation. (Gem)
So this isn’t actually an 8.1-only feature.
That’s an important distinction.
Is This New in Rails 8.1?
No – and this is an important correction.
The encrypted credentials diff functionality existed before Rails 8.1.
For example, Rails 7.0 already had the credentials:diff implementation, and Rails 7.2’s application generator also enrolled projects in credentials diffing. (Gem)
Rails has supported decrypted Git diffs for encrypted credentials for several versions and Rails 8.x continues to build on the credentials tooling.
Rails 8.1 does introduce other useful credentials functionality. For example, Rails 8.1 added command-line credential fetching, which can be useful for deployment tooling such as Kamal. (Ruby on Rails Guides)
The master key should not be committed. Rails’ security guide explicitly recommends keeping the master key safe and out of version control. (Ruby on Rails Guides)
One Thing to Remember
The decrypted content can appear in your local terminal output.
The difference is a great way to understand what’s really happening.
Quick Reference
# Edit credentials
bin/rails credentials:edit

# Enroll project in credential diffing
bin/rails credentials:diff --enroll

# Normal readable diff
git diff

# Show the actual encrypted file diff
git diff --no-textconv -- config/credentials.yml.enc

# Inspect Git's configuration
git config --show-origin --get-regexp 'diff|textconv|filter'

# Check Git attributes
git check-attr diff -- config/credentials.yml.enc
Security rule:
 Y config/credentials.yml.enc → commit it
 X config/master.key          → NEVER commit it
Rails’ official security guide confirms that encrypted credentials can be stored in version control while the master key must remain protected. (Ruby on Rails Guides)
Testing is a critical part of building reliable web applications. However, choosing the right testing tools and deciding what to test at each layer can be confusing, especially when working with Ruby on Rails, React and separate API services.
In this guide, we’ll cover four types of tests, Rails examples, browser automation tools and a recommended testing architecture for modern web applications.
1. Understanding the Four Types of Tests
A good testing strategy uses different testing layers rather than testing everything through a browser.
1. Unit Tests
Purpose: Test a small, isolated piece of business logic.
Examples include price calculations, validations, discount rules, and service objects.
# app/services/discount_calculator.rb
class DiscountCalculator
  def self.apply(price:, percent:)
    price * (100 - percent) / 100.0
  end
end
RSpec example:
RSpec.describe DiscountCalculator do
  it "calculates a discounted price" do
    result = described_class.apply(
      price: 100,
      percent: 10
    )

    expect(result).to eq(90)
  end
end
Characteristics:
Fast and easy to debug.
Tests business rules independently.
Usually avoids databases, network calls, and browsers.
Unit tests provide a strong foundation for an application, but they cannot prove that all components work together.
2. Integration and Request Tests
Purpose: Verify that multiple components work together correctly.
In Rails, request specs are especially useful for testing API endpoints, HTTP status codes, response bodies, authorization, and database side effects.
# spec/requests/api/products_spec.rb
RSpec.describe "GET /api/products", type: :request do
  it "returns products as JSON" do
    product = create(:product, name: "Trail Shoes")

    get "/api/products"

    expect(response).to have_http_status(:ok)

    json = JSON.parse(response.body)

    expect(json.map { |item| item["id"] })
      .to include(product.id)
  end
end
This tests the HTTP request and response through Rails, without opening a browser.
Other important scenarios include:
Authentication and authorization.
Invalid parameters and validation errors.
Database interactions.
API error handling and response formats.
Characteristics: More realistic than isolated unit tests, generally faster and less brittle than browser tests.
RSpec supports model, request, job, mailer, system, and other spec types. Therefore, RSpec is not limited to unit testing. See the RSpec Rails documentation.
3. Frontend Component Tests
Purpose: Test individual UI components and their user-visible behavior.
For a React frontend, you can use Vitest with React Testing Library.
For example, a search component should display matching results or an appropriate empty state when users search.
import { render, screen } from "@testing-library/react";
import { describe, it, expect } from "vitest";
import SearchMessage from "./SearchMessage";

describe("SearchMessage", () => {
  it("shows an empty-state message", () => {
    render(<SearchMessage results={[]} />);

    expect(
      screen.getByText("No products found")
    ).toBeInTheDocument();
  });
});
This assumes SearchMessage renders the specified text when its results array is empty and that the testing dependencies are configured.
Component tests are useful for:
Form validation and error messages.
Loading and empty states.
Button interactions.
Rendering based on props and state.
They usually do not require a real browser or a running Rails API.
Purpose: Test a complete user journey through a real browser.
For example:
User signs in.
Searches for a product.
Adds it to the cart.
Completes checkout.
Sees an order confirmation.
These tests can detect integration problems across the frontend, backend, browser, and database that isolated tests may miss.
However, they are generally slower and require more setup. Consequently, you should prioritize critical workflows instead of testing every button or input through a browser.
❓ 2. Is RSpec the Best Testing Framework for Enterprise Applications?
This assumption is partly correct.
RSpec is popular in Rails applications because it offers an expressive testing DSL, useful matchers, shared examples, mocking support, and a mature ecosystem. These features can make tests easier to write and maintain.
However, there are two important distinctions.
First, RSpec is not the same as unit testing.
You can use RSpec for all of these:
Unit tests.
Request and integration tests.
Background job tests.
Browser-based system tests.
A project may use RSpec extensively but have very few isolated unit tests. For example, if most specs exercise HTTP endpoints, its test suite may be heavily integration-oriented.
Second, RSpec is not automatically faster than other testing frameworks.
Rails includes Minitest by default. Both Minitest and RSpec can support maintainable, comprehensive test suites. Overall execution time depends heavily on database setup, test isolation, factories, external services, parallelization, and the proportion of browser tests.
The best choice is the framework that fits your team’s conventions, expertise, and application requirements.
3. Puppeteer vs. Rails System Tests
Puppeteer is a JavaScript library for controlling browsers programmatically. It can automate clicks, form submissions, page navigation, screenshots, and other browser activities.
It is not a Rails testing framework.
What is the equivalent in Rails?
There is no exact one-to-one replacement, but the closest built-in Rails equivalent is system testing using Capybara and a browser driver.
Rails system tests integrate browser automation with your Rails testing environment. You can interact with links, forms, buttons, JavaScript behavior, and page content.
Example:
# spec/system/product_search_spec.rb
RSpec.describe "Product search", type: :system do
  it "shows matching products" do
    create(:product, name: "Trail Shoes")

    visit "/products"

    fill_in "Search", with: "Trail"
    click_button "Search"

    expect(page).to have_text("Trail Shoes")
  end
end
This example assumes a server-rendered Rails page with a search field labeled “Search” and a corresponding button.
In an RSpec project, configure system specs with Capybara and an appropriate browser driver, such as Selenium. Other supported driver integrations are available.
These tools are not all direct competitors. For example, RSpec and Playwright can be used in the same project because they test different layers.
❓ 4. What Is Playwright and When Should You Use It?
Playwright is a browser automation and testing framework. It supports Chromium, Firefox, and WebKit, and provides a test runner, assertions, browser contexts, and automatic waiting for many browser actions.
This makes it especially useful for modern JavaScript applications.
Playwright is a strong default for E2E tests in this architecture because it can run independently of the Rails testing framework and interact with the deployed or locally running React application.
For example, a Playwright test might open the React application, enter a search term, verify the displayed products, add one to the cart, and complete a checkout flow against a test Rails API.
You can still use Rails system tests if you prefer a Ruby-based browser-testing workflow. However, Playwright often provides a more natural fit when the frontend is a separately developed React application.
My preference: Use RSpec for backend behavior and Playwright for critical cross-application browser journeys. Avoid duplicating every backend test in Playwright.
❓ 5. Are Browser Tests, System Tests and E2E Tests the Same?
This terminology causes considerable confusion because different tools and teams use these terms differently.
Browser test: A broad term for a test that drives an actual browser.
System test in Rails: A Rails testing category that exercises the application through a browser, typically using Capybara.
E2E test: A test that validates a complete workflow across the components involved in that workflow.
A Rails system test that signs in, purchases a product, and verifies the confirmation page is also an E2E test in the broader sense.
Likewise, a Playwright test can be an E2E test.
Not every browser test must be a full E2E test. For example, a browser test might verify that a dropdown opens correctly without exercising the backend.
Remember that system testing is a specific Rails testing facility, whereas E2E describes the scope and purpose of a test.
☑️ 6. Recommended Testing Architecture
For a typical production web application, I recommend the following strategy:
Layer
Tool
Priority
Unit
RSpec
High
Integration / API
RSpec request specs
High
Frontend components
Vitest + Testing Library
High for substantial JS frontends
E2E browser workflows
Playwright or Rails system tests
Critical user journeys
A practical CI strategy is:
Run unit, request, and component tests on every pull request.
Run a small set of critical E2E tests on every pull request when execution time permits.
Run broader browser coverage, including additional browser engines where required, on a scheduled or pre-release basis.
Scan dependencies and run relevant security checks as part of CI.
The goal is not to maximize the number of tests. The goal is to catch defects quickly and reliably at the lowest reasonable level.
For example, test twenty discount calculation edge cases with unit tests rather than maintaining twenty browser tests for the same business rules. Then use a few E2E tests to prove that the essential shopping journey works.
🎯 The Conclusion
For a conventional Rails application, RSpec with request specs and a carefully selected set of system tests can be sufficient.
For a React + Rails API application, I recommend:
RSpec for business logic and backend integration.
Vitest + React Testing Library for frontend components.
Playwright for important E2E journeys.
Puppeteer is also capable of browser automation, but there is no need to introduce it merely because it is popular in JavaScript projects.
The best testing architecture is a balanced suite that verifies business rules, API behavior, frontend interactions, and critical end-to-end workflows without making every test expensive to maintain.
For this specific project, I recommend a single Git repository containing two applications:
rails_react_user_management/
├── backend/      # Rails API
└── frontend/     # React + Vite
This is cleaner than forcing Vite into Rails views because we explicitly want an API-only Rails backend. React’s current guidance supports using Vite as a build tool when building React from scratch, and Vite has a first-class Rails integration, but that integration is more useful when Rails is also serving the frontend. (React)
For our learning project, we’ll therefore keep the frontend and backend clearly separated while keeping them in one repo.
1. Prerequisites
Check:
ruby -v
rails -v
node -v
npm -v
Current Vite requires Node.js 20.19+ or 22.12+. (vitejs)
2. Create the Rails API
mkdir rails_react_user_management
cd rails_react_user_management

rails new backend --api -d postgresql
cd backend
The important part is:
--api
This tells Rails to create an API-only application rather than a traditional Rails application with views/assets. That’s exactly what we want.
Create the database:
bin/rails db:create
Start Rails:
bin/rails server
API:
http://localhost:3000
3. Create our User API
Let’s create a simple User model:
bin/rails generate model User name:string email:string
bin/rails db:migrate
Create controller:
bin/rails generate controller Users
app/controllers/users_controller.rb:
class UsersController < ApplicationController
  def index
    render json: User.all
  end

  def show
    render json: User.find(params[:id])
  end

  def create
    user = User.create!(user_params)
    render json: user, status: :created
  end

  private

  def user_params
    params.require(:user).permit(:name, :email)
  end
end
Routes:
# config/routes.rb

Rails.application.routes.draw do
  scope "/api" do
    resources :users
  end
end
React’s documentation currently recommends a build tool such as Vite when building a React application from scratch and Create React App is deprecated. (React)
Then we’ll add React Router, reusable components, forms, CRUD, loading/error states, custom hooks, useContext, Redux Toolkit, API abstraction, authentication, pagination, optimistic updates, testing, and production deployment.
For the int., the important architectural distinction is:
Rails is the API/backend and React is the client application. Vite is the frontend development/build tool.
Vite provides the development server and production build pipeline; its current production build uses Rolldown and outputs optimized static assets. (vitejs)
Next, we should implement the actual User Management UI – User list + Add User + Edit + Delete – using proper React components and API calls, because that will give you the hands-on React knowledge needed for the int.
Q) The request inside the useEffect is firing 2 times. App.jsx line 9: fetch("/api/users") Why?
This is most likely happening because React StrictMode intentionally runs useEffect twice in development to help identify bugs in your components.
The above screenshot shows two successful GET /api/users requests, which matches this behavior.
1. Check main.jsx
Open frontend/src/main.jsx. The Vite React template typically wraps your app in StrictMode:
import { StrictMode } from "react";
import { createRoot } from "react-dom/client";
import App from "./App.jsx";

createRoot(document.getElementById("root")).render(
  <StrictMode>
    <App />
  </StrictMode>
);
Because of StrictMode, React performs an extra effect setup-and-cleanup cycle when mounting components in development.
Even though the dependency array is empty ([]), the effect runs twice during the initial development mount under StrictMode.
2. Does this happen in production?
No. React’s extra StrictMode effect cycle is development-only. A production build does not perform this extra cycle.
3. Int. takeaway
Remember these three points:
useEffect(..., []) normally runs on initial mount, not after every render.
StrictMode deliberately runs an extra effect setup-and-cleanup cycle in development.
Effects involving network requests should handle cleanup, errors, and cancellation where appropriate.
For our Rails + React application, keep StrictMode enabled. This behavior is expected during development and is not evidence that your Rails API or Vite proxy is incorrectly configured.
If you are building AI features into a Rails, Node.js, Python, or any other application, you quickly run into a practical problem:
Which AI model should I use?
OpenAI? Claude? Gemini? DeepSeek? Llama? Mistral?
And what happens when your chosen provider is expensive, rate-limited, unavailable, or simply not the best model for a particular task?
This is where OpenRouter becomes interesting.
OpenRouter provides a unified API for accessing hundreds of AI models through a single interface. It follows an OpenAI-compatible API style, so applications using the OpenAI SDK can often switch to OpenRouter with very little code change. (OpenRouter)
What is OpenRouter?
Think of OpenRouter as an AI gateway/router sitting between your application and multiple LLM providers.
Instead of:
Your Application
      |
      +----> OpenAI
      |
      +----> Anthropic
      |
      +----> Google
      |
      +----> DeepSeek
you can have:
Your Application
      |
      v
  OpenRouter
      |
      +----> OpenAI
      +----> Anthropic
      +----> Google
      +----> DeepSeek
      +----> Meta
      +----> Other providers
Your application talks to one API, while OpenRouter handles access to the underlying models and providers.
It currently exposes hundreds of models through its API, and the available catalog can be queried programmatically. (OpenRouter)
Why would a developer use it?
The biggest advantage isn’t simply “many models.”
The real advantage is reducing coupling to a single AI provider.
Imagine your Rails application has:
MODEL="some-expensive-model"
Six months later you discover that another model:
performs better for your use case
costs less
has better latency
has higher availability
With a direct provider integration, changing providers can involve SDKs, authentication, request formats, response formats and application-specific code.
With OpenRouter, the model is largely a configuration decision:
MODEL="provider/model-name"
That makes experimentation much easier.
Practical Example: OpenAI-Compatible API
One of the most useful features is OpenAI API compatibility.
For example, using the OpenAI Ruby client, the important difference is the base_url:
The exact Ruby client API can vary by gem version, but the architectural idea is simple:
Keep your application code mostly unchanged and change the endpoint/model configuration.
OpenRouter officially documents using the OpenAI SDK with its API by changing the baseURL to the OpenRouter endpoint. (OpenRouter)
Which ruby gem to use?
1. The Recommended Path: The Official openai Gem (Drop-in Compatibility)
# AI assistant - OpenAI
gem "openai", "< 2.0"
Because OpenRouter mirrors OpenAI’s API structure, the easiest and most stable approach is to use the popular official-adjacent openai gem. You simply swap out the base_url and pass your OpenRouter API key.
My Current Rails Implementation is given below (Edited)
While OpenRouter does not maintain an official, first-party SDK exclusively for Ruby, its API is fully OpenAI-compatible. This gives you three simple ways to integrate OpenRouter into a Ruby application
You can test the same prompt against different models without building three separate integrations.
This is particularly useful during development.
For example:
Task: Generate SQL query from natural language

Model A → Good accuracy, expensive
Model B → Very good accuracy, cheaper
Model C → Fast, acceptable accuracy
Instead of making a permanent decision immediately, you can benchmark them.
That’s a much better engineering approach than blindly choosing a model because it is popular.
This is one of the features I find particularly useful for production systems.
Suppose your primary model is temporarily:
Rate limited
        ↓
Provider outage
        ↓
Model unavailable
OpenRouter can automatically try another model/provider according to your routing configuration. (OpenRouter)
For example:
models:[
"primary-model",
"fallback-model-1",
"fallback-model-2"
]
If the first model fails, OpenRouter can attempt the next one.
This turns your AI integration from:
Application → One AI Provider
into something closer to:
Application
     |
     v
OpenRouter
     |
     +---- Primary
     |
     +---- Fallback
     |
     +---- Another fallback
For production applications, that resilience can be more important than simply having access to many models.
Provider Routing
There is another layer that is easy to overlook.
A model may be available through multiple providers.
OpenRouter can route requests between providers and allows developers to influence routing based on things such as provider order, price, throughput and latency. (OpenRouter)
For example, if your application cares primarily about speed, routing can be configured to prefer higher-throughput providers.
If cost is the priority, you can prioritize price.
That means your architecture can move from:
Use Model X
towards:
Use Model X
through the provider that currently makes the most sense
That is a much more interesting abstraction for production AI systems.
What About Cost?
OpenRouter doesn’t magically make every model free.
The underlying model still has its own pricing.
OpenRouter says it passes through provider pricing while providing unified billing and routing. (OpenRouter)
However, OpenRouter also exposes free models.
For example:
openrouter/free
is available as a free-model option, subject to the applicable limits. (OpenRouter)
This is particularly useful when learning or experimenting.
For example, instead of spending money while learning AI API integration:
Rails App
   ↓
OpenRouter
   ↓
Free/low-cost model
You can first build the feature, understand the API, streaming, prompts and error handling, and only later move to a more capable paid model.
Important: free does not mean unlimited. OpenRouter documents rate limits for free models, and those limits depend on account/credit conditions. (OpenRouter)
🏗️ A Good Architecture for Rails
For a Rails application, I wouldn’t scatter OpenRouter calls throughout controllers.
Instead, create an abstraction:
class AiClient
  def initialize
    @client = OpenAI::Client.new(
      access_token: ENV["OPENROUTER_API_KEY"],
      base_url: "https://openrouter.ai/api/v1"
    )
  end

  def ask(prompt)
    @client.chat(
      parameters: {
        model: ENV.fetch("AI_MODEL"),
        messages: [
          { role: "user", content: prompt }
        ]
      }
    )
  end
end
Then your application does:
response=AiClient.new.ask(
"Summarize this customer feedback"
)
The model becomes configuration:
AI_MODEL=provider/model-name
Now changing the model doesn’t require changing business logic.
That’s the pattern I would recommend for a production Rails application.
Where OpenRouter Makes the Most Sense
I would consider OpenRouter when:
1. You are experimenting with multiple LLMs
You don’t want to build five separate integrations just to compare models.
2. You want provider flexibility
Your application shouldn’t become tightly coupled to one AI company unless there is a strong reason.
3. You need fallback strategies
AI APIs can experience rate limits and provider outages. Model/provider fallback can improve resilience. (OpenRouter)
4. You are cost-conscious
You can compare models and route workloads according to cost/performance requirements.
5. You are building an AI abstraction layer
For example:
Rails Application
       |
       v
    AiClient
       |
       v
   OpenRouter
       |
   +---+---+---+
   |   |   |   |
  GPT Claude Gemini DeepSeek
Your business logic doesn’t need to know which provider actually processed the request.
Should You Always Use OpenRouter?
No.
There are situations where going directly to the provider makes more sense.
For example, if your application is deeply dependent on provider-specific features, you may want the official SDK/API directly.
Also, adding another layer means you should evaluate:
latency
provider availability
data/privacy requirements
supported API features
model-specific behavior
operational dependencies
OpenRouter also provides controls around provider selection and data collection, including options such as Zero Data Retention routing where supported, so these requirements should be evaluated rather than assumed. (OpenRouter)
My Take as a Senior Developer
I wouldn’t look at OpenRouter simply as “a website where I can access different AI models.”
The more interesting way to think about it is:
OpenRouter is an abstraction layer between your application and the rapidly changing LLM ecosystem.
The AI world is moving extremely fast.
Today’s best model may not be tomorrow’s best model.
If your application is tightly coupled to:
Application → Provider SDK → One Model
you have created an architectural dependency.
If instead you build:
Application
     ↓
AI Service / Adapter
     ↓
OpenRouter
     ↓
Multiple Models / Providers
you gain considerably more flexibility.
For me, model experimentation, provider independence, automatic fallback and a consistent API are the strongest reasons to consider OpenRouter.
And for someone learning AI development, it is also a practical way to experiment with different models without writing a completely different integration for every provider.
Bottom line: If you’re building AI features today, don’t think only about which model to use. Think about how easily you can change that model tomorrow. OpenRouter is one practical way to design for that flexibility.
Conceptually, that becomes a pgvector nearest-neighbor query using cosine distance. pgvector supports cosine distance through <=>.
3. Test semantic search
You already have three chunks:
Chunk 1
Ruby blocks are chunks of code passed to methods.
Chunk 2
Ruby modules allow code to be organized and reused.
Chunk 3
Ruby classes define objects and their behavior.
Let’s test with a query that doesn’t use the exact wording from the second chunk.
Run:
bin/rails c
Then:
search=Ai::VectorSearchService.new
Now:
results=search.call(
query:"How can I reuse code in Ruby?"
)
Inspect:
results.map(&:content)
You should ideally see the modules chunk near the top:
"Ruby modules allow code to be organized and reused."
That’s our first semantic retrieval.
4. See the ranking
I want you to see why the result was selected.
Ask for the distance:
results.map do |chunk|
  {
    id: chunk.id,
    content: chunk.content,
    distance: chunk.neighbor_distance
  }
end
Depending on your Neighbor version, the distance accessor may be exposed differently. If neighbor_distance isn’t available, don’t spend time debugging it yet; the returned ordering is the important part for this checkpoint.
A basic test can use a fake embedding service, because we don’t want every test to call the embedding API.
require "test_helper"

class Ai::VectorSearchServiceTest < ActiveSupport::TestCase
  test "returns nearest document chunks" do
    document = Document.create!(title: "Ruby Guide", source: "test")

    document.document_chunks.create!(
      content: "Ruby blocks are passed to methods.",
      chunk_index: 0,
      embedding: Array.new(1024, 0.1)
    )

    document.document_chunks.create!(
      content: "Ruby modules allow code reuse.",
      chunk_index: 1,
      embedding: Array.new(1024, 0.2)
    )

    fake_embedding_service = Minitest::Mock.new

    fake_embedding_service.expect(
      :call,
      Array.new(1024, 0.2),
      text: "How do I reuse Ruby code?"
    )

    service = Ai::VectorSearchService.new(
      embedding_service: fake_embedding_service
    )

    results = service.call(
      query: "How do I reuse Ruby code?",
      limit: 1
    )

    assert_equal 1, results.size
    assert_equal "Ruby modules allow code reuse.", results.first.content

    fake_embedding_service.verify
  end
end
Because our vectors are artificial, this test is mainly verifying the service’s wiring. For higher-confidence semantic-search tests, we’d later use controlled fixtures or a small integration test.
Next – The Actual RAG Answer
We’re now one step away from having a real RAG feature.
Currently:
Question
 ↓
VectorSearchService
 ↓
Relevant chunks
Next we’ll do:
Question
 ↓
VectorSearchService
 ↓
Top 5 chunks
 ↓
PromptBuilder
 ↓
LLM
 ↓
Answer grounded in document
We’ll modify Ai::PromptBuilder so it can accept retrieved context and implement:
Ai::RagService
That will be the point where our Rails app goes from “I can search vectors” to “I have built a RAG application.”
Step 14 – Complete RAG in Rails
Now we have reached the final step of the RAG implementation:
class Ai::PromptBuilder
  SYSTEM_PROMPT = <<~PROMPT
    You are a helpful AI assistant.

    Answer questions clearly and concisely.

    When document context is provided:
    - Use the provided context as the primary source of truth.
    - Do not invent information that is not supported by the context.
    - If the answer cannot be determined from the context, say that you don't have enough information.
  PROMPT

  def initialize(conversation:, context: nil)
    @conversation = conversation
    @context = context
  end

  def build
    messages = [
      {
        role: "system",
        content: SYSTEM_PROMPT.strip
      }
    ]

    if @context.present?
      messages << {
        role: "system",
        content: <<~CONTEXT
          Use the following document context to answer the user's question:

          #{@context}
        CONTEXT
      }
    end

    messages.concat(
      @conversation.messages
        .order(:created_at)
        .map do |message|
          {
            role: message.role,
            content: message.content
          }
        end
    )

    messages
  end
end
result = rag.call(
  conversation: conversation,
  question: "How can Ruby code be reused?"
)
Then:
putsresult[:content]
You should get an answer based on your stored document chunks.
Error: I didn’t see a question in your message, This model is unavailable for free
When I tested result = rag.call(... I get this error:
Error #2

{url: "https://openrouter.ai/api/v1/chat/completions", status: 404, body: {error: {message: "This model is unavailable for free. The paid version is available now - use this slug instead: minimax/minimax-m3", code: 404}, user_id: "user_xxxxx"}} (OpenAI::Errors::NotFoundError)
Our model fallback does not work. So I used another one as our first model from the models array: "nvidia/nemotron-3-super-120b-a12b:free", Then it works. But I get the following result:
Error #1

puts result
{content: "I'm ready to answer your question, but I didn’t see a question in your message. Could you please provide the question you’d like me to answer based on the given context about Ruby modules, blocks, and classes?", model: "nvidia/nemotron-3-super-120b-a12b:free", input_tokens: 139, output_tokens: 151}
Why is it?
There are actually two separate issues here. The first one is very clear from our RagService result.
1. Why the RAG answer says “I didn’t see a question”
Your code currently does this:
result=rag.call(
conversation:conversation,
question:"How can Ruby code be reused?"
)
But in our Ai::RagService, we only use question for retrieval:
chunks=@vector_search_service.call(
query:question,
limit:limit
)
Then we build the prompt from:
Ai::PromptBuilder.new(
conversation:conversation,
context:context
).build
The question itself is never added to the conversation or prompt.
So the LLM receives approximately:
SYSTEM:
You are a helpful AI assistant...

CONTEXT:
Ruby blocks are...
Ruby modules allow code to be organized and reused.
Ruby classes define...

[previous conversation, if any]
but not:
USER:
How can Ruby code be reused?
Therefore the model is actually doing the right thing when it says:
“I didn’t see a question in your message.”
This is our bug.
2. Fix Ai::RagService
We need to make the current question part of the LLM input.
I actually prefer making the question a first-class argument to PromptBuilder rather than appending it afterward.
So our cleaner final API can become:
Ai::PromptBuilder.new(
conversation:conversation,
context:context,
current_question:question
).build
Then PromptBuilder controls the complete LLM prompt.
We’ll do that after confirming the current fix works.
4. About your fallback problem
You’re also correct that the fallback behavior isn’t happening as expected.
Your error:
This model is unavailable for free.
The paid version is available now...
came back as:
OpenAI::Errors::NotFoundError
That’s HTTP 404.
OpenRouter’s current documentation says its models array should trigger fallback when the primary model returns an error, and when using the OpenAI SDK it should be supplied through extra_body. (OpenRouter)
However, there’s an important detail in our current Ruby SDK usage.
The latest OpenAI Ruby SDK documentation says undocumented request parameters such as OpenRouter’s models extension should be passed using:
request_options: {
extra_body: {
models: [...]
}
}
not simply:
extra_body: {
models: [...]
}
The SDK documents extra_body specifically under request_options. (GitHub)
So our earlier code was likely passing the OpenRouter extension in the wrong place.
5. Fix Ai::Client fallback request
Change this:
response=@client.chat.completions.create(
model:MODELS.first,
messages:messages,
extra_body: {
models:MODELS.drop(1)
}
)
to:
response=@client.chat.completions.create(
model:MODELS.first,
messages:messages,
request_options: {
extra_body: {
models:MODELS.drop(1)
}
}
)
That’s the key fix.
The OpenAI Ruby SDK explicitly documents request_options.extra_body for passing provider-specific/undocumented request parameters.
6. Test the fallback independently
Before retesting RAG, let’s isolate fallback.
Temporarily make:
MODELS= [
"an-invalid-or-unavailable-model",
"nvidia/nemotron-3-super-120b-a12b:free"
].freeze
Then:
client = Ai::Client.new

result = client.chat(
  messages: [
    {
      role: "user",
      content: "Why is Node.js commonly used as a backend?"
    }
  ]
)
Then:
putsresult[:content]
putsresult[:model]
We want:
requested primary → fails
fallback → succeeds
result[:model]
=> "nvidia/nemotron-3-super-120b-a12b:free"
If that works, restore your real MODELS.
This is a much better test than testing fallback through the full RAG stack.
* Now Let’s Move On to Our Development.
14.4 See the actual retrieved context
Before trusting the final answer, inspect retrieval independently:
search = Ai::VectorSearchService.new

chunks = search.call(
  query: "How can Ruby code be reused?",
  limit: 3
)
Then:
chunks.eachdo |chunk|
puts"-----"
putschunk.content
end
You should see something like:
-----
Ruby modules allow code to be organized and reused.
-----
Ruby classes define objects and their behavior.
That’s the crucial RAG mechanism.
The model didn’t search PostgreSQL.
Rails searched PostgreSQL first and gave the model the relevant information.
14.5 Connect RAG to the chat flow
Right now our application uses:
Ai::ChatService
for normal chat.
We can keep that and add a dedicated RAG path.
For example, create an endpoint/action later such as:
             DOCUMENT INGESTION

PDF / Document
      ↓
Text Extraction
      ↓
Chunking
      ↓
EmbeddingService
      ↓
Embedding Model
      ↓
vector(1024)
      ↓
DocumentChunk
      ↓
PostgreSQL + pgvector
14.12 The answer you should memorize
Question:
“Explain how you implemented RAG in Rails.”
You can now say:
“I split documents into chunks and generated embeddings for each chunk. I stored those embeddings in PostgreSQL using pgvector. At query time, I embed the user’s question and perform cosine similarity search to retrieve the most relevant chunks. I then inject those chunks as context into the prompt and send the augmented prompt to the LLM. I keep retrieval, prompt construction and provider communication behind separate Rails services.”
That’s already enough material for a serious Senior Rails + AI int. discussion.
Now, we’ll consider RAG mechanically complete and move to the next major bootcamp topic: AI Agents + Tool Calling, where we’ll turn the assistant from:
Question → Answer
into:
Question
↓
Agent
├── Search docs
├── Search products
├── Find order
└── Execute business action
That is where your Rails business-logic and API design experience becomes especially valuable.
One important correction before we code: the free model list you fetched earlier contains no free embedding model slug. OpenRouter currently lists liquid/lfm2.5-embedding-350m as a free embedding model, producing 1,024-dimensional vectors. OpenRouter’s embeddings API is OpenAI-compatible, so we can use the same Ruby SDK/base URL. (OpenRouter)
That means our existing vector(1536) column is the wrong dimension for the free embedding model we’ll use. We’ll fix that now.
def embed(text:)
response = @client.embeddings.create(
model: EMBEDDING_MODEL,
input: text
)
{
embedding: response.data.first.embedding,
model: response.model,
input_tokens: response.usage&.prompt_tokens
}
end
So your client now has two responsibilities:
chat()
embed()
Both communicate with the same OpenRouter endpoint, but use different models/endpoints. OpenRouter provides an OpenAI-compatible /embeddings API for this. (OpenRouter)
Step 4 – Test the raw embedding request
Open Rails console:
bin/rails c
Then:
client=Ai::Client.new
Now:
result = client.embed(
text: "Ruby on Rails is a web application framework."
)
Inspect:
result.keys
You should get:
[:embedding, :model, :input_tokens]
Now:
result[:embedding].length
You should get:
1024
This is an important RAG checkpoint.
You’ve just proven:
text
↓
embedding model
↓
1024 numbers
Now inspect the first few values:
result[:embedding].first(5)
You’ll see floating-point numbers.
Don’t worry about the actual values. Their position in vector space is what matters.
Step 5 – Create Ai::EmbeddingService
Now we introduce the application-level service.
Create:
app/services/ai/embedding_service.rb
Use:
class Ai::EmbeddingService
def initialize(ai_client: Ai::Client.new)
@ai_client = ai_client
end
def call(text:)
result = @ai_client.embed(text: text)
result[:embedding]
end
end
Why create another service when Ai::Client already has embed?
Because these are different responsibilities:
Ai::Client
How do I communicate with OpenRouter?
Ai::EmbeddingService
How does our application generate an embedding?
That distinction becomes useful once we introduce:
We now have our first actual vector stored in PostgreSQL.
Error: I cannot update embedding vector column with Ruby Array embedding data
I have tested to storing the embedding. But it seems to be Rails does not know / there is a Type mismatch for embedding ruby array data and db vector data type
Question
↓
Query embedding
↓
pgvector
↓
ORDER BY cosine distance
↓
Top K chunks
That is the point where RAG becomes real.
Then we’ll build Ai::VectorSearchService and make the first semantic search against PostgreSQL – the most important practical RAG step after embeddings.