We should implement OpenRouter model fallbacks. I have received an email that is pointing to exactly the right mechanism.
The important distinction is:
model = primary model
models = ordered fallback models
OpenRouter tries the models in order when the current one errors
With the OpenAI Ruby SDK, OpenRouter’s models extension should be passed through extra_body. (OpenRouter)
Also, our previous openai/gpt-oss-20b:free error is precisely the kind of failure where a fallback chain is useful.
1. Don’t use openrouter/free
Let’s make the model selection explicit.
In Ai::Client:
PRIMARY_MODEL="openai/gpt-oss-20b:free"
FALLBACK_MODELS= [
"some-other-free-model:free",
"another-free-model:free"
].freeze
However, don’t blindly copy model names from an old tutorial, because OpenRouter’s free catalog changes. Its current model listing shows multiple free models and their availability/status. (OpenRouter)
For this reason, let’s first see what free models are currently available to your account/API.
This gives us the currently available zero-price model IDs instead of guessing.
Pick 2–3 general-purpose conversational models.
Avoid things whose purpose is:
moderation
safety classification
reranking
embedding
image generation
Our earlier User Safety: safe response is exactly why.
3. Model fallback implementation
I would not use openrouter/free as our primary model anymore and definitely not nvidia/nemotron-3.5-content-safety, which is why you previously got the safety-classification output.
For our AI Assistant app, let’s use three general-purpose free models and let OpenRouter handle model-level fallback. OpenRouter documents that the models array is tried in order and with the OpenAI SDK it belongs inside extra_body. (OpenRouter)
Our free fallback chain
From the models we actually have available, I’d use:
The reason I’m choosing these is that they’re general instruction/chat models rather than specialized safety, embedding, or multimodal models. We are optimizing for learning reliability, not benchmarking model quality.
I would not use:
nvidia/nemotron-3.5-content-safety:free
because that’s the wrong task.
I would also avoid for this particular chat application:
cohere/north-mini-code:free
because we’re building a general assistant rather than a coding-only assistant.
And we won’t use:
openrouter/free
Change Ai::Client
Let’s simplify the configuration.
class Ai::Client
MODELS = [
  "minimax/minimax-m3:free",
  "google/gemma-4-31b-it:free",
  "nvidia/nemotron-3-super-120b-a12b:free"
].freeze
BASE_URL = "https://openrouter.ai/api/v1"
def initialize
api_key = Rails.application.credentials.dig(
:openrouter,
:api_key
)
raise "OpenRouter API key is missing" if api_key.blank?
@client = OpenAI::Client.new(
api_key: api_key,
base_url: BASE_URL
)
end
def chat(messages:)
response = @client.chat.completions.create(
model: MODELS.first,
extra_body: {
models: MODELS.drop(1)
},
messages: messages
)
{
content: response.choices.first.message.content,
model: response.model,
input_tokens: response.usage&.prompt_tokens,
output_tokens: response.usage&.completion_tokens
}
rescue OpenAI::Errors::RateLimitError => e
raise Ai::RateLimitError, e.message
rescue OpenAI::Errors::APITimeoutError => e
raise Ai::TimeoutError, e.message
rescue OpenAI::Errors::APIConnectionError => e
raise Ai::ProviderError, e.message
rescue OpenAI::Errors::APIStatusError => e
raise Ai::ProviderError, e.message
end
end
OpenRouter then tries the models in order if the preceding model can’t serve the request. (OpenRouter)
Why model plus models?
This is worth understanding:
model:MODELS.first
is the primary model.
extra_body: {
models:MODELS.drop(1)
}
are the fallbacks.
So:
M3
↓ unavailable
Gemma
↓ unavailable
Nemotron
If the request succeeds using Gemma, response.model tells us which model actually served the request. OpenRouter documents that the response’s model identifies the model used for the successful run. (OpenRouter)
Test it now
Start:
bin/rails c
Then:
client=Ai::Client.new
And:
result=client.chat(
messages: [
{
role:"user",
content:"Why Node.js as a backend?"
}
]
)
=>
{content:
"# Why Node.js as a Backend?\n\nNode.js has become one of the most popular choices for backend development for several compelling reasons:\n\n## 1. **JavaScript Everywhere**\n- Use the same language (JavaScript) on both frontend and backend\n- Easier to share code between client and server\n- Single language for full-stack development reduces context switching\n\n## 2. **Non-Blocking, Event-Driven Architecture**\n- Built on Google's V8 JavaScript engine\n- Handles thousands of concurrent connections with a single thread\n- Ideal for:...skipping...
=>
> puts result[:model]
minimax/minimax-m3:free
=> nil
Then:
putsresult[:content]
putsresult[:model]
You should now get an actual conversational answer.
Run it several times if you want to observe which model is serving your requests.
And this connects directly to our AiRequest
This is why we built the observability table earlier.
Imagine:
Requested:
minimax/m3
Actual:
google/gemma-4-31b-it
Our admin dashboard should eventually show:
Requested Model minimax/minimax-m3:free
Actual Model google/gemma-4-31b-it:free
Status success
That’s a genuinely useful production metric.
OpenRouter documents that, when using the OpenAI SDK, its models parameter is passed through extra_body. (OpenRouter)
OpenRouter says fallback can happen for provider downtime, rate limiting, moderation refusal and context-length errors, among other errors. (OpenRouter)
4. One thing we should NOT do
Don’t implement this:
begin
call_model_a
rescue
call_model_b
rescue
call_model_c
end
unless you have a very specific reason.
OpenRouter already provides model-level failover and doing the fallback manually would mean:
Your Rails app
      ↓
request A
      ↓
failure
      ↓
request B
while OpenRouter can perform this routing itself.
The provider also knows its own availability and provider-level routing state better than our Rails application does.
So:
Let OpenRouter handle model fallback; let Rails handle application-level error handling.
That’s a clean separation of responsibilities. (OpenRouter)
We have enough practical experience with SSE right now. We don’t need to perfect the transport layer, lets move on to improve our production error handling architecture.
Step 12 – Production Hardening of the AI Integration
class Ai::Error < StandardError
end

class Ai::ProviderError < Ai::Error
end

class Ai::RateLimitError < Ai::Error
end

class Ai::TimeoutError < Ai::Error
end
This gives our application its own error vocabulary instead of exposing SDK/provider exceptions everywhere.
The exact exception classes can depend on the SDK/version, so inspect the exception raised by your installed openai gem rather than blindly copying provider-specific classes.
“I distinguish transient failures from permanent failures. For transient failures, I use a bounded number of retries with exponential (delay: 1,2,4,8,16 seconds) backoff.”
Step 13: Add AI Observability with admin Dashboard
Instead of merely saying we support observability, let’s build an actual AI Admin / Observability dashboard into the app. This will make the project much stronger because you can demonstrate that we thought beyond “call the LLM.”
We will track:
AI Request
├── provider
├── model
├── operation
├── status
├── conversation
├── message
├── input tokens
├── output tokens
├── estimated cost
├── latency
├── started/completed timestamps
├── retry count
├── HTTP status
├── error class
├── error message
├── request ID
├── streamed?
└── metadata
And the admin UI will have:
/admin/ai_requests

AI Observability
-------------------------------------------------
Total Requests       127
Successful           119
Failed                 8
Total Input Tokens  45,230
Total Output Tokens 18,921
Avg Latency          2.34 sec
Estimated Cost       $0.00 / N/A
-------------------------------------------------

Recent AI Requests
-------------------------------------------------
Time | Model | Status | Tokens | Latency | Error
-------------------------------------------------
...
Then clicking a request gives the complete details.
Step 12A – Create AiRequest
We’ll call the model AiRequest.
This is not the AI message itself.
Remember:
Message
    ↓
What the user/assistant said

AiRequest
    ↓
What happened while talking to the LLM
namespace :admin do
  resources :ai_requests, only: %i[index show]
end
So your routes become something like:
Rails.application.routes.draw do
  resources :conversations, only: [:create, :show] do
    resources :messages, only: [:create]
  end

  namespace :admin do
    resources :ai_requests, only: %i[index show]
  end

  root "conversations#new"
end
Check:
bin/rails routes | grep ai_requests
You should get:
/admin/ai_requests
/admin/ai_requests/:id
Step 12I – Admin Controller
Open:
app/controllers/admin/ai_requests_controller.rb
Use:
class Admin::AiRequestsController < ApplicationController
  before_action :authenticate_admin!

  def index
    @ai_requests = AiRequest
      .includes(:conversation, :message)
      .recent
      .limit(100)

    @total_requests = AiRequest.count

    @successful_requests =
      AiRequest.successful.count

    @failed_requests =
      AiRequest.failed_requests.count

    @total_input_tokens =
      AiRequest.sum(:input_tokens)

    @total_output_tokens =
      AiRequest.sum(:output_tokens)

    @average_latency =
      AiRequest.where.not(latency_ms: nil).average(:latency_ms)

    @estimated_cost =
      AiRequest.sum(:estimated_cost)
  end

  def show
    @ai_request = AiRequest.includes(
      :conversation,
      :message
    ).find(params[:id])
  end

  private

  def authenticate_admin!
    authenticate_or_request_with_http_basic("AI Admin") do |username, password|
      username == Rails.application.credentials.dig(:admin, :username) &&
        password == Rails.application.credentials.dig(:admin, :password)
    end
  end
end
This means the admin dashboard isn’t publicly accessible.
here only to demonstrate recording unexpected failures.
In the final production version, we’ll distinguish:
timeout
rate limit
provider error
invalid response
unexpected application bug
and map them to the proper AiRequest.status.
That’s coming immediately after this.
Why this dashboard is worth having
You now have a tangible answer to questions like:
How would you monitor an AI application?
You can say:
“I record each AI invocation separately from the conversation message itself. I track provider, model, status, latency, token consumption, retries, HTTP status and error information, then expose that through an internal observability dashboard.”
Then show page:
/admin/ai_requests
That’s much stronger than saying:
“I would use logging.”
One thing I deliberately did NOT add
I don’t recommend storing the complete prompt by default in AiRequest.
Why?
Because prompts can contain:
PII
customer data
confidential company information
secrets
Instead we can later store safe metadata such as:
{
"message_count":8,
"prompt_tokens":1200,
"temperature":0.2
}
and keep sensitive content under the normal conversation access controls.
Issue 1:Fix AI Response: User Safety
Currently when I tested I get the AI Response like: User Safety: safeResponse Safety: safe
This is a model-selection problem, not a Rails problem.
The response:
User Safety: safeResponse Safety: safe
is characteristic of a content-safety/guardrail model, not a normal conversational model. OpenRouter currently lists Nemotron 3.5 Content Safety (free) as a moderation model whose intended output is exactly safety classifications such as User Safety and Response Safety. (OpenRouter)
Because we’re using:
MODEL="openrouter/free"
OpenRouter is free to route that request to an available free model. The free-model router is explicitly designed to select among available free models, so you shouldn’t use it when you need a stable application behavior. (OpenRouter)
Fix: choose an actual chat model
For our course, let’s use a specific free conversational model instead of:
MODEL="openrouter/free"
A good current option is:
MODEL="openai/gpt-oss-20b:free"
OpenRouter lists free models separately, including general-purpose models; the exact free catalog changes over time.
Change Ai::Client
Open:
app/services/ai/client.rb
Change:
MODEL="openrouter/free"
to:
MODEL="openai/gpt-oss-20b:free"
Then test:
bin/rails c
client=Ai::Client.new
result=client.chat(
messages: [
{
role:"user",
content:"Why Node.js as a backend?"
}
]
)
putsresult[:content]
We should now get an actual explanatory answer rather than the safety classification.
Why I want a specific model for our project
This is actually a valuable AI engineering lesson.
Current approach
Ai::Client
↓
openrouter/free
↓
??? model
The model can change depending on routing.
Better application architecture
Ai::Client
↓
specific model
↓
predictable behavior
For production systems, model choice should generally be deliberate rather than an accidental consequence of a router.
The openrouter/free router is useful for experimentation, but for our course we’ll use an explicit free model so our behavior stays understandable. OpenRouter itself recommends openrouter/free as a convenient way to sample available free models, which is precisely why it shouldn’t be treated as a fixed model identity.
One more thing: our RAG work needs an embedding model
Don’t use the chat model for embeddings.
We’ll have:
Chat:
openai/gpt-oss-20b:free
Embeddings:
separate embedding model
OpenRouter currently lists free embedding models as well, including NVIDIA’s Nemotron 3 Embed 1B, which is specifically intended for retrieval/RAG. (OpenRouter)
We’ll choose the embedding model separately when we implement Ai::EmbeddingService.
For now
Make this one-line change:
MODEL="openai/gpt-oss-20b:free"
After that, we’ll continue with Step 13 – generating embeddings and storing the first real vector in document_chunks.
Issue 2: OpenAI::Errors::NotFoundError
Our server Log:
OpenAI::Errors::NotFoundError ({url: "https://openrouter.ai/api/v1/chat/completions", status: 404, body: {error: {message: "This model is unavailable for free. The paid version is available now - use this slug instead: openai/gpt-oss-20b", code: 404}, user_id: ...
Since we’re using the openai Ruby SDK, our rescue layer should use OpenAI::Errors::*, not Faraday exceptions. The SDK maps HTTP status codes such as 400, 401, 403, 404, 409, 422, 429 and 500+ into its own typed exceptions, and it has separate APIConnectionError / APITimeoutError classes. (https://github.com/openai/openai-ruby/blob/main/lib/openai/errors.rb)
Also, our 404 message tells us something important:
OpenRouter’s current free catalog does include openai/gpt-oss-20b:free, but free endpoints can change availability. (OpenRouter)
Our earlier 404 specifically said that the endpoint was unavailable for free at that moment and suggested the paid slug. Since OpenRouter currently lists the :free variant as free, this looks like provider/availability inconsistency, not that our slug was fundamentally wrong. OpenRouter also notes that free variants are rate-limited and availability can vary. (OpenRouter)
1. Fix the model
Let’s use the explicit free model again:
MODEL="openai/gpt-oss-20b:free"
OpenRouter currently lists that exact slug as free with zero input/output pricing. (OpenRouter)
If that endpoint temporarily fails, we can switch to another currently listed free model rather than using openrouter/free.
2. Fix Ai::Client error handling
Also change our Ai::Client chat rescues from: Faraday::TooManyRequestsError
Faraday::TimeoutError
Faraday::Error
to: similar to: OpenAI::Errors::NotFoundError etc,

check: https://github.com/openai/openai-ruby/blob/main/lib/openai/errors.rb
Let’s use the actual SDK error hierarchy.
The important classes are:
OpenAI::Errors::BadRequestError
OpenAI::Errors::AuthenticationError
OpenAI::Errors::PermissionDeniedError
OpenAI::Errors::NotFoundError
OpenAI::Errors::ConflictError
OpenAI::Errors::UnprocessableEntityError
OpenAI::Errors::RateLimitError
OpenAI::Errors::InternalServerError
OpenAI::Errors::APIConnectionError
OpenAI::Errors::APITimeoutError
The current SDK maps HTTP 404 → NotFoundError, 429 → RateLimitError, and 500+ → InternalServerError. (GitHub)
So replace our old Faraday rescues entirely.
app/services/ai/client.rb
Use:
class Ai::Client
  MODEL = "openai/gpt-oss-20b:free"
  BASE_URL = "https://openrouter.ai/api/v1"

  def initialize
    api_key = Rails.application.credentials.dig(:openrouter, :api_key)

    raise "OpenRouter API key is missing" if api_key.blank?

    @client = OpenAI::Client.new(
      api_key: api_key,
      base_url: BASE_URL
    )
  end

  def chat(messages:)
    response = @client.chat.completions.create(
      model: MODEL,
      messages: messages
    )

    {
      content: response.choices.first.message.content,
      model: response.model,
      input_tokens: response.usage&.prompt_tokens,
      output_tokens: response.usage&.completion_tokens
    }
  rescue OpenAI::Errors::RateLimitError => e
    raise Ai::RateLimitError, e.message

  rescue OpenAI::Errors::APITimeoutError => e
    raise Ai::TimeoutError, e.message

  rescue OpenAI::Errors::APIConnectionError => e
    raise Ai::ProviderError, e.message

  rescue OpenAI::Errors::BadRequestError,
          OpenAI::Errors::AuthenticationError,
          OpenAI::Errors::PermissionDeniedError,
          OpenAI::Errors::NotFoundError,
          OpenAI::Errors::ConflictError,
          OpenAI::Errors::UnprocessableEntityError,
          OpenAI::Errors::InternalServerError,
          OpenAI::Errors::APIStatusError => e
    raise Ai::ProviderError, e.message
  end
end
The specific NotFoundError you just encountered will therefore be caught here:
This tells us what the client’s constructor expects.
Also try:
OpenAI::Client.instance_methods(false)
We’re learning to inspect a Ruby library rather than treating it as magic.
Step 5.14 – Create the OpenAI client
Now let’s modify:
app/services/ai/client.rb
We’ll start with:
class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?

    @client = OpenAI::Client.new(api_key: @api_key)
  end
end
The Ruby OpenAI SDK’s API can change between versions, so don’t blindly copy the exact request syntax from older tutorials. That’s why we’re checking the version we’ve actually installed before writing the API call.
Now we’ve:
“OpenAI client initialized.”
We’ll make our first actual LLM request and inspect the complete response, including:
response
model
output
usage
input tokens
output tokens
That will lead directly into why we added those fields to our Message model.
@client=OpenAI::Client.new(api_key:@api_key)
We’ll use our installed SDK’s API, not older ruby-openai examples. The current official openai Ruby SDK documents OpenAI::Client.new(api_key: ...) and the Responses API as the current interface. (GitHub)
Step 5.16 – Make the First Real LLM Request
For this step, we’ll do one simple request and inspect the response.
We are not integrating it with Conversation or Message yet.
Our goal is:
Rails console
↓
Ai::Client
↓
OpenAI Responses API
↓
LLM
↓
Response
1. Add a chat method
Open:
app/services/ai/client.rb
Change it to:
class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?

    @client = OpenAI::Client.new(api_key: @api_key)
  end

  def chat(message)
    @client.responses.create(
      model: "gpt-5.2",
      input: message
    )
  end
end
The SDK’s current Responses API accepts model and input for creating a response. (GitHub)
Why input: message?
We’re deliberately starting with the simplest possible request:
input:"Explain Ruby blocks in simple terms"
Later we’ll send structured conversation history:
input: [
{ role::system, content:"..." },
{ role::user, content:"..." }
]
The Responses API supports both simple input and structured message input. (GitHub)
2. Start Rails console
bin/rails c
Create the client:
client=Ai::Client.new
Now make the request:
response=client.chat(
message:"Explain Ruby blocks in simple terms."
)
This is the moment our application makes an actual network request.
3. Inspect the response
First:
response.class
Then:
response
Don’t worry if the output is large.
The current official Ruby SDK returns typed response objects and the response contains the generated output plus metadata such as usage. (GitHub)
But if you get the following output, we can change the model which has free API calls:
ai-assistant(dev):013> client = Ai::Client.new
ai-assistant(dev):003> res = ai.chat('I want to be a expert in Ruby language')
app/services/ai/client.rb:11:in 'Ai::Client#chat': {url: "https://api.openai.com/v1/responses", status: 429, body: {error: {message: "You have no credits remaining. Add credits to continue using the API at https://platform.openai.com/settings/organization/billing/.", type: "insufficient_quota", param: nil, code: "credit_balance_exhausted"}}} (OpenAI::Errors::RateLimitError)
        from (ai-assistant):3:in '<compiled>'
Yes – the error makes sense and there is an important distinction here:
Our ChatGPT subscription and OpenAI API billing are separate.
So even if you can use ChatGPT normally, that does not give your Ruby application free API calls. OpenAI explicitly says ChatGPT and API billing are managed separately. (OpenAI Help Center)
Why you’re seeing You have no credits remaining
Your Rails code is calling the OpenAI API, not ChatGPT:
Rails app
↓
OpenAI API
↓
API billing / credits
The API account associated with your key currently has no usable credits. OpenAI’s current prepaid-billing documentation says API requests stop once the available credit balance is exhausted. (OpenAI Help Center)
“But aren’t basic models free?”
Not generally for the API.
There may be specific free/trial allocations or products with included usage, but you should not assume that a model being available in ChatGPT means the API is free.
For our Rails application, we’re using:
OpenAI::Client
which consumes API usage and is metered separately.
What I recommend for our course
I don’t think we should spend money just to continue learning unless you’re comfortable doing so.
We have three practical paths:
Option 1 – Add a small API balance
Open your OpenAI API billing overview and check your balance. New API users currently use prepaid billing and the documented minimum purchase is $5, with $10 as the default purchase amount. (OpenAI Help Center)
For this course a small balance should be plenty for experimentation because our prompts will be tiny.
Option 2 – Use another provider with a free tier
We could temporarily use a provider that offers some free API usage, while keeping the same architecture:
Ai::Client
↓
Provider
↓
LLM
This is actually useful because later we’ll make our architecture provider-agnostic.
Option 3 – Run a local model
We can install something like Ollama and run an LLM locally:
Rails
↓
Ai::Client
↓
localhost
↓
Local LLM
Advantages:
no API credits
no network dependency
no per-token cost
great for development
The downside is that the model quality may differ from hosted models, and local inference requires reasonable hardware.
One important thing for our architecture
Don’t change this:
Ai::Client
The fact that OpenAI isn’t currently usable doesn’t mean we should redesign the application.
We specifically created:
Rails
↓
Ai::Client
↓
Provider
so that later we can switch:
Ai::Client
↓
OpenAI
to:
Ai::Client
↓
Anthropic
or:
Ai::Client
↓
Ollama
without rewriting our Rails application.
That’s actually an important senior-level design lesson.
What we can do now?
Since our objective is learning AI engineering, not spending money on API calls, first check your API billing page.
If it shows:
Free trial credit remaining: $0.00
then the error is fully explained. OpenAI’s billing documentation uses exactly this sort of balance indicator. (OpenAI Help Center)
We can then decide between a small API credit or a local/free-tier provider.
For this course, I slightly prefer keeping OpenAI as the first provider so you learn the real production API flow, then later we’ll add a second provider/local model to demonstrate the abstraction properly.
4. Get the generated text
Try:
response.output_text
You should get a normal answer such as:
A Ruby block is a chunk of code that can be passed to a method...
This is the first important distinction:
response
↓
entire API response
response.output_text
↓
just the model's text
Don’t immediately throw away the full response. We need the metadata later.
5. Inspect the model
Try:
response.model
This tells you which model actually generated the response.
That’s relevant to our messages.model column.
6. Inspect usage
Now:
response.usage
You should see token-related information.
Inspect it:
response.usage.input_tokens
and:
response.usage.output_tokens
These are directly related to the fields we added earlier:
messages
-------------------
input_tokens
output_tokens
So our database design is now connected to a real API response.
LLM response
│
├── model
├── output text
└── usage
├── input_tokens
└── output_tokens
The SDK’s response models expose usage information as part of the response. (GitHub)
7. One very important experiment
Ask a second question:
response2=client.chat(
message:"What is my name?"
)
You’ll probably notice the model doesn’t know your name from the previous request.
That’s intentional.
We made two independent requests:
Request 1
"Explain Ruby blocks"
Request 2
"What is my name?"
The LLM does not automatically receive our previous request.
This is going to become extremely important when we implement:
Conversation
↓
Messages
↓
Prompt Builder
↓
LLM
Our Rails application will be responsible for providing the appropriate conversation context.
Don’t paste our API key or any sensitive output anywhere.
Now: “Our First LLM request works.”
Then we’ll do the next important step: inspect the raw response structure and improve Ai::Client so it returns a clean Ruby object to the rest of our Rails application.
Now let’s move to the next step: make the Message model production-friendly.
We’ll start with the most important field: role.
Step 3 – Design Message.role
Currently our database allows:
role = anything
For example:
"user"
"assistant"
"system"
"foo"
"hello"
"something-invalid"
That’s not what we want.
Our AI application has a defined set of roles:
user
assistant
system
Later, when we introduce tool calling, we may also need to represent tool messages depending on the provider/API design. But for our current application, we’ll keep the persisted roles to these three.
Why use a string instead of an integer?
You may remember our previous discussion about Rails enums.
We could store:
0 = user
1 = assistant
2 = system
But for an AI application, I prefer a string-backed enum.
Database:
role
---------
user
assistant
system
instead of:
role
---------
0
1
2
Why?
1. Database is self-describing
When you run:
SELECTroleFROM messages;
you immediately see:
user
assistant
assistant
user
system
2. Easier debugging
When you’re debugging an AI conversation, the actual value is obvious.
3. Safer for external APIs
LLM APIs already use strings such as:
{
"role":"user"
}
So our database representation matches the domain.
Step 3A – Add the Rails enum
Open:
app/models/message.rb
Currently you should have something like:
classMessage<ApplicationRecord
belongs_to:conversation
end
Change it to:
classMessage<ApplicationRecord
belongs_to:conversation
enum:role, {
user:"user",
assistant:"assistant",
system:"system"
}, validate:true
end
Understand this carefully
This:
enum:role, {
user:"user",
assistant:"assistant",
system:"system"
}, validate:true
doesn’t mean PostgreSQL has an enum type. We’re using a Rails enum backed by a string column.
PostgreSQL still has:
role character varying
Rails gives us a domain API on top of it.
Step 3B – Test the enum
Start Rails console:
bin/rails console
Find our message:
message=Message.first
Check:
message.role
You should get:
"user"
Now:
message.user?
Expected:
true
And:
message.assistant?
Expected:
false
Step 3C – Test the scopes
Rails also gives us useful scopes.
Try:
Message.user
and:
Message.assistant
and:
Message.system
For example:
Message.user
roughly translates to:
SELECT*
FROM messages
WHERErole='user';
This is one of the benefits of using an enum.
Step 3D – Test invalid values
Now try:
Message.new(
conversation:Conversation.first,
role:"something_else",
content:"test"
)
Because we specified:
validate:true
Rails should treat the role as invalid.
Check:
message=Message.new(
conversation:Conversation.first,
role:"something_else",
content:"test"
)
message.valid?
Expected:
false
Then:
message.errors.full_messages
You should see an error indicating that the role is not included in the allowed values.
Why validate: true?
This is worth understanding: Without validation, Rails enum behavior can raise an ArgumentError when assigning an invalid value.
With:
validate:true
we get normal ActiveRecord validation behavior:
message.valid?
→false
and:
message.errors
contains the validation error.
That’s generally more convenient when the model is receiving user/application input.
Step 3E – One more important layer: Database constraint
There is a subtle issue here.
Rails validation protects you when data enters through Rails.
But PostgreSQL doesn’t know that only these values are valid:
ERROR: new row for relation "messages" violates check constraint "messages_role_check"
That’s exactly what we want.
The database is now protecting the data.
Why is this important?
Suppose an int. asks:
“Why do you have both Rails validation and a PostgreSQL constraint?”
A strong senior-level answer would be:
“Rails validations provide application-level feedback and are useful for normal model operations, but they’re not a database integrity guarantee because data can enter through other paths. For important invariants such as message roles, I also enforce the constraint at the PostgreSQL level.”
That’s a much stronger answer than:
“Because Rails has validations.”
4.8 One more design question: content
We’re making:
change_column_null:messages, :content, false
But should an AI message be allowed to contain an empty string?
For example:
content:""
NOT NULL allows that.
So:
NULL NO
"" technically allowed
"Hello" YES
Whether empty content should be allowed is an application-level business rule.
We can later decide whether to add:
validates:content, presence:true
But don’t add that yet.
There are legitimate AI API situations where a message may not have ordinary text content – for example, tool-related or structured content. We’ll revisit our message representation when we implement tool calling.
We don’t want the application to fail mysteriously later.
Add:
class Ai::Client
  def initialize
    @api_key = Rails.application.credentials.dig(:openai, :api_key)

    raise "OpenAI API key is missing" if @api_key.blank?
  end
end
Now:
Ai::Client.new
will fail immediately if the key isn’t configured. This is called fail-fast configuration.
5.10 Test the client
Run:
bin/rails console
Then:
client=Ai::Client.new
If everything is configured correctly, it should return:
Enums are one of those features developers use frequently – especially in frameworks like Rails – but many developers never fully understand why enums exist, what problem they solve, or how they are implemented internally. In Rails, enums appear deceptively simple:
enumstatus: { pending:0, paid:1, failed:2 }
But behind this tiny line lies an important software design concept used across programming languages, databases, compilers, APIs, operating systems, and application architecture.
This article explains the complete picture of enums:
Why enums exist
How they differ from other data structures
How Rails maps enums to integers internally
Whether enums are tied to SQL/databases
How ActiveRecord::Enum works under the hood
Real-world benefits and tradeoffs developers should know
What Is an Enum?
An Enum (Enumeration) is a restricted set of named values representing a finite group of states or options.
Example:
status=:pending
Possible statuses may be:
:pending
:processing
:completed
:failed
Instead of allowing any arbitrary value, enums constrain the system to a known set of valid states.
Why Do Enums Exist?
Enums solve several important problems in software systems.
1. Prevent Invalid States
Without enums:
order.status="asdfgh"
This may accidentally enter the database and corrupt business logic.
Enums restrict allowed values:
enumstatus: {
pending:0,
processing:1,
completed:2
}
Now Rails only allows known states.
2. Improve Readability
Compare:
iforder.status==2
vs
iforder.completed?
Enums convert meaningless numbers into expressive business language.
3. Save Storage Space
Integers are smaller and faster than strings.
Instead of storing:
"processing"
the DB stores:
1
This improves:
indexing
query performance
storage efficiency
4. Standardize State Management
Enums centralize valid states:
Order.statuses
returns:
{
"pending"=>0,
"processing"=>1,
"completed"=>2
}
This becomes a single source of truth.
5. Enable Better APIs & DSLs
Rails automatically generates methods:
order.pending?
order.completed!
Order.processing
Enums create expressive domain APIs.
How Enums Differ From Other Data Structures
Enums are NOT collections like arrays or hashes.
They represent a finite state system.
🔹 Enum vs Array
Array:
statuses= ["pending", "paid", "failed"]
Problem:
no constraints
no semantic meaning
no mapping behavior
no helper methods
🔹 Enum vs Hash
Hash:
STATUSES= {
pending:0,
paid:1
}
Closer, but still missing:
validations
query scopes
state predicates
DSL methods
Rails enums internally use hashes, but add behavior around them.
🔹 Enum vs Constants
Constants:
PENDING=0
PAID=1
Problem:
scattered
harder to manage
no grouped state semantics
Enums organize states cohesively.
🌍 Are Enums Related Only to SQL or Databases?
❌ Absolutely not.
Enums exist in:
C
Java
Rust
Swift
TypeScript
GraphQL
Operating systems
Compilers
APIs
State machines
Enums are a general programming concept, not a database feature.
Example: TypeScript Enum
enumStatus{
Pending,
Processing,
Completed
}
Example: Java Enum
enumStatus{
PENDING,
PROCESSING,
COMPLETED
}
Example: PostgreSQL Native Enum
CREATE TYPE status AS ENUM (
'pending',
'processing',
'completed'
);
This is database-level enum support.
🏗️ How Rails Implements Enums
Rails provides:
ActiveRecord::Enum
located in:
activerecord/lib/active_record/enum.rb
When you write:
classOrder<ApplicationRecord
enumstatus: {
pending:0,
processing:1,
completed:2
}
end
Rails dynamically generates:
1️⃣ Attribute Mapping
order.status
# => "pending"
Internally stored as:
0
in the database.
2️⃣ Predicate Methods
order.pending?
order.completed?
3️⃣ Bang Methods
order.completed!
Equivalent to:
order.update!(status::completed)
4️⃣ Query Scopes
Order.pending
Order.completed
Generated automatically.
5️⃣ Mapping Helpers
Order.statuses
Returns:
{
"pending"=>0,
"processing"=>1,
"completed"=>2
}
How Rails Maps Enum Values to Integers
Internally Rails stores:
{
pending:0,
processing:1,
completed:2
}
When assigning:
order.status=:processing
Rails converts:
:processing->1
before writing to DB.
When reading:
1->"processing"
This conversion is handled through ActiveRecord attribute type casting.
Database Example
Ruby:
order.status
# => "completed"
Actual DB value:
status =2
Why Integers Are Commonly Used
Integers:
are compact
index efficiently
compare faster
are DB-friendly
This is why Rails originally used integer-backed enums.
Important Enum Pitfall: Order Matters
This is VERY important.
Dangerous
enumstatus: [:pending, :processing, :completed]
Rails maps automatically:
pending->0
processing->1
completed->2
If you later insert:
[:pending, :draft, :processing, :completed]
Everything shifts:
processing becomes 2
completed becomes 3
💥 Existing DB data breaks.
Correct (recommended)
Always use explicit mapping:
enumstatus: {
pending:0,
processing:1,
completed:2
}
String-Based Enums in Rails
Rails also supports string-backed enums:
enumstatus: {
pending:"pending",
completed:"completed"
}
Benefits:
human-readable DB values
safer migrations
easier debugging
Tradeoff:
slightly larger storage
slightly slower indexing
🧪 Real SQL Generated by Rails Enum Queries
Order.completed
Generates:
SELECT*
FROM orders
WHERE status =2;
Even though Ruby code uses names, SQL uses integers.
🔬 Internals: How ActiveRecord::Enum Works
Internally Rails:
stores mappings in a class hash
defines methods dynamically using metaprogramming
hooks into ActiveRecord attribute casting
builds scopes automatically
Rails essentially does something conceptually like:
Rails validates at app layer, but DB still accepts:
status =999
unless constrained.
🛡️ Best Practices for Rails Enums
Use explicit mappings
enumstatus: {
pending:0,
processing:1,
completed:2
}
Add DB constraints if critical
Example PostgreSQL constraint:
CHECK(status IN(0,1,2))
Keep enums focused
Good:
status
payment_state
visibility
Bad:
everything_state
Prefer string enums when readability matters
Especially in:
analytics-heavy apps
debugging-heavy systems
APIs
Consider state machines for complex transitions
Enums represent states. State machines represent transitions.
Very different concepts.
Mental Model Every Developer Should Remember
Think of enums as:
“A controlled vocabulary for state.”
Enums are:
not collections
not just DB mappings
not Rails-specific
They are a way to model finite, meaningful states safely and expressively.
Final Takeaway
Enums exist because software systems constantly need to represent a limited set of valid states in a way that is:
efficient
readable
maintainable
safe
Rails’ ActiveRecord::Enum builds a powerful abstraction on top of simple integer (or string) mappings, generating expressive APIs, query scopes, and validations automatically through Ruby metaprogramming.
Understanding enums deeply helps developers:
design better domain models
avoid fragile state systems
write safer queries
reason about application workflows more clearly
Enums may look small, but they are one of the foundational building blocks of robust application design.
When you run thousands of background jobs through Sidekiq, Redis becomes the bottleneck. Every job enqueue adds Redis writes, network round-trips, and memory pressure. This post covers a real-world optimization we applied and a broader toolkit for keeping Sidekiq lean.
The Problem: One Job Per Item
Imagine sending weekly emails to 10,000 users. The naive approach:
At 10,000 users, that’s 10,000 Redis operations and 10,000 scheduled entries. At 1M users, that’s 1M scheduled jobs in Redis. That’s expensive and slow.
The Fix: Batch + Staggered Scheduling
Instead of one job per user, we batch users and schedule each batch with a small delay:
Each worker still processes one user at a time internally, but we only enqueue one job per batch. Redis overhead drops by roughly 100x.
Why perform_in instead of chaining?
perform_in(delay, batch_ids) — all jobs are scheduled immediately with their future timestamps. Sidekiq moves them into the ready queue at the right time regardless of other queue traffic.
Chaining (each job enqueues the next) — the next batch only enters the queue after the current one finishes. If other jobs are busy, your email chain sits behind them and can be delayed significantly.
For time-sensitive jobs like “send at 8:46 AM local time,” upfront scheduling is the right choice.
Other Sidekiq Optimization Strategies
1. Bulk Enqueue (Sidekiq Pro/Enterprise)
Sidekiq::Client.push_bulk pushes many jobs in one Redis call:
# Single Redis call instead of N
Sidekiq::Client.push_bulk(
'class'=>WeeklyEmailWorker,
'args'=>user_ids.map { |id| [id] }
)
Useful when you don’t need per-job delays and want to minimize Redis round-trips.
2. Adjust Concurrency
Default is 10 threads per process. More threads = more concurrency but more memory:
# config/sidekiq.yml
:concurrency:25# Tune based on CPU/memory
Higher concurrency helps if jobs are I/O-bound (HTTP, DB, email). For CPU-bound jobs, lower concurrency is usually better.
3. Use Dedicated Queues
Separate heavy jobs from light ones:
# config/sidekiq.yml
:queues:
-[critical, 3]# 3x weight
-[default, 2]
-[low, 1]
Critical jobs get more CPU time. Low-priority jobs don’t block the rest.
In this comprehensive guide, we’ll explore four fundamental concepts in computer science and object-oriented programming: the Template Method pattern, Strategy patterns, parameterized types, and object relationships through aggregation and acquaintance. These concepts form the backbone of modern software design and appear across virtually every programming language.
1. Template Method Pattern: Defining the Skeleton of an Algorithm
What is Template Method?
The Template Method is a behavioral design pattern that defines the skeleton of an algorithm in a base class but lets subclasses override specific steps without changing the algorithm’s structure. Think of it as a recipe where the overall cooking process is fixed, but individual chefs can customize certain steps.
The Core Idea
Instead of having multiple classes each implement the complete algorithm, you create:
A base/parent class that outlines the overall process
Subclasses that override specific “hook” methods to customize behavior
This follows the “Hollywood Principle”: “Don’t call us, we’ll call you.” The parent class controls the flow and calls the methods that subclasses provide.
Ruby Example
Let’s create a beverage brewing system:
# Base class defining the template method
class BeverageMaker
  def brew
    gather_ingredients
    heat_water
    add_ingredients
    steep
    serve
  end

  def gather_ingredients
    puts "Gathering ingredients..."
  end

  def heat_water
    puts "Heating water to appropriate temperature..."
  end

  # These are hook methods that subclasses will override
  def add_ingredients
    raise NotImplementedError, "Subclasses must implement add_ingredients"
  end

  def steep
    raise NotImplementedError, "Subclasses must implement steep"
  end

  def serve
    puts "Pouring into a cup..."
  end
end

# Tea subclass
class TeaMaker < BeverageMaker
  def add_ingredients
    puts "Adding tea leaves to the infuser..."
  end

  def steep
    puts "Steeping for 3-5 minutes..."
  end
end

# Coffee subclass
class CoffeeMaker < BeverageMaker
  def add_ingredients
    puts "Adding ground coffee to the filter..."
  end

  def steep
    puts "Brewing for 4-6 minutes..."
  end

  def serve
    puts "Adding milk and sugar as desired, then pouring..."
  end
end

# Usage
puts "=== Making Tea ==="
tea = TeaMaker.new
tea.brew

puts "\n=== Making Coffee ==="
coffee = CoffeeMaker.new
coffee.brew
Output:
=== Making Tea ===
Gathering ingredients...
Heating water to appropriate temperature...
Adding tea leaves to the infuser...
Steeping for 3-5 minutes...
Pouring into a cup...

=== Making Coffee ===
Gathering ingredients...
Heating water to appropriate temperature...
Adding ground coffee to the filter...
Brewing for 4-6 minutes...
Adding milk and sugar as desired, then pouring...
Real-World Application: Data Processing
class DataProcessor
  def process(file_path)
    data = read_file(file_path)
    data = validate(data)
    data = transform(data)
    data = enrich(data)
    save_output(data)
  end

  def read_file(file_path)
    raise NotImplementedError
  end

  def validate(data)
    puts "Validating data..."
    data
  end

  def transform(data)
    raise NotImplementedError
  end

  def enrich(data)
    puts "Enriching data with metadata..."
    data
  end

  def save_output(data)
    raise NotImplementedError
  end
end

class CSVProcessor < DataProcessor
  def read_file(file_path)
    puts "Reading CSV file: #{file_path}"
    [["Name", "Age"], ["Alice", 30], ["Bob", 25]]
  end

  def transform(data)
    puts "Transforming CSV data to hash format..."
    data
  end

  def save_output(data)
    puts "Saving processed data to database..."
  end
end

class JSONProcessor < DataProcessor
  def read_file(file_path)
    puts "Reading JSON file: #{file_path}"
    {"users" => [{"name" => "Alice", "age" => 30}]}
  end

  def transform(data)
    puts "Transforming JSON data to standardized format..."
    data
  end

  def save_output(data)
    puts "Saving to API endpoint..."
  end
end
Benefits
Code Reuse: Common logic is written once in the parent class
Consistency: Ensures all subclasses follow the same algorithm structure
Flexibility: Subclasses can customize only what they need
Maintainability: Changes to the overall algorithm are made in one place
The Strategy pattern defines a family of algorithms, encapsulates each one, and makes them interchangeable. It lets the algorithm vary independently from clients that use it. Unlike Template Method, where variations happen through inheritance, Strategy uses composition to swap algorithms at runtime.
The Core Idea
You create:
A Strategy interface that defines the algorithm contract
Concrete strategy classes that implement different variants
A context class that uses a strategy object
This allows you to change the algorithm used without modifying the client code.
Ruby Example
Let’s create a payment processing system:
# Strategy interface (in Ruby, we use duck typing or modules)
module PaymentStrategy
  def pay(amount)
    raise NotImplementedError
  end
end

# Concrete strategies
class CreditCardPayment
  include PaymentStrategy

  def initialize(card_number, cvv)
    @card_number = card_number
    @cvv = cvv
  end

  def pay(amount)
    puts "Processing credit card payment of $#{amount}"
    puts "Card: #{@card_number[-4..-1]}"
    validate_cvv
    puts "Payment approved!"
  end

  private

  def validate_cvv
    puts "Validating CVV..."
  end
end

class PayPalPayment
  include PaymentStrategy

  def initialize(email)
    @email = email
  end

  def pay(amount)
    puts "Sending $#{amount} via PayPal to #{@email}"
    authenticate
    puts "PayPal payment processed!"
  end

  private

  def authenticate
    puts "Authenticating with PayPal..."
  end
end

class CryptocurrencyPayment
  include PaymentStrategy

  def initialize(wallet_address, crypto_type = "Bitcoin")
    @wallet_address = wallet_address
    @crypto_type = crypto_type
  end

  def pay(amount)
    puts "Sending #{amount} satoshis to wallet #{@wallet_address}"
    puts "Cryptocurrency: #{@crypto_type}"
    confirm_blockchain
    puts "Transaction confirmed on blockchain!"
  end

  private

  def confirm_blockchain
    puts "Confirming on blockchain..."
  end
end

# Context class
class ShoppingCart
  def initialize(payment_strategy)
    @payment_strategy = payment_strategy
    @total = 0
  end

  def add_item(price)
    @total += price
  end

  def checkout
    @payment_strategy.pay(@total)
  end

  # Strategy can be changed at runtime
  def change_payment_method(new_strategy)
    @payment_strategy = new_strategy
  end
end

# Usage
puts "=== Customer 1: Credit Card Payment ==="
cart1 = ShoppingCart.new(CreditCardPayment.new("4532-1234-5678-9010", "123"))
cart1.add_item(50)
cart1.add_item(30)
cart1.checkout

puts "\n=== Customer 2: PayPal Payment ==="
cart2 = ShoppingCart.new(PayPalPayment.new("user@example.com"))
cart2.add_item(100)
cart2.checkout

puts "\n=== Customer 3: Changes mind about payment ==="
cart3 = ShoppingCart.new(CreditCardPayment.new("5412-9876-5432-1098", "456"))
cart3.add_item(75)
puts "Initial strategy: Credit Card"
cart3.change_payment_method(CryptocurrencyPayment.new("1A1z7agoat4WYvtQy06YnYs73m7nEChoCM", "Bitcoin"))
puts "Changed strategy: Cryptocurrency"
cart3.checkout
Real-World Application: Sorting Algorithms
module SortStrategy
  def sort(array)
    raise NotImplementedError
  end
end

class BubbleSort
  include SortStrategy

  def sort(array)
    puts "Sorting using Bubble Sort..."
    n = array.length
    (0...n).each do |i|
      (0...n - i - 1).each do |j|
        array[j], array[j + 1] = array[j + 1], array[j] if array[j] > array[j + 1]
      end
    end
    array
  end
end

class QuickSort
  include SortStrategy

  def sort(array)
    puts "Sorting using Quick Sort..."
    return array if array.length <= 1
    pivot = array[0]
    left = array[1..-1].select { |x| x < pivot }
    right = array[1..-1].select { |x| x >= pivot }
    sort(left) + [pivot] + sort(right)
  end
end

class DataSorter
  def initialize(strategy)
    @strategy = strategy
  end

  def execute(data)
    @strategy.sort(data)
  end

  def change_strategy(strategy)
    @strategy = strategy
  end
end

# Usage
data = [64, 34, 25, 12, 22, 11, 90]
sorter = DataSorter.new(BubbleSort.new)
puts sorter.execute(data.dup).inspect

sorter.change_strategy(QuickSort.new)
puts sorter.execute(data.dup).inspect
Benefits
Runtime Flexibility: Algorithms can be selected at runtime
Code Isolation: Each algorithm is encapsulated in its own class
Easy to Extend: New strategies can be added without modifying existing code
Testability: Each strategy can be tested independently
Template Method vs. Strategy
Aspect
Template Method
Strategy
Mechanism
Inheritance
Composition
When to use
Related algorithms sharing common structure
Interchangeable algorithms
Implementation
Subclasses override methods
Different classes implement interface
Change timing
Compile-time (class selection)
Runtime (object swap)
3. Parameterized Types: Generic Programming
What are Parameterized Types?
Parameterized types (also called generics) allow you to write code that works with different data types while maintaining type safety. They enable you to create classes and functions that operate on various types specified as parameters.
C++ Templates
C++ uses templates to implement generics at compile-time:
#include <iostream>
#include <vector>

// Generic function template
template <typename T>
T max_value(T a, T b) {
    return (a > b) ? a : b;
}

// Generic class template
template <typename T>
class Stack {
private:
    std::vector<T> elements;

public:
    void push(T value) {
        elements.push_back(value);
    }

    T pop() {
        T value = elements.back();
        elements.pop_back();
        return value;
    }

    bool is_empty() const {
        return elements.empty();
    }
};

int main() {
    // Using template functions with different types
    std::cout << "Max of 5 and 10: " << max_value(5, 10) << std::endl;
    std::cout << "Max of 3.5 and 2.1: " << max_value(3.5, 2.1) << std::endl;

    // Using template classes
    Stack<int> intStack;
    intStack.push(10);
    intStack.push(20);
    std::cout << "Popped: " << intStack.pop() << std::endl;

    Stack<std::string> stringStack;
    stringStack.push("Hello");
    stringStack.push("World");
    std::cout << "Popped: " << stringStack.pop() << std::endl;

    return 0;
}
Key Features:
Compile-time code generation: Compiler generates specific code for each type used
Type safety: Type checking happens at compile time
Zero runtime overhead: Generic code is instantiated for each type
Template specialization: Can provide specific implementations for certain types
Ada Generics
Ada’s generics provide a similar mechanism but with a different syntax:
generic
    type Item_Type is private;
    Max_Length : Integer;
package Stacks is
    type Stack_Type is limited private;

    procedure Push(S : in out Stack_Type; Item : Item_Type);
    procedure Pop(S : in out Stack_Type; Item : out Item_Type);
    function Is_Empty(S : Stack_Type) return Boolean;

private
    type Item_Array is array (1..Max_Length) of Item_Type;
    type Stack_Type is record
        Items : Item_Array;
        Top : Integer := 0;
    end record;
end Stacks;
Usage:
with Stacks;
procedure Use_Integer_Stack is
package Int_Stacks is new Stacks(Item_Type => Integer, Max_Length => 100);
My_Stack : Int_Stacks.Stack_Type;
begin
Int_Stacks.Push(My_Stack, 42);
-- ...
end Use_Integer_Stack;
Ruby Generics (Runtime Polymorphism)
Ruby doesn’t have compile-time generics, but uses duck typing and metaprogramming:
# Ruby approach: Using blocks and duck typing
class Container
  def initialize
    @items = []
  end

  def add(item)
    @items << item
  end

  def process(&block)
    @items.each { |item| block.call(item) }
  end

  def map(&block)
    @items.map { |item| block.call(item) }
  end

  def select(&block)
    @items.select { |item| block.call(item) }
  end
end

# Using with different types
int_container = Container.new
int_container.add(1)
int_container.add(2)
int_container.add(3)

puts "Original integers:"
int_container.process { |x| puts x }

puts "\nDoubled integers:"
doubled = int_container.map { |x| x * 2 }
puts doubled.inspect

string_container = Container.new
string_container.add("Hello")
string_container.add("World")
string_container.add("Ruby")

puts "\nOriginal strings:"
string_container.process { |s| puts s }

puts "\nUppercased strings:"
uppercased = string_container.map { |s| s.upcase }
puts uppercased.inspect
Using Generic Patterns
# A more sophisticated generic-like pattern using modules
module Enumerable
  def filter_map(&block)
    map(&block).select { |item| !item.nil? }
  end

  def partition_by(&block)
    Hash.new { |h, k| h[k] = [] }.tap do |hash|
      each { |item| hash[block.call(item)] << item }
    end
  end
end

class MyList
  include Enumerable

  def initialize(items)
    @items = items
  end

  def each(&block)
    @items.each(&block)
  end

  def map(&block)
    @items.map(&block)
  end

  def select(&block)
    @items.select(&block)
  end
end

# Usage
numbers = MyList.new([1, 2, 3, 4, 5, 6])
evens = numbers.partition_by { |n| n.even? ? :even : :odd }
puts evens.inspect
Benefits
Type Safety: Errors caught at compile-time (in typed languages)
Code Reuse: Write once for multiple types
Performance: No runtime type checking overhead in compiled languages
Expressiveness: Can write sophisticated data structures and algorithms
4. Object Aggregation and Acquaintance: Structuring Relationships
Understanding the Difference
Aggregation and acquaintance are two ways objects relate to each other in object-oriented design:
Aggregation (has-a relationship): An object contains another object as a part of its structure. The contained object is a permanent part of the container.
Acquaintance (uses-a relationship): An object temporarily knows about another object, typically passed as a parameter or obtained through a method call. The relationship is less permanent.
Aggregation Examples
Aggregation represents a “part-of” relationship where an object owns or contains other objects:
# Strong aggregation: Car owns its parts
class Engine
  def initialize(horsepower)
    @horsepower = horsepower
  end

  def start
    puts "Engine with #{@horsepower}hp starting..."
  end

  def stop
    puts "Engine stopping..."
  end
end

class Wheel
  def initialize(size)
    @size = size
  end

  def rotate
    puts "#{@size}\" wheel rotating..."
  end
end

class Car
  def initialize(make, model)
    @make = make
    @model = model
    # Aggregation: Car contains Engine and Wheels
    @engine = Engine.new(200)
    @wheels = [
      Wheel.new(18),
      Wheel.new(18),
      Wheel.new(18),
      Wheel.new(18)
    ]
  end

  def start
    puts "Starting #{@make} #{@model}..."
    @engine.start
  end

  def drive
    @wheels.each(&:rotate)
    puts "Car is moving!"
  end

  def stop
    @engine.stop
    puts "Car stopped."
  end
end

# Usage
car = Car.new("Toyota", "Camry")
car.start
car.drive
car.stop
Key characteristics of aggregation:
The container creates/owns the contained objects
The contained objects are part of the container’s structure
Destroying the container may destroy the contained objects
The relationship is relatively permanent
Acquaintance Examples
Acquaintance represents a “knows-about” relationship where objects interact but don’t own each other:
# Acquaintance: Order knows about Customer and Product
class Customer
  def initialize(name, email)
    @name = name
    @email = email
  end

  def name
    @name
  end

  def email
    @email
  end
end

class Product
  def initialize(name, price)
    @name = name
    @price = price
  end

  def name
    @name
  end

  def price
    @price
  end
end

class Order
  def initialize(order_id)
    @order_id = order_id
    @customer = nil  # Acquaintance: will know about a customer
    @products = []  # Acquaintance: will know about products
    @total = 0
  end

  # Receives a customer as a parameter
  def assign_customer(customer)
    @customer = customer
    puts "Order #{@order_id} assigned to #{customer.name}"
  end

  # Receives products as parameters
  def add_product(product, quantity = 1)
    @products << { product: product, quantity: quantity }
    @total += product.price * quantity
  end

  def display_summary
    puts "\n=== Order Summary ==="
    puts "Order ID: #{@order_id}"
    puts "Customer: #{@customer.name}"
    puts "Items:"
    @products.each do |item|
      puts "  - #{item[:product].name}: $#{item[:product].price} x #{item[:quantity]}"
    end
    puts "Total: $#{@total}"
  end
end

# Usage
customer = Customer.new("Alice Johnson", "alice@example.com")
product1 = Product.new("Laptop", 999)
product2 = Product.new("Mouse", 25)

order = Order.new("ORD-001")
order.assign_customer(customer)
order.add_product(product1)
order.add_product(product2, 2)
order.display_summary
Key characteristics of acquaintance:
Objects are passed as parameters or obtained through method calls
The relationship is temporary and context-dependent
Objects don’t create or own each other
Objects can exist independently
Real-World Comparison: Restaurant System
# AGGREGATION: Restaurant owns its Menu and Tables
class MenuItem
  def initialize(name, price)
    @name = name
    @price = price
  end

  def description
    "#{@name}: $#{@price}"
  end
end

class Table
  def initialize(table_number, capacity)
    @table_number = table_number
    @capacity = capacity
    @is_occupied = false
  end

  def occupy
    @is_occupied = true
  end

  def free
    @is_occupied = false
  end

  def available?
    !@is_occupied
  end
end

class Menu
  def initialize(cuisine_type)
    @cuisine_type = cuisine_type
    @items = []
  end

  def add_item(item)
    @items << item
  end

  def list_items
    @items.map(&:description)
  end
end

class Restaurant
  def initialize(name)
    @name = name
    # AGGREGATION: Restaurant owns these objects
    @menu = Menu.new("Italian")
    @tables = [
      Table.new(1, 4),
      Table.new(2, 6),
      Table.new(3, 2)
    ]
  end

  def setup_menu
    @menu.add_item(MenuItem.new("Pasta Carbonara", 15))
    @menu.add_item(MenuItem.new("Lasagna", 18))
    @menu.add_item(MenuItem.new("Tiramisu", 8))
  end

  def show_menu
    puts "=== #{@name} Menu ==="
    @menu.list_items.each { |item| puts item }
  end

  def reserve_table(party_size)
    available_table = @tables.find { |t| t.available? && t.capacity >= party_size }
    if available_table
      available_table.occupy
      "Table reserved!"
    else
      "No suitable tables available"
    end
  end
end

# ACQUAINTANCE: Reservation knows about Customer and Restaurant
class Reservation
  def initialize(reservation_id)
    @reservation_id = reservation_id
    @customer = nil
    @restaurant = nil
    @time = nil
    @party_size = nil
  end

  def make_reservation(customer, restaurant, time, party_size)
    @customer = customer
    @restaurant = restaurant
    @time = time
    @party_size = party_size
    puts "Reservation #{@reservation_id} made for #{customer.name} at #{time} for #{party_size} people"
  end

  def confirm
    puts "Confirming reservation for #{@customer.name}..."
    result = @restaurant.reserve_table(@party_size)
    puts result
  end
end

# Usage
restaurant = Restaurant.new("Luigi's Italian Kitchen")
restaurant.setup_menu
restaurant.show_menu

customer = Customer.new("Bob Smith", "bob@example.com")
reservation = Reservation.new("RES-001")
reservation.make_reservation(customer, restaurant, "7:00 PM", 4)
reservation.confirm
When to Use Each
Aspect
Aggregation
Acquaintance
Relationship
Part-of, owns
Uses, knows-about
Lifetime
Container controls
Independent
Creation
Container creates
External creation
Use Case
Car-Engine, House-Rooms
Customer-Order, Client-Service
Dependency
Strong coupling
Loose coupling
Benefits
Aggregation:
Clear ownership and lifecycle management
Encapsulation of related components
Simplified understanding of object structure
Acquaintance:
Loose coupling between objects
Better testability and modularity
More flexible object interactions
Easier to extend and modify
Putting It All Together: A Complete Example
Let’s create a library system that demonstrates all four concepts:
# TEMPLATE METHOD: Base class for different user types
class LibraryUser
def initialize(name)
@name = name
@borrowed_books = []
end
def process_checkout(book)
check_eligibility
check_availability(book)
checkout_book(book)
send_confirmation(book)
end
protected
def check_eligibility
raise NotImplementedError
end
def check_availability(book)
puts "Checking if #{book.title} is available..."
end
def checkout_book(book)
@borrowed_books << book
puts "Book checked out successfully"
end
def send_confirmation(book)
puts "Sending confirmation to #{@name}"
end
end
class Student < LibraryUser
def check_eligibility
puts "Checking student ID and membership status..."
end
def send_confirmation(book)
puts "Emailing confirmation to student: #{@name}"
end
end
class Faculty < LibraryUser
def check_eligibility
puts "Checking faculty status..."
end
def checkout_book(book)
@borrowed_books << book
puts "Faculty member can borrow up to 20 items"
end
end
# AGGREGATION: Library owns Books and has Shelves
class Book
attr_reader :title, :author
def initialize(title, author, isbn)
@title = title
@author = author
@isbn = isbn
@is_available = true
end
def available?
@is_available
end
def checkout
@is_available = false
end
def return_book
@is_available = true
end
end
class Shelf
def initialize(section, capacity)
@section = section
@capacity = capacity
@books = []
end
def add_book(book)
@books << book if @books.length < @capacity
end
def list_books
@books.map(&:title)
end
end
class Library
def initialize(name)
@name = name
# AGGREGATION: Library owns shelves and manages books
Understanding when and how to apply each concept leads to more flexible, maintainable, and scalable software. Ruby’s flexibility makes these patterns particularly elegant to implement, though the principles apply across all modern programming languages.
The key is choosing the right tool for the right problem: use Template Method when you have variations of a fixed process, use Strategy for interchangeable algorithms, use generics for type-flexible code, and use appropriate aggregation/acquaintance patterns to structure your object relationships cleanly.
A developer’s guide to understanding Stripe’s API transformation and avoiding common migration pitfalls
The payment processing landscape has evolved dramatically over the past decade, and Stripe has been at the forefront of this transformation. One of the most significant changes in Stripe’s ecosystem was the transition from the Charges API to the Payment Intents API. This shift wasn’t just a cosmetic update – it represented a fundamental reimagining of how online payments should work in an increasingly complex global marketplace.
The Old World: Charges API (2011-2019)
The Simple Days
When Stripe first launched, online payments were relatively straightforward. The Charges API reflected this simplicity:
# The old way - direct charge creation
charge = Stripe::Charge.create({
  amount: 2000,
  currency: 'usd',
  source: 'tok_visa',  # Token from Stripe.js
  description: 'Example charge'
})

if charge.paid
  # Payment succeeded, fulfill order
  fulfill_order(charge.id)
else
  # Payment failed, show error
  handle_error(charge.failure_message)
end
This approach was beautifully simple: create a charge, check if it succeeded, done. The API returned a charge object with an ID like ch_1234567890, and that was your payment.
What Made It Work
The Charges API thrived in an era when:
Card payments dominated – Most transactions were simple credit/debit cards
3D Secure was optional – Strong customer authentication wasn’t mandated
Regulations were simpler – PCI DSS was the main compliance concern
Payment methods were limited – Mostly cards, with PayPal as the main alternative
Mobile payments were nascent – Most transactions happened on desktop browsers
The Cracks Begin to Show
As the payments ecosystem evolved, the limitations of the Charges API became apparent:
Authentication Challenges: When 3D Secure authentication was required, the simple charge-and-done model broke down. Developers had to handle redirects, callbacks, and asynchronous completion manually.
Mobile Payment Integration: Apple Pay and Google Pay required more complex flows that didn’t map well to direct charge creation.
Regulatory Compliance: European PSD2 regulations introduced Strong Customer Authentication (SCA) requirements that the Charges API couldn’t elegantly handle.
Webhook Reliability: With complex payment flows, relying on synchronous responses became insufficient. Webhooks were critical, but the Charges API didn’t provide a cohesive event model.
The Catalyst: PSD2 and Strong Customer Authentication
The European Union’s Revised Payment Services Directive (PSD2), which came into effect in 2019, was the final nail in the coffin for simple payment flows. PSD2 mandated Strong Customer Authentication (SCA) for most online transactions, requiring:
Two-factor authentication for customers
Dynamic linking between payment and authentication
Exemption handling for low-risk transactions
The Charges API, with its synchronous create-and-complete model, simply couldn’t handle these requirements elegantly.
The New Era: Payment Intents API (2019-Present)
A Paradigm Shift
Stripe’s response was revolutionary: instead of treating payments as simple charge operations, they reconceptualized them as intents that could evolve through multiple states:
# The modern way - intent-based payments
payment_intent = Stripe::PaymentIntent.create({
  amount: 2000,
  currency: 'usd',
  payment_method: 'pm_card_visa',
  confirmation_method: 'manual',
  capture_method: 'automatic'
})

case payment_intent.status
when 'requires_confirmation'
  # Confirm the payment intent
  payment_intent.confirm
when 'requires_action'
  # Handle 3D Secure or other authentication
  handle_authentication(payment_intent.client_secret)
when 'succeeded'
  # Payment completed, fulfill order
  fulfill_order(payment_intent.id)
when 'requires_payment_method'
  # Payment failed, request new payment method
  handle_payment_failure
end
The Intent Lifecycle
Payment Intents introduced a state machine that could handle complex payment flows:
Payment Intents provide richer webhook events that track the entire payment lifecycle:
# webhook_endpoints.rb
case event.type
when 'payment_intent.succeeded'
  handle_successful_payment(event.data.object)
when 'payment_intent.payment_failed'
  handle_failed_payment(event.data.object)
when 'payment_intent.requires_action'
  notify_customer_action_required(event.data.object)
end
3. Client-Side Integration
The Payment Intents API encouraged better client-side integration through Stripe Elements and mobile SDKs:
Many applications need to update their database schemas to accommodate both old and new payment types:
# Migration to support both charge and payment intent IDs
class AddPaymentIntentSupport < ActiveRecord::Migration[6.0]
  def change
    add_column :payments, :stripe_payment_intent_id, :string
    add_column :payments, :payment_type, :string, default: 'charge'

    add_index :payments, :stripe_payment_intent_id
    add_index :payments, :payment_type
  end
end

# Updated model to handle both
class Payment < ApplicationRecord
  def stripe_id
    case payment_type
    when 'payment_intent'
      stripe_payment_intent_id
    when 'charge'
      stripe_charge_id
    end
  end

  def refundable_charge_id
    if payment_type == 'payment_intent'
      # Fetch the actual charge ID from the payment intent
      pi = Stripe::PaymentIntent.retrieve(stripe_payment_intent_id)
      pi.charges.data.first.id
    else
      stripe_charge_id
    end
  end
end
Webhook Handler Updates
Webhook handling becomes more sophisticated with Payment Intents:
# Legacy charge webhook handling
def handle_charge_webhook(event)
  charge = event.data.object

  case event.type
  when 'charge.succeeded'
    mark_payment_successful(charge.id)
  when 'charge.failed'
    mark_payment_failed(charge.id)
  end
end

# Modern payment intent webhook handling
def handle_payment_intent_webhook(event)
  payment_intent = event.data.object

  case event.type
  when 'payment_intent.succeeded'
    # Payment completed successfully
    complete_order(payment_intent.id)

  when 'payment_intent.payment_failed'
    # All payment attempts have failed
    cancel_order(payment_intent.id)

  when 'payment_intent.requires_action'
    # Customer needs to complete authentication
    notify_action_required(payment_intent.id, payment_intent.client_secret)

  when 'payment_intent.amount_capturable_updated'
    # Partial capture scenarios
    handle_partial_authorization(payment_intent.id)
  end
end
Best Practices for Modern Stripe Integration
1. Embrace Asynchronous Patterns
With Payment Intents, assume payments are asynchronous:
class PaymentProcessor
  def create_payment(amount, customer_id, payment_method_id)
    payment_intent = Stripe::PaymentIntent.create({
      amount: amount,
      currency: 'usd',
      customer: customer_id,
      payment_method: payment_method_id,
      confirmation_method: 'automatic',
      return_url: success_url
    })

    # Don't assume immediate success
    case payment_intent.status
    when 'succeeded'
      complete_payment_immediately(payment_intent)
    when 'requires_action'
      # Send client_secret to frontend for authentication
      { status: 'requires_action', client_secret: payment_intent.client_secret }
    when 'requires_payment_method'
      { status: 'failed', error: 'Payment method declined' }
    else
      # Wait for webhook confirmation
      { status: 'processing', payment_intent_id: payment_intent.id }
    end
  end
end
2. Implement Robust Webhook Handling
Webhooks are critical for Payment Intents—implement them defensively:
class StripeWebhookController < ApplicationController
  protect_from_forgery except: :handle

  def handle
    payload = request.body.read
    sig_header = request.env['HTTP_STRIPE_SIGNATURE']

    begin
      event = Stripe::Webhook.construct_event(
        payload, sig_header, ENV['STRIPE_WEBHOOK_SECRET']
      )
    rescue JSON::ParserError, Stripe::SignatureVerificationError
      head :bad_request and return
    end

    # Handle idempotently
    return head :ok if processed_event?(event.id)

    case event.type
    when 'payment_intent.succeeded'
      PaymentSuccessJob.perform_later(event.data.object.id)
    when 'payment_intent.payment_failed'
      PaymentFailureJob.perform_later(event.data.object.id)
    end

    mark_event_processed(event.id)
    head :ok
  end

  private

  def processed_event?(event_id)
    Rails.cache.exist?("stripe_event_#{event_id}")
  end

  def mark_event_processed(event_id)
    Rails.cache.write("stripe_event_#{event_id}", true, expires_in: 24.hours)
  end
end
3. Handle Multiple Payment Methods Gracefully
Payment Intents excel at handling diverse payment methods:
Payment Intents provide detailed error information:
def handle_payment_error(payment_intent)
  last_payment_error = payment_intent.last_payment_error

  case last_payment_error&.code
  when 'authentication_required'
    # Redirect to 3D Secure
    redirect_to_authentication(payment_intent.client_secret)

  when 'card_declined'
    decline_code = last_payment_error.decline_code
    case decline_code
    when 'insufficient_funds'
      show_error("Insufficient funds on your card")
    when 'expired_card'
      show_error("Your card has expired")
    else
      show_error("Your card was declined")
    end

  when 'processing_error'
    show_error("A processing error occurred. Please try again.")

  else
    show_error("An unexpected error occurred")
  end
end
The Future: What’s Next?
1. Embedded Payments
Stripe continues to innovate with embedded payment solutions that make Payment Intents even more powerful:
As real-time payment networks like FedNow and Open Banking expand, Payment Intents provide the flexibility to support these new methods seamlessly.
3. Cross-Border Optimization
Payment Intents are evolving to better handle multi-currency and cross-border transactions with improved routing and local payment method support.
Key Takeaways for Developers
Payment Intents are the future: If you’re building new payment functionality, start with Payment Intents, not Charges.
Embrace asynchronous patterns: Don’t expect payments to complete immediately. Design your system around webhooks and state management.
Handle the ID confusion: Remember that Payment Intents (pi_) contain Charges (ch_). Refunds and some other operations still work on charge IDs.
Implement robust webhook handling: With complex payment flows, webhooks become critical infrastructure, not nice-to-have features.
Test thoroughly: The increased complexity of Payment Intents requires more comprehensive testing, especially around authentication flows and edge cases.
Monitor proactively: Use Stripe’s dashboard and logs extensively during development and deployment to understand payment flow behavior.
Conclusion
The evolution from Stripe’s Charges API to Payment Intents represents more than just a technical upgrade—it’s a fundamental shift toward a more flexible, regulation-compliant, and globally-aware payment processing model. While the migration requires thoughtful planning and careful implementation, the benefits in terms of supported payment methods, authentication handling, and regulatory compliance make it essential for any serious payment processing application.
The key is to approach the migration systematically: understand the differences, plan for the ID confusion, implement robust webhook handling, and test extensively. With these foundations in place, Payment Intents unlock capabilities that simply weren’t possible with the older Charges API.
As global payment regulations continue to evolve and new payment methods emerge, Payment Intents provide the architectural flexibility to adapt and grow. The initial complexity investment pays dividends in long-term maintainability and feature capability.
For developers still using the Charges API, the writing is on the wall: it’s time to embrace the future of payment processing with Payment Intents.
Have you encountered similar challenges migrating from Charges to Payment Intents? What patterns have worked best in your applications? Share your experiences in the comments below.
Ruby is one of the few languages where classes are objects, capable of holding both instance behavior and class-level behavior. This flexibility comes from a powerful internal structure: the singleton class, also known as the eigenclass. Every Ruby object has one — including classes themselves.
When developers write class << self, they are opening a special, hidden class that Ruby uses to store methods that belong to the class object, not its instances. This technique is the backbone of Ruby’s expressive meta-programming features and is used heavily in Rails, Sidekiq, ActiveRecord, RSpec, and nearly every major Ruby framework.
This article explains why Ruby has singleton classes, what they enable, and when you should use class << self instead of def self.method for defining class-level behavior.
In Ruby, writing:
class Payment; end
creates an object:
Payment.instance_of?(Class) # => true
Since Payment is an object, it can have:
Its own methods
Its own attributes
Its own included modules
Just like any other object.
Ruby stores these class-specific methods in a special internal structure: the singleton class of Payment.
When you define a class method:
def self.process
end
Ruby is actually doing this under the hood:
Open the singleton class of Payment
Define process inside it
So:
class << Payment
  def process; end
end
and:
def Payment.process; end
and:
def self.process; end
All do the same thing.
But class << self unlocks far more power.
Each Ruby object has:
[ Object ] ---> [ Singleton Class ] ---> [ Its Class ]
Instance methods live in Payment. Class methods live in Payment's eigenclass.
The eigenclass is where Ruby stores:
Class methods
Per-object overrides
Class-specific attributes
DSL behaviors
class << self
  def load; end
  def export; end
  def sync; end
end
Cleaner than:
def self.load; end
def self.export; end
def self.sync; end
This is a huge advantage.
class << self
  private

  def connection_pool
    @pool ||= ConnectionPool.new
  end
end
Using def self.method cannot make the method private — Ruby doesn’t allow it.
class << self
  include CacheHelpers
end
This modifies class-level behavior, not instance behavior.
Rails uses this technique everywhere.
You must open the eigenclass:
class << self
  def new(*args)
    puts "Creating a new Payment!"
    super
  end
end
This cannot be done properly with def self.new.
class << self
  attr_accessor :config
end
Usage:
Payment.config = { currency: "USD" }
This config belongs to the class itself.
Example from ActiveRecord:
class << self
  def has_many(name)
    # defines association
  end
end
Or RSpec:
class << self
  def describe(text, &block)
    # builds DSL structure
  end
end
When you write:
class Order < ApplicationRecord
  has_many :line_items
end
Internally Rails does:
class Order
  class << self
    def has_many(name)
      # logic here
    end
  end
end
This is how Rails builds its elegant DSL.
class << self
  def before_save(method_name)
    set_callback(:save, :before, method_name)
  end
end
Again, these DSL methods live in the singleton class.
✅ Use def self.method_name when:
Only defining 1–2 methods
Simpler readability is preferred
✅ Use class << self when:
You have many class methods
You require private class methods
You need to include modules at class level
You are building DSLs or metaprogramming-heavy components
You need to override class-level behavior (new, allocate)
Opening a class’s singleton class (class << self) is not just a stylistic choice — it is a powerful meta-programming technique that lets you modify the behavior of the class object itself. Because Ruby treats classes as first-class objects, their singleton classes hold the key to defining class methods, private class-level utilities, DSLs, and dynamic meta-behavior.
Understanding how and why Ruby uses the eigenclass gives you deeper insight into the design of Rails, Sidekiq, ActiveRecord, and virtually all major Ruby libraries.
It’s one of the most elegant aspects of Ruby’s object model — and one of its most powerful once mastered.
In Ruby, everything is an object – and that includes classes themselves. A class like Payment is actually an instance of Class, meaning it can have its own methods, attributes, and behavior just like any other object. Because every object in Ruby has a special hidden class called a singleton class (or eigenclass), Ruby uses this mechanism to store methods that belong specifically to the class object, rather than to its instances.
When developers open a class’s eigenclass using class << self, they are directly modifying this singleton class, gaining access to unique meta-programming abilities not available through normal def self.method definitions. This approach lets you define private class methods, include modules into a class’s singleton behavior, override internal methods like new or allocate, group multiple class methods cleanly, and create flexible DSLs. Ultimately, opening the eigenclass enables fine-grained control over a Ruby class’s meta-level behavior, a powerful tool when writing expressive, maintainable frameworks and advanced Ruby code.
? Why Ruby Needs a Singleton Class for the Class Object
Ruby separates instance behavior from class behavior:
Instance methods live in the class (Payment)
Class methods live in the class’s singleton class (Payment.singleton_class)
This means:
def self.process
end
and:
class << self
  def process
  end
end
are doing the same thing – defining a method on the class’s eigenclass.
But class << self gives you more control.
What You Can Do With class << self That You Can’t Do With def self.method
1. Group multiple class methods without repeating self.
class << self
  def load_data; end
  def generate_stats; end
  def export; end
end
Cleaner and more readable when many class methods exist.
2. Make class methods private
This is a BIG reason to open the eigenclass.
class << self
  private

  def secret_config
    "hidden!"
  end
end
With def self.secret_config, you cannot make it private.
3. Add modules to the class’s singleton behavior
This modifies the class itself, not its instances.
class << self
  include SomeClassMethods
end
Equivalent to:
extend SomeClassMethods
But allows mixing visibility (public/private/protected).
class << self
  def allocate
    puts "custom allocation"
    super
  end
end
This cannot be done correctly with def self.allocate.
5. Implement DSLs and class-level configuration
Rails, RSpec, Sidekiq, and ActiveRecord all use this.
class << self
  attr_accessor :config
end
Now the class has its own state:
Payment.config = { mode: :test }
Understanding the Bigger Picture — Ruby’s Meta-Object Model
Ruby treats classes as objects, and every object has:
A class where instance methods live
A singleton class where methods specific to that object live
So:
Instance methods → stored in the class (Payment)
Class methods → stored in the singleton class (Payment.singleton_class)
Opening the eigenclass means directly modifying that second structure.
When Should You Use class << self?
Use class << self when:
✔ You have several class methods to define ✔ You need private/protected class methods ✔ You want to include or extend modules into the class’s behavior ✔ You need to override class-level built-ins (new, allocate) ✔ You’re implementing DSLs or framework-level code
Use def self.method when:
✔ You’re defining one or two simple class methods ✔ You want the simplest, most readable syntax
🎯 Final Takeaway
Opening the singleton class at the class level isn’t just stylistic — it unlocks capabilities that normal class method definitions cannot provide. It’s a powerful tool for clean organization, encapsulation, and meta-programming. Frameworks like Rails rely heavily on this pattern because it allows precise control over how classes behave at a meta-level.
Understanding this distinction helps you write cleaner, more flexible Ruby code — and it deepens your appreciation of Ruby’s elegant object model.
In the next article, we can check more examples in detail.

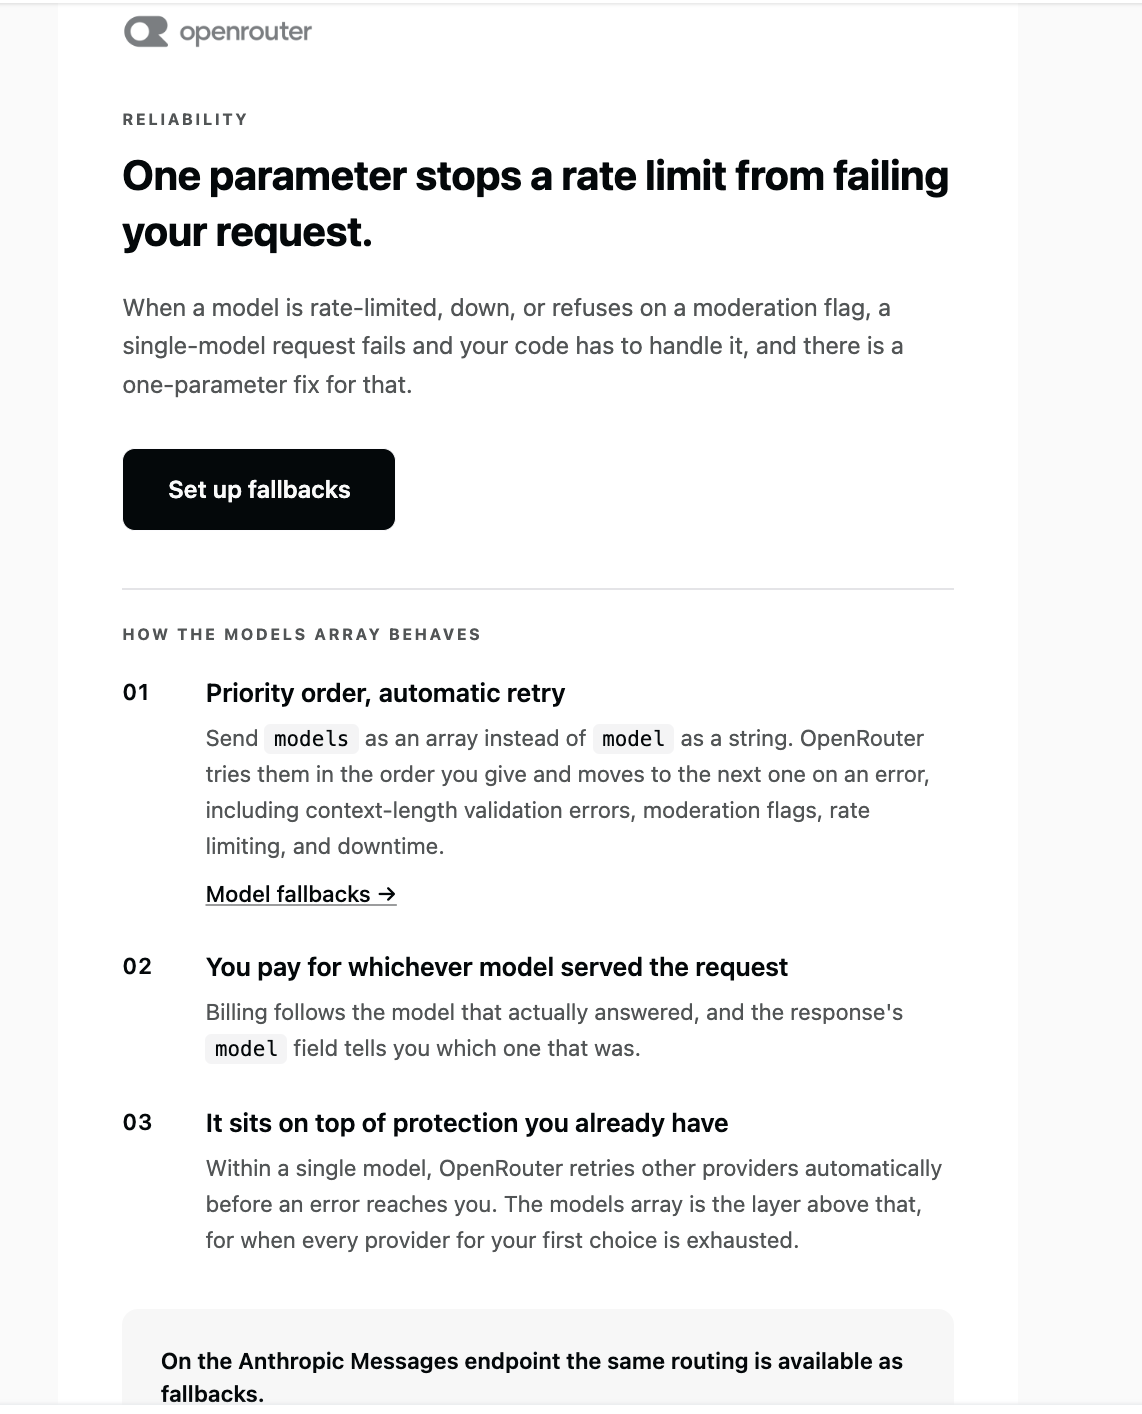
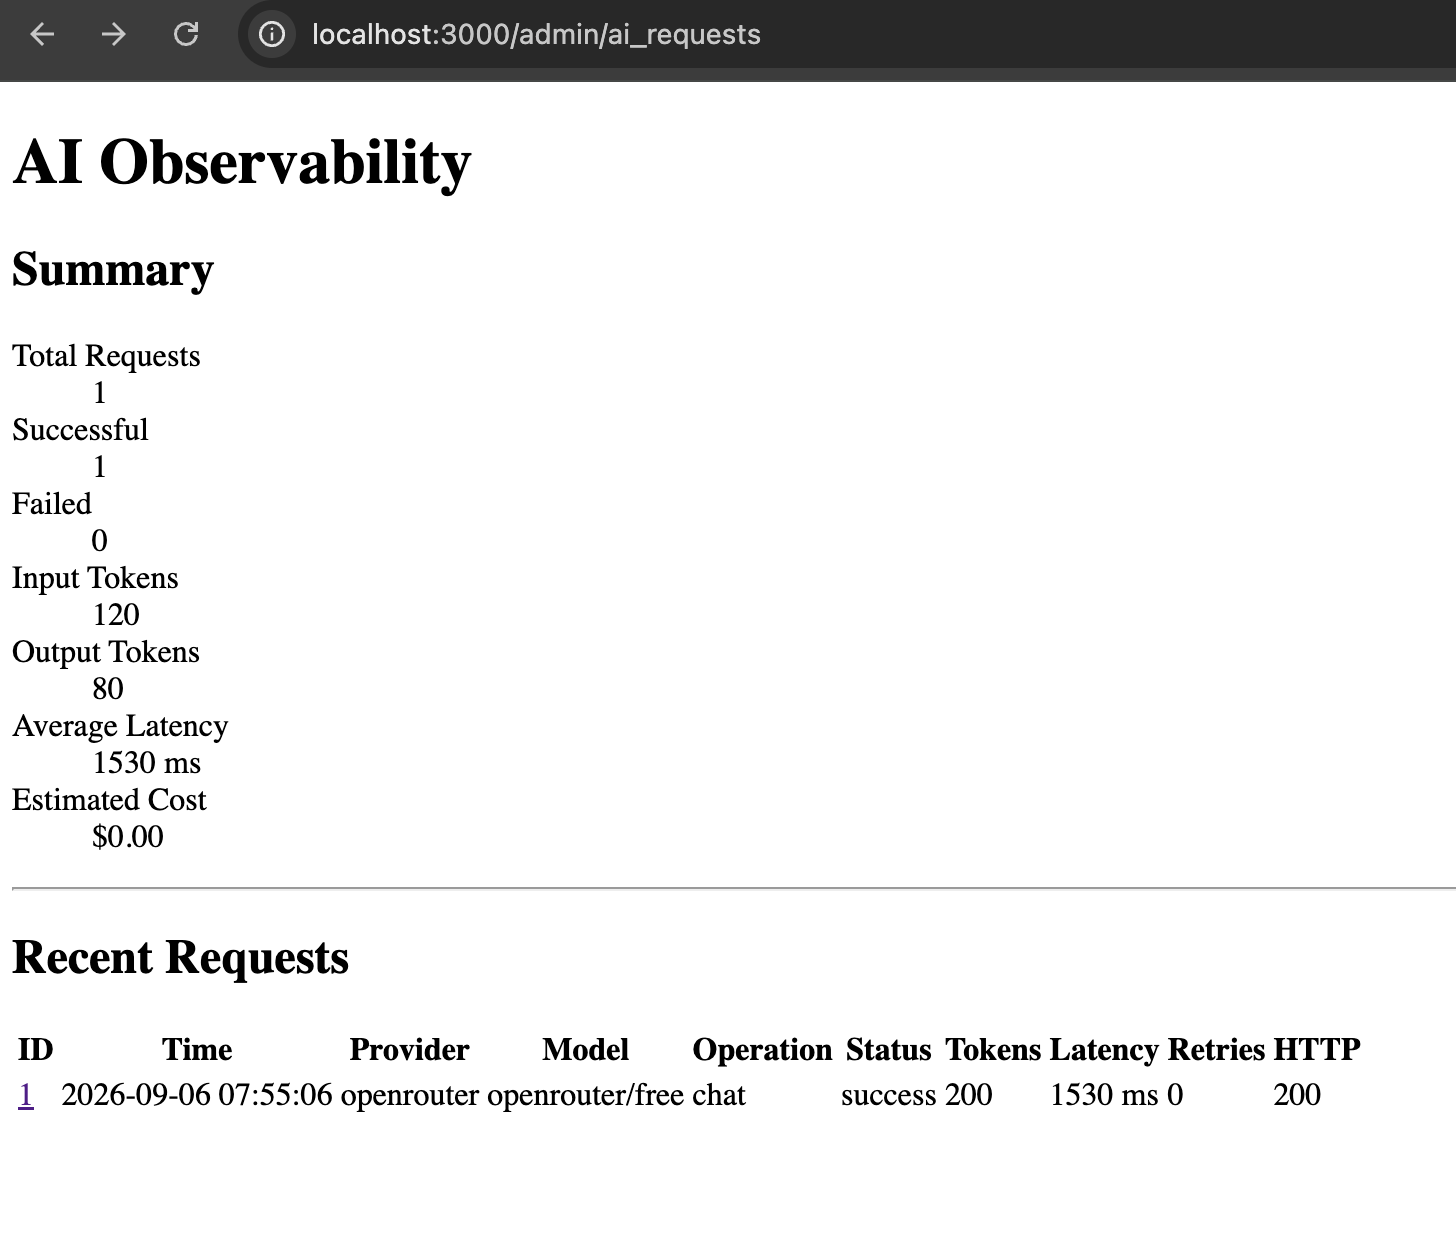
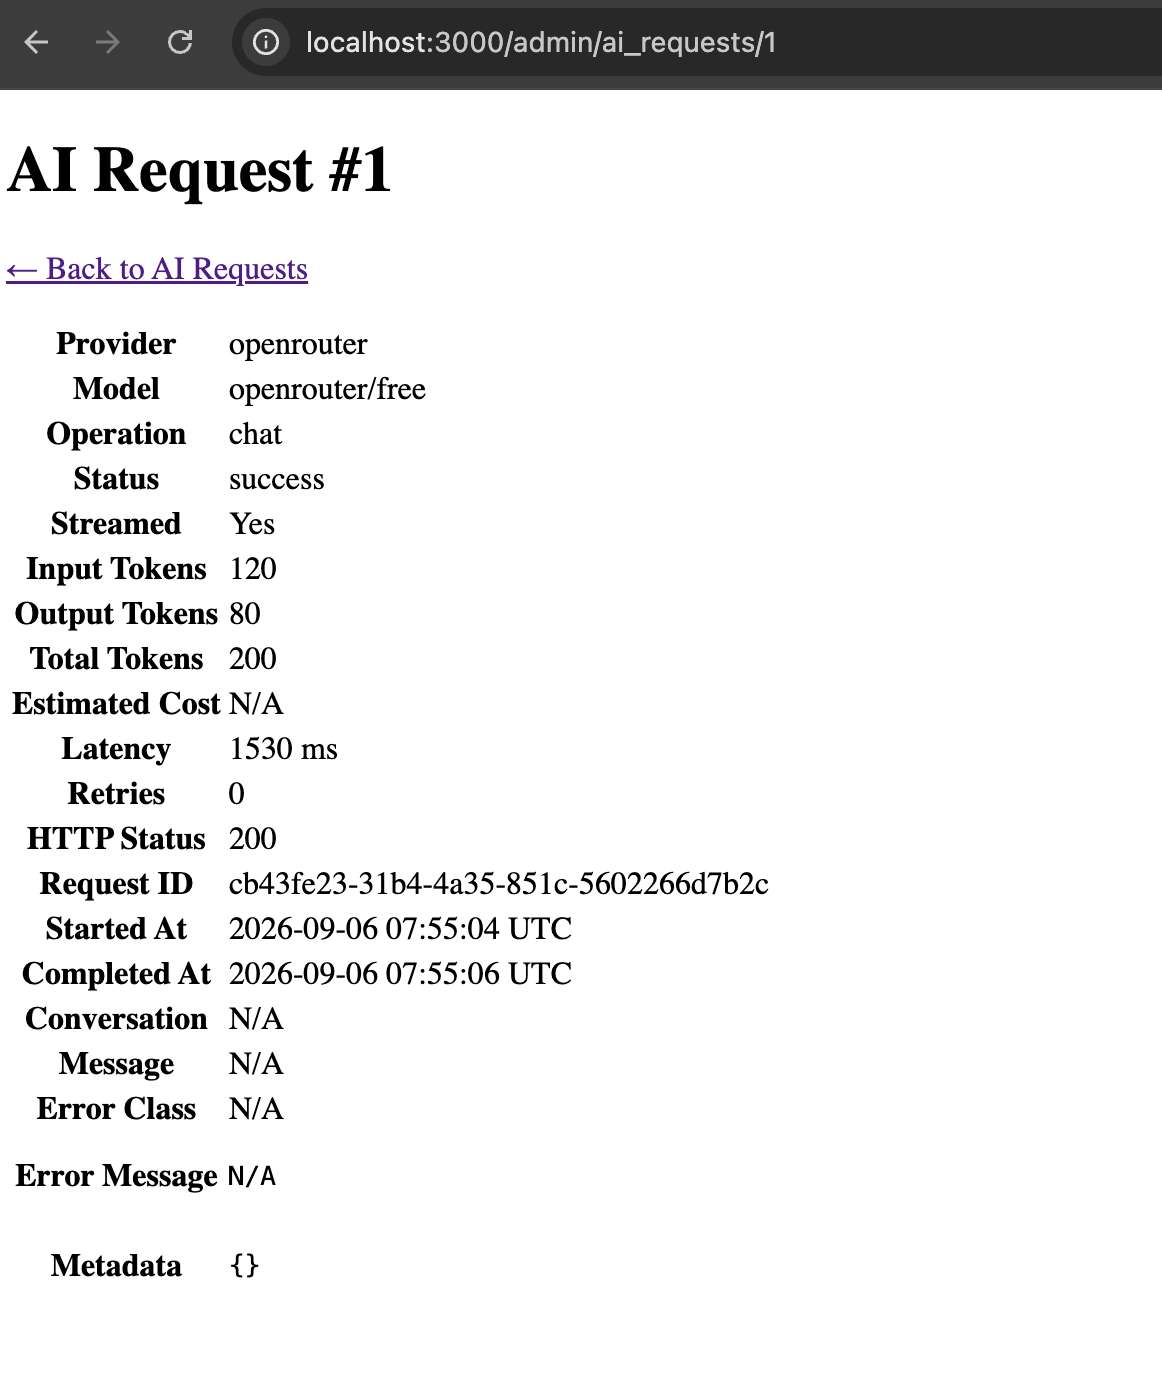

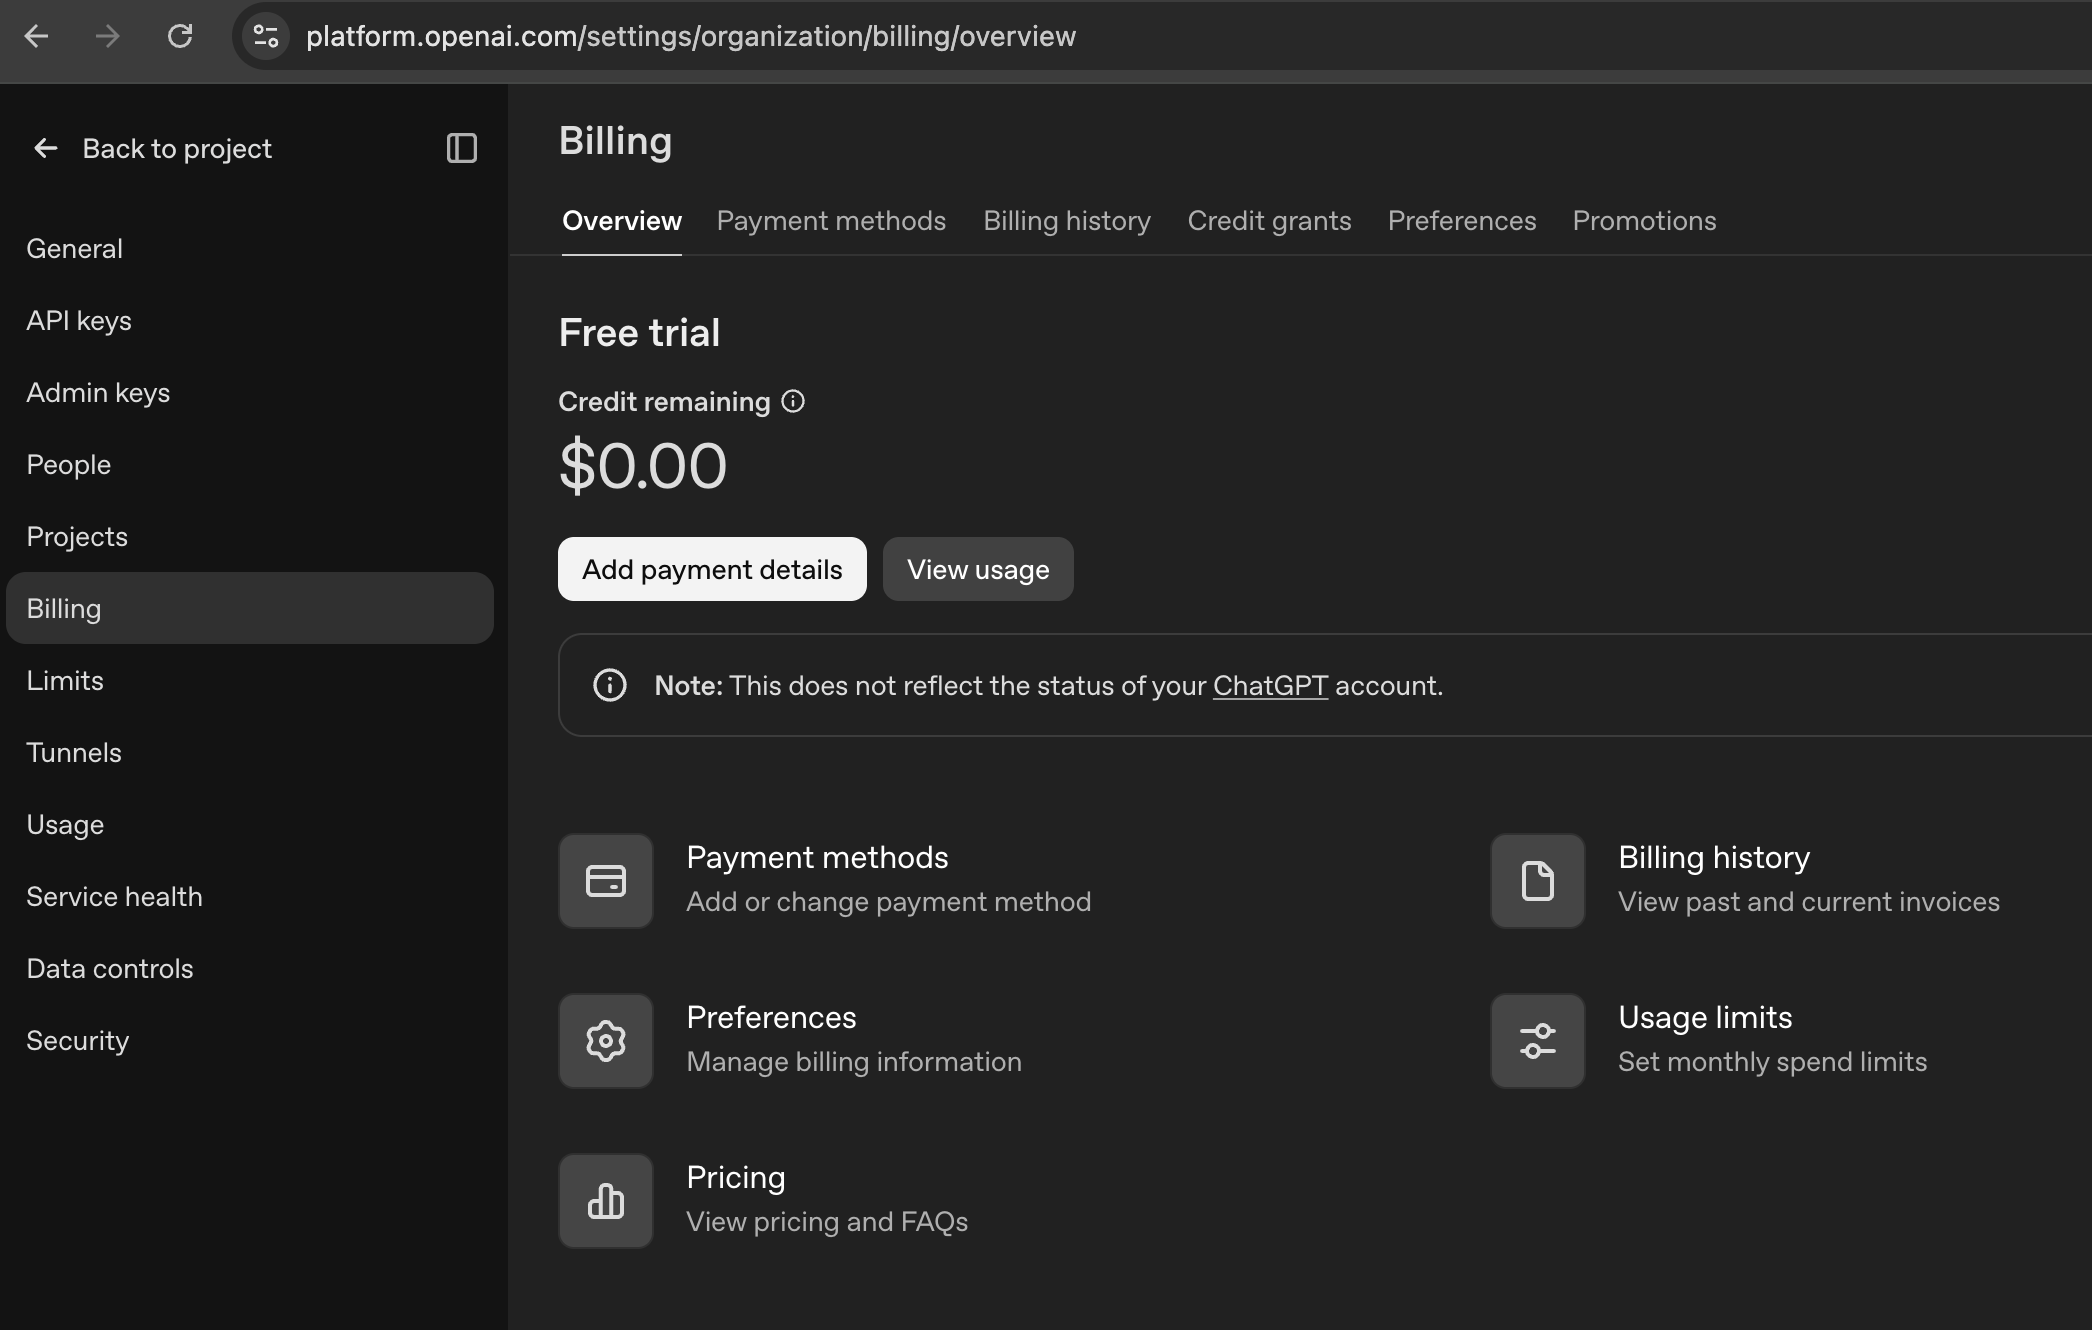
 The Rails Drop
