Can We Do Type Checking in Ruby Method Parameters?

Ruby is a dynamically typed language that favors duck typing over strict type enforcement. However, there are cases where type checking can be useful to avoid unexpected behavior. In this post, we’ll explore various ways to perform type validation and type checking in Ruby.

Type Checking and Type Casting in Ruby

Yes, even though Ruby does not enforce types at the language level, there are several techniques to validate the types of method parameters. Below are some approaches:

1. Manual Type Checking with raise

One straightforward way to enforce type checks is by manually verifying the type of a parameter using is_a? and raising an error if it does not match the expected type.

def my_method(arg)
  raise TypeError, "Expected String, got #{arg.class}" unless arg.is_a?(String)
  
  puts "Valid input: #{arg}"
end

my_method("Hello")  # Works fine
my_method(123)      # Raises: TypeError: Expected String, got Integer

2. Using respond_to? for Duck Typing

Rather than enforcing a strict class type, we can check whether an object responds to a specific method.

def my_method(arg)
  unless arg.respond_to?(:to_str)
    raise TypeError, "Expected a string-like object, got #{arg.class}"
  end
  
  puts "Valid input: #{arg}"
end

my_method("Hello")  # Works fine
my_method(:symbol)  # Raises TypeError

3. Using Ruby 3’s Type Signatures (RBS)

Ruby 3 introduced RBS and TypeProf for static type checking. You can define types in an .rbs file:

def my_method: (String) -> void

Then, you can use tools like steep, a static type checker for Ruby, to enforce type checking at development time.

How to Use Steep for Type Checking

Steep does not use annotations or perform type inference on its own. Instead, it relies on .rbi files to define type signatures. Here’s how you can use Steep for type checking:

  1. Define a Ruby Class:
class Calculator
  def initialize(value)
    @value = value
  end
  
  def double
    @value * 2
  end
end

  1. Generate an .rbi File:
steep scaffold calculator.rb > sig/calculator.rbi

This generates an .rbi file, but initially, it will use any for all types. You need to manually edit it to specify proper types.

  1. Modify the .rbi File to Define Types:
class Calculator
  @value: Integer
  def initialize: (Integer) -> void
  def double: () -> Integer
end

  1. Run Steep to Check Types:
steep check

Steep also supports generics and union types, making it a powerful but less intrusive type-checking tool compared to Sorbet.

4. Using Sorbet for Stronger Type Checking

Sorbet is a third-party static type checker that allows you to enforce type constraints at runtime.

require 'sorbet-runtime'

extend T::Sig

sig { params(arg: String).void }
def my_method(arg)
  puts "Valid input: #{arg}"
end

my_method("Hello")  # Works fine
my_method(123)      # Raises error at runtime

References:

Another Approach: Using Rescue for Type Validation

A different way to handle type checking is by using exception handling (rescue) to catch unexpected types and enforce validation.

def process_order(order_items, customer_name, discount_code)
  # Main logic
  ...

rescue => e
  # Type and validation checks
  raise "Expecting an array of items: #{order_items.inspect}" unless order_items.is_a?(Array)
  raise "Order must contain at least one item: #{order_items.inspect}" if order_items.empty?
  raise "Expecting a string for customer name: #{customer_name.inspect}" unless customer_name.is_a?(String)
  raise "Customer name cannot be empty" if customer_name.strip.empty?
  
  raise "Unexpected error in `process_order`: #{e.message}"
end

Summary

  • Use is_a? or respond_to? for runtime type checking.
  • Use Ruby 3’s RBS for static type enforcement.
  • Use Sorbet for stricter type checking at runtime.
  • Use Steep for static type checking with RBS.
  • Exception handling can be used for validating types dynamically.

Additional Considerations

Ruby is a dynamically typed language, and unit tests can often be more effective than type checks in ensuring correctness. Writing tests ensures that method contracts are upheld for expected data.

For Ruby versions prior to 3.0, install the rbs gem separately to define types for classes.

If a method is defined, it will likely be called. If reasonable tests exist, every method will be executed and checked. Therefore, instead of adding excessive type checks, investing time in writing tests can be a better strategy.
Installing ⚙️ and Setting Up 🔧 Ruby 3.4, Rails 8.0 and IDE on macOS in 2025

Ruby on Rails is a powerful framework for building web applications. If you’re setting up your development environment on macOS in 2025, this guide will walk you through installing Ruby 3.4, Rails 8, and a best IDE for development.

1. Installing Ruby and Rails

“While macOS comes with Ruby pre-installed, it’s often outdated and can’t be upgraded easily. Using a version manager like Mise allows you to install the latest Ruby version, switch between versions, and upgrade as needed.” – Rails guides

Install Dependencies

Run the following command to install essential dependencies (takes time):

brew install openssl@3 libyaml gmp rust

…..
==> Installing rust dependency: libssh2, readline, sqlite, python@3.13, pkgconf
==> Installing rust

zsh completions have been installed to:
/opt/homebrew/share/zsh/site-functions
==> Summary
🍺 /opt/homebrew/Cellar/rust/1.84.1: 3,566 files, 321.3MB
==> Running brew cleanup rust
==> openssl@3
A CA file has been bootstrapped using certificates from the system
keychain. To add additional certificates, place .pem files in
/opt/homebrew/etc/openssl@3/certs

and run
/opt/homebrew/opt/openssl@3/bin/c_rehash
==> rust
zsh completions have been installed to:
/opt/homebrew/share/zsh/site-functions

Install Mise Version Manager

curl https://mise.run | sh
echo 'eval "$(~/.local/bin/mise activate zsh)"' >> ~/.zshrc
source ~/.zshrc

Install Ruby and Rails

mise use -g ruby@3
mise ruby@3.4.1 ✓ installed
mise ~/.config/mise/config.toml tools: ruby@3.4.1

ruby --version   # output Ruby 3.4.1

gem install rails

# reload terminal and check
rails --version  # output Rails 8.0.1

For additional guidance, refer to these resources:


2. Installing an IDE for Ruby on Rails Development

Choosing the right Integrated Development Environment (IDE) is crucial for productivity. Here are some popular options:

RubyMine

  • Feature-rich and specifically designed for Ruby on Rails.
  • Includes debugging tools, database integration, and smart code assistance.
  • Paid software that can be resource-intensive.

Sublime Text

  • Lightweight and highly customizable.
  • Requires plugins for additional functionality.

Visual Studio Code (VS Code) (Recommended)

  • Free and open-source.
  • Excellent plugin support.

Install VS Code

Follow the official installation guide.

Enable GitHub Copilot for AI-assisted coding:

  1. Open VS Code.
  2. Sign in with your GitHub account.
  3. Enable Copilot from the extensions panel.

To use VS Code from the terminal, ensure code is added to your $PATH:

  1. Open Command Palette (Cmd+Shift+P).
  2. Search for Shell Command: Install 'code' command in PATH.
  3. Restart your terminal and try: code .

3. Your 15 Essential VS Code Extensions for Ruby on Rails

To enhance your development workflow, install the following VS Code extensions:

  1. GitHub Copilot – AI-assisted coding (already installed).
  2. vscode-icons – Better file and folder icons.
  3. Tabnine AI – AI autocompletion for JavaScript and other languages.
  4. Ruby & Ruby LSP – Language support and linting.
  5. ERB Formatter/Beautify – Formats .erb files (requires htmlbeautifier gem): gem install htmlbeautifier
  6. ERB Helper Tags – Autocomplete for ERB tags.
  7. GitLens – Advanced Git integration.
  8. Ruby Solargraph – Provides code completion and inline documentation (requires solargraph gem): gem install solargraph
  9. Rails DB Schema – Auto-completion for Rails database schema.
  10. ruby-rubocop – Ruby linting and auto-formatting (requires rubocop gem): gem install rubocop
  11. endwise – Auto-adds end keyword in Ruby.
  12. Output Colorizer – Enhances syntax highlighting in log files.
  13. Auto Rename Tag – Automatically renames paired HTML/Ruby tags.
  14. Highlight Matching Tag – Highlights matching tags for better visibility.
  15. Bracket Pair Colorizer 2 – Improved bracket highlighting.

Conclusion

By following this guide, you’ve successfully set up a robust Ruby on Rails development environment on macOS. With Mise for version management, Rails installed, and VS Code configured with essential extensions, you’re ready to start building Ruby on Rails applications.

Part 2: https://railsdrop.com/2025/03/22/setup-rails-8-app-rubocop-actiontext-image-processing-part-2

Happy Rails setup! 🚀

Setting Up Terminal 🖥️ for Development on MacOS (Updated 2025)

If you’re setting up your MacBook for development, having a well-configured terminal is essential. This guide will walk you through installing and configuring a powerful terminal setup using Homebrew, iTerm2, and Oh My Zsh, along with useful plugins.

1. Install Homebrew

Homebrew is a package manager that simplifies installing software on macOS.

Open the Terminal and run:

/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"

After installation, add Homebrew to your PATH by running the following commands:

echo >> ~/.zprofile
echo 'eval "$(/opt/homebrew/bin/brew shellenv)"' >> ~/.zprofile
eval "$(/opt/homebrew/bin/brew shellenv)"

Verify installation:

brew --version

Check here.

2. Install iTerm2

The default macOS Terminal is functional but lacks advanced features. iTerm2 is a powerful alternative.

Install it using Homebrew:

brew install --cask iterm2

Open iTerm2 from your Applications folder after installation.

Check and Install Git

Ensure Git is installed:

git --version

If not installed, install it using Homebrew:

brew install git

3. Install Oh My Zsh

Oh My Zsh enhances the Zsh shell with themes and plugins. Install it with:

sh -c "$(curl -fsSL https://raw.githubusercontent.com/ohmyzsh/ohmyzsh/master/tools/install.sh)"

Check here.

Configure .zshrc

Edit your .zshrc file:

vim ~/.zshrc

Add useful plugins:

plugins=(git rails ruby)

The default theme is robbyrussell. You can explore other themes here.

Customize iTerm2 Color Scheme

Find and import themes from iTerm2 Color Schemes.

4. Add Zsh Plugins

Enhance your terminal experience with useful plugins.

a. Install zsh-autosuggestions

This plugin provides command suggestions as you type.

Install via Oh My Zsh:

git clone https://github.com/zsh-users/zsh-autosuggestions ${ZSH_CUSTOM:-~/.oh-my-zsh/custom}/plugins/zsh-autosuggestions

Or install via Homebrew:

brew install zsh-autosuggestions

Add to ~/.zshrc:

plugins=(git rails ruby zsh-autosuggestions)

If installed via Homebrew, add:

source /opt/homebrew/share/zsh-autosuggestions/zsh-autosuggestions.zsh

to the bottom of ~/.zshrc.

Restart iTerm2:

exec zsh

b. Install zsh-syntax-highlighting

This plugin highlights commands to distinguish valid syntax from errors.

Install via Oh My Zsh:

git clone https://github.com/zsh-users/zsh-syntax-highlighting.git ${ZSH_CUSTOM:-~/.oh-my-zsh/custom}/plugins/zsh-syntax-highlighting

Add to .zshrc:

plugins=(git rails ruby zsh-autosuggestions zsh-syntax-highlighting)

Restart iTerm2:

exec zsh

Wrapping Up

Your terminal is now set up for an optimized development experience! With Homebrew, iTerm2, Oh My Zsh, and useful plugins, your workflow will be faster and more efficient.

to be continued …

The Evolution of Asset 📑 Management in Web and Ruby on Rails

Understanding Middleware in Rails

When a client request comes into a Rails application, it doesn’t always go directly to the MVC (Model-View-Controller) layer. Instead, it might first pass through middleware, which handles tasks such as authentication, logging, and static asset management.

Rails uses middleware like ActionDispatch::Static to efficiently serve static assets before they even reach the main application.

ActionDispatch::Static Documentation

“This middleware serves static files from disk, if available. If no file is found, it hands off to the main app.”

Where Are Static Files Stored?

Rails stores static assets in the public/ directory, and ActionDispatch::Static ensures these are served efficiently without hitting the Rails stack.

Core Components of Ruby on Rails – A reminder

To understand asset management evolution, let’s quickly revisit Rails’ core components:

  • ActiveRecord: Object-relational mapping (ORM) system for database interactions.
  • Action Pack: Handles the controller and view layers.
  • Active Support: A collection of utility classes and standard library extensions.
  • Action Mailer: A framework for designing email services.

The Role of Browsers in Asset Management

Web browsers cache static assets to improve performance. The caching strategy varies based on asset types:

  • Images: Rarely change, so they are aggressively cached.
  • JavaScript and CSS files: Frequently updated, requiring cache-busting mechanisms.

The Era of Sprockets

Historically, Rails used Sprockets as its default asset pipeline. Sprockets provided:

  • Conversion of CoffeeScript to JavaScript and SCSS to CSS.
  • Minification and bundling of assets into fewer files.
  • Digest-based caching to ensure updated assets were fetched when changed.

The Rise of JavaScript & The Shift Towards Webpack

The release of ES6 (2015-2016) was a turning point for JavaScript, fueling the rise of Single Page Applications (SPAs). This marked a shift from traditional asset management:

  • Sprockets was effective but became complex and difficult to configure for modern JS frameworks.
  • Projects started including package.json at the root, indicating JavaScript dependency management.
  • Webpack emerged as the go-to tool for handling JavaScript, offering features like tree-shaking, hot module replacement, and modern JavaScript syntax support.

The Landscape in 2024: A More Simplified Approach

Recent advancements in web technology have drastically simplified asset management:

  1. ES6 Native Support in All Major Browsers
    • No need for transpilation of modern JavaScript.
  2. CSS Advancements
    • Features like variables and nesting eliminate the need for preprocessors like SASS.
  3. HTTP/2 and Multiplexing
    • Enables parallel loading of multiple assets over a single connection, reducing dependency on bundling strategies.

Enter Propshaft: The Modern Asset Pipeline

Propshaft is the new asset management solution introduced in Rails, replacing Sprockets for simpler and faster asset handling. Key benefits include:

  • Digest-based file stamping for effective cache busting.
  • Direct and predictable mapping of assets without complex processing.
  • Better integration with HTTP/2 for efficient asset delivery.

Rails 8 Precompile Uses Propshaft

What is Precompile? A Reminder

Precompilation hashes all file names and places them in the public/ folder, making them accessible to the public.

Propshaft improves upon this by creating a manifest file that maps the original filename as a key and the hashed filename as a value. This significantly enhances the developer experience in Rails.

Propshaft ultimately moves asset management in Rails to the next level, making it more efficient and streamlined.

The Future of Asset Management in Rails

With advancements like native ES6 support and CSS improvements, Rails continues evolving to embrace simpler, more efficient asset management strategies. Propshaft, combined with modern browser capabilities, makes asset handling seamless and more performance-oriented.

As the web progresses, we can expect further simplifications in asset pipelines, making Rails applications faster and easier to maintain.

Stay tuned for more innovations in the Rails ecosystem!

Happy Rails Coding! 🚀

Senior-Level Linux Commands Every Backend Engineer Should Know

For a senior backend engineer, Linux commands are more than tools for navigating directories.

They become a production debugging language.

When a Rails application is consuming too much memory, a log contains millions of lines, a deployment introduces unexpected configuration changes, or a background worker suddenly starts failing, knowing how to combine commands such as sed, awk, grep, find, xargs, sort, uniq, cut, tr, jq, and ps can save hours.

The real skill is not memorizing commands. It is understanding how to compose them into pipelines.

command1 | command2 | command3

This article focuses on commands and techniques that become particularly valuable at a senior engineering level.


1. grep – Search With Intent

Most developers know:

grep "ERROR" production.log

But grep becomes much more powerful with regular expressions and recursive searches.

Search recursively

grep -R "ActiveRecord::Deadlocked" log/

Useful when you don’t know which file contains the problem.

Ignore case

grep -Ri "timeout" .

Show line numbers

grep -n "connection refused" production.log

Search multiple patterns

grep -E "ERROR|FATAL|Exception" production.log

Show context around matches

grep -C 5 "NoMethodError" production.log

This is extremely useful for application logs because the surrounding lines often contain request IDs, parameters, stack traces, or timestamps.

When to use

Use grep when your primary operation is:

“Find lines matching this condition.”

2. sed – Stream Editing

sed is one of the most useful Linux commands for manipulating text without opening an editor.

The simplest example:

sed 's/foo/bar/g' file.txt

Replace every foo with bar.

Delete lines

Delete empty lines:

sed '/^$/d' file.txt

Delete lines containing DEBUG:

sed '/DEBUG/d' production.log

Print specific lines

sed -n '100,150p' production.log

This displays lines 100 through 150.

Very useful when investigating a specific portion of a huge log file.

Modify a configuration file

For example:

sed -i 's/RAILS_LOG_LEVEL=info/RAILS_LOG_LEVEL=debug/' .env

-i modifies the file in place.

Be careful with production configuration files. Prefer making a backup when appropriate:

sed -i.bak 's/old_value/new_value/g' config.yml

Advanced use: remove sensitive information

Suppose logs contain email addresses:

User login: john@example.com
User login: alice@example.com

We can mask them:

sed -E 's/[[:alnum:]._%+-]+@[[:alnum:].-]+\.[A-Za-z]{2,}/[REDACTED]/g' app.log

This is useful when sanitizing logs before sharing them.

When to use sed

Think:

“I want to transform or filter text while streaming it.”

3. awk – Lightweight Data Processing

awk is one of the most important commands for senior engineers.

It treats input as structured columns.

Suppose:

101 John 4500
102 Alice 6000
103 Bob 5000

Run:

awk '{print $1, $3}' users.txt

Output:

101 4500
102 6000
103 5000

Filter records

awk '$3 > 5000 {print $1, $2, $3}' users.txt

Now only users earning more than 5000 are printed.

Calculate values

awk '{sum += $3} END {print sum}' users.txt

Calculate the total salary.

Average:

awk '{sum += $3; count++} END {print sum/count}' users.txt

Processing logs

Imagine an Nginx log:

10.0.0.1 GET /users 200
10.0.0.2 GET /users 500
10.0.0.3 GET /products 200
10.0.0.4 GET /users 500

Extract HTTP status:

awk '{print $4}' access.log

Count status codes:

awk '{print $4}' access.log | sort | uniq -c

Result:

2 200
2 500

awk with conditions

awk '$4 >= 500 {print}' access.log

Find server errors.

When to use awk

Think:

“My input has columns/records and I need to filter, transform, aggregate, or calculate something.”

For quick operational data analysis, awk can often replace writing a small script.

4. cut – Extract Columns

For simple column extraction, cut is usually easier than awk.

Example:

cut -d',' -f1 users.csv

Extract the first CSV field.

Multiple fields:

cut -d',' -f1,3 users.csv

Character ranges:

cut -c1-10 file.txt

Use cut when the operation is straightforward.

Use awk when logic becomes conditional or computational.

5. sort + uniq – Finding Patterns

These commands become extremely powerful together.

Suppose you want to find the most common URLs:

awk '{print $7}' access.log |
sort |
uniq -c |
sort -nr

Example:

1500 /api/users
980 /api/orders
450 /health

This is a classic production-analysis pipeline.

Why sort before uniq?

uniq only detects adjacent duplicate lines.

Therefore:

sort file.txt | uniq

is usually required.

6. head and tail – Inspect Large Files Safely

Instead of opening a 10 GB log:

head -n 50 production.log

Last 100 lines:

tail -n 100 production.log

The real power is:

tail -f production.log

Follow new log entries in real time.

For Rails applications this is particularly useful during deployments:

tail -f log/production.log

You can combine it with grep:

tail -f production.log | grep --line-buffered "ERROR"

Now you’re effectively monitoring errors as they occur.

7. find – Locate Files Precisely

Find Ruby files:

find app/ -type f -name "*.rb"

Find files modified recently:

find log/ -type f -mtime -1

Find large files:

find /var/log -type f -size +500M

Find and execute a command:

find tmp/ -type f -name "*.tmp" -delete

Be careful with destructive commands.

A safer approach is:

find tmp/ -type f -name "*.tmp" -print

Inspect the result first.

8. xargs – Turn Output Into Arguments

Suppose:

find tmp/ -type f -name "*.tmp"

returns many files.

You can pass them to another command:

find tmp/ -type f -name "*.tmp" -print0 |
xargs -0 rm

-print0 and -0 are important because filenames can contain spaces or special characters.

Another example:

grep -Rl "TODO" app/ | xargs wc -l

This finds files containing TODO and counts their lines.

9. ps – Understand Running Processes

For a Rails server:

ps aux | grep puma

More useful:

ps aux --sort=-%mem | head

Find processes consuming the most memory.

CPU:

ps aux --sort=-%cpu | head

This can quickly identify runaway workers.

10. top and htop – Live System Diagnosis

top

For an easier interactive interface:

htop

Use these when diagnosing:

  • High CPU
  • Memory pressure
  • Load
  • Runaway processes
  • Number of workers
  • Process states

For application debugging, don’t look only at Rails logs. Always correlate application behavior with OS-level resource usage.

11. df vs du

These commands answer different questions.

Disk filesystem usage

df -h

Answers:

How full is the filesystem?

Directory usage

du -sh log/

Answers:

What is consuming the space?

Find the largest directories:

du -sh * | sort -hr | head

This is extremely useful when a server suddenly reports:

No space left on device

12. lsof – Discover Who Owns a Resource

Find which process is using port 3000:

lsof -i :3000

Find processes using a file:

lsof /var/log/production.log

Find deleted files still consuming disk:

lsof +L1

This last one is particularly valuable.

A process may keep a deleted log file open. du may not show the file anymore, while disk space remains consumed until the process releases it.

13. ss – Network Investigation

Modern Linux systems commonly use ss for socket inspection.

Check listening ports:

ss -lntp

Check established connections:

ss -nt

Find connections to port 5432:

ss -nt | grep ':5432'

This can help investigate:

  • PostgreSQL connection exhaustion
  • Unexpected network connections
  • Services not listening
  • Connection buildup

14. jq – JSON From the Command Line

Modern APIs produce JSON everywhere.

Suppose:

{
"users": [
{"id": 1, "name": "John"},
{"id": 2, "name": "Alice"}
]
}

Extract names:

jq '.users[].name' response.json

Output:

"John"
"Alice"

Transform it:

jq -r '.users[] | "\(.id),\(.name)"' response.json

This becomes especially powerful when debugging APIs:

curl -s https://example.com/api/users |
jq '.users[] | select(.active == true)'

15. curl – API Debugging From the Shell

Instead of immediately reaching for Postman:

curl -i https://example.com/health

POST JSON:

curl -X POST https://example.com/api/users \
-H "Content-Type: application/json" \
-d '{"name":"John"}'

Measure request timing:

curl -o /dev/null -s \
-w 'HTTP: %{http_code}\nTime: %{time_total}s\n' \
https://example.com

This is extremely useful when debugging production APIs.

16. tee – See and Save Output Simultaneously

bundle exec rails db:migrate 2>&1 | tee migration.log

The output is displayed on the terminal while simultaneously being written to a file.

Useful during deployments and troubleshooting.

17. Powerful Pipelines

The real senior-level skill comes from combining commands.

For example, identify the most frequent 500 responses:

grep " 500 " access.log |
awk '{print $7}' |
sort |
uniq -c |
sort -nr |
head -20

Or find the largest log files:

find /var/log -type f -size +100M -print |
xargs -r ls -lh |
sort -k5 -hr

Or monitor Rails errors:

tail -f log/production.log |
grep --line-buffered -E "ERROR|FATAL|Exception"

18. A Practical Senior Engineer Mental Model

Instead of memorizing hundreds of commands, categorize them.

RequirementCommands
Searchgrep, rg
Transform textsed
Process columns/dataawk, cut
Count/group datasort, uniq
Locate filesfind
Connect commandsxargs, pipes
Inspect processesps, top, htop
Inspect disksdf, du
Inspect socketsss, lsof
JSON processingjq
HTTP/API debuggingcurl
Save + display outputtee

The most important progression is:

Basic Linux
Individual commands
Pipelines
Conditional filtering
Aggregation
Production diagnosis

A senior engineer should be comfortable turning an unclear operational question into a shell pipeline.

For example:

“Which API endpoints are causing the most HTTP 500 errors right now?”

Instead of manually opening a log file, you should naturally arrive at something like:

grep " 500 " access.log |
awk '{print $7}' |
sort |
uniq -c |
sort -nr |
head -20

That is the real power of Linux:

small, composable tools solving complex operational problems.

For Rails engineers especially, mastering these commands means you can diagnose the application, process, filesystem, network, and logs from the same shell instead of relying entirely on application-level tooling.

Happy commanding!

Learning C to Understand Ruby – Part 2: Memory, Pointers and the Ruby Object Model

In Part 1, I looked at why learning C can be valuable for a Ruby developer-not to replace Ruby, but to understand what happens underneath it.

This time, we go closer to the machine.

The concepts are simple:

memory, addresses, pointers, stack, heap.

But they completely change the way you think about Ruby objects.


Everything ultimately becomes memory

Consider this Ruby code:

name = "Ruby"

At the Ruby level, we think:

name → "Ruby"

At the machine level, however, something must exist in memory.

There is storage for the string’s data, metadata describing the object, and some mechanism for Ruby to refer to that object.

The exact representation is an implementation detail, but the important idea is:

Ruby objects ultimately have a physical representation in memory.

C lets us see memory directly.


Memory has addresses

Consider:

int number = 42;

The variable has a value:

42

but it also occupies some location in memory.

We can ask C for that location:

printf("%p", (void *)&number);

The & operator means:

Give me the address of number.

You might see something like:

0x7ffee1234abc

The actual address is not important.

The concept is.

Memory
0x7ffee1234abc
[42]

Now we have crossed an important boundary.

We are no longer thinking only about values.

We are thinking about where those values live.


A pointer stores an address

C lets us store that address:

int number = 42;
int *ptr = &number;

Now:

number
[42]
ptr
[address of number]

And:

printf("%d", *ptr);

The * dereferences the pointer.

It means:

Go to the address stored in ptr and access the value there.

So:

*ptr = 100;

changes the original variable:

number = 100

This is one of C’s defining characteristics.

You can explicitly work with addresses and the data behind them.


Ruby references are not C pointers

This is an important distinction.

Ruby variables behave somewhat like references from a conceptual perspective, but Ruby does not expose raw memory addresses and pointer arithmetic in normal Ruby code.

For example:

name = "Ruby"
other = name

You can think:

name
└────→ String object
other
└────→ same String object

But Ruby does not let you simply say:

"Take this address and add 8 bytes."

C does.

That difference is fundamental.

Ruby gives you an object model.

C gives you memory-level primitives from which many such abstractions can be built.


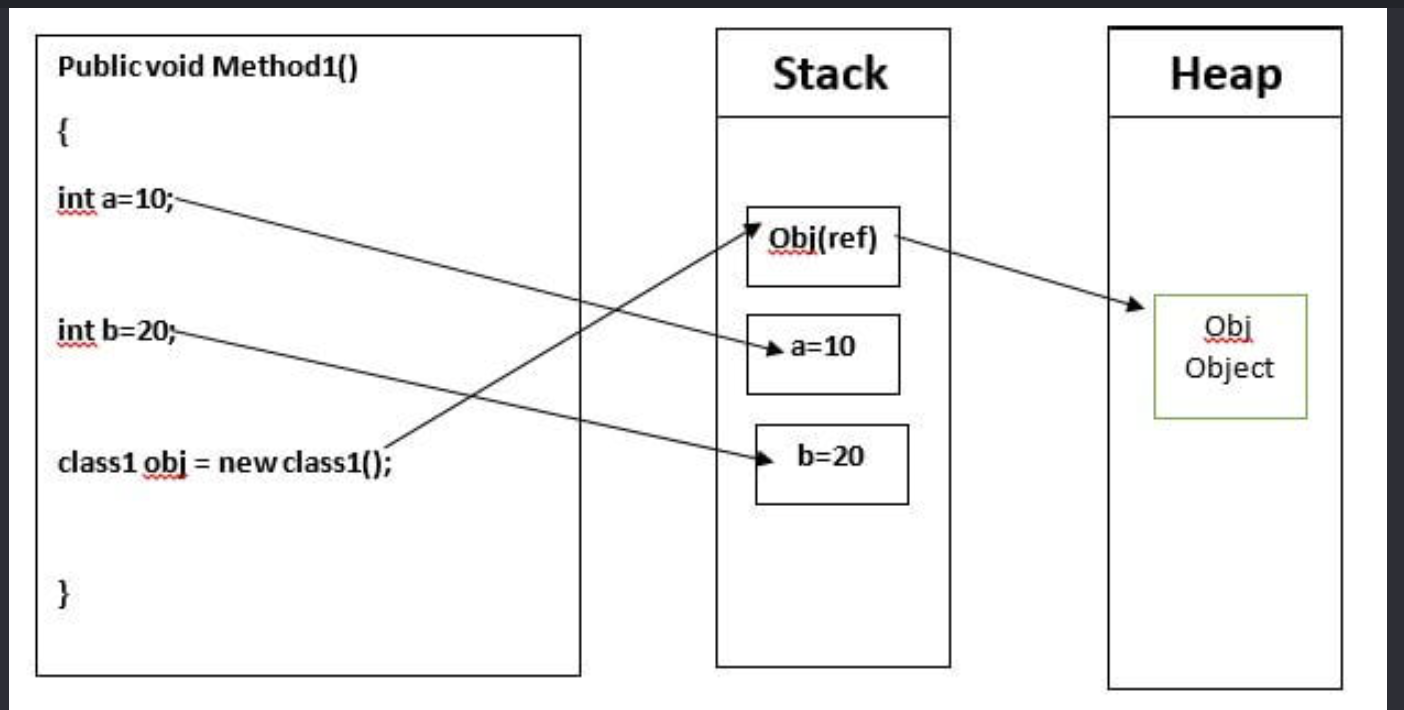
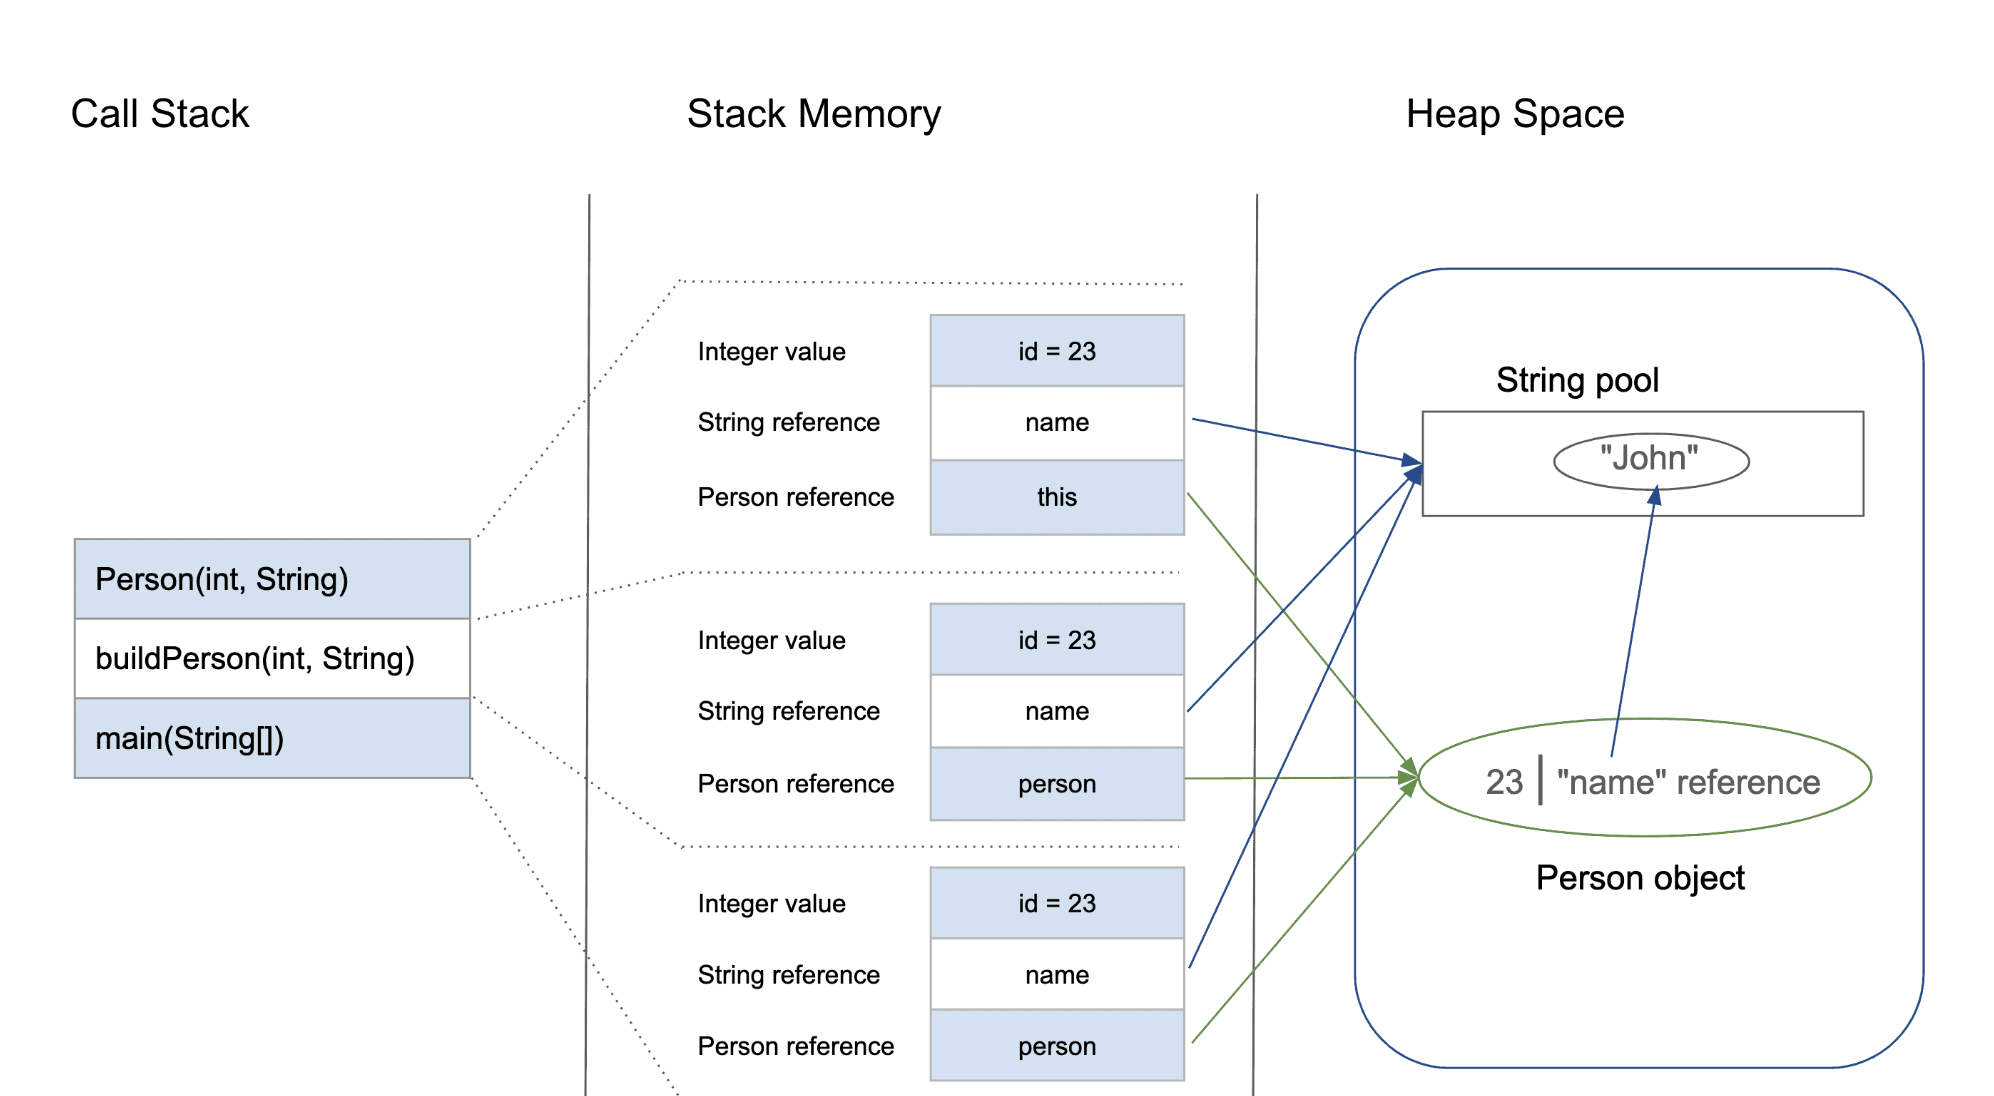
Stack and heap

Now we reach another important concept.

A running program uses memory in different ways. Two areas you’ll encounter immediately are the stack and the heap.

Consider:

void calculate() {
int number = 42;
}

The local variable has automatic storage associated with the function’s execution.

Conceptually:

Stack
calculate()
┌───────────────┐
│ number = 42 │
└───────────────┘

When the function returns, that stack storage is no longer needed.

Dynamic allocation is different:

int *number = malloc(sizeof(int));
*number = 42;

Now memory is allocated dynamically.

Conceptually:

Stack
┌───────────────┐
│ number │──────┐
└───────────────┘ │
Heap
┌────────┐
│ 42 │
└────────┘

And C expects you to eventually release it:

free(number);

This explicit ownership model is one of the biggest differences between C and Ruby.

C always need to know, how large a piece of data is and where do I put it. Everything in C is something like: name + address + value


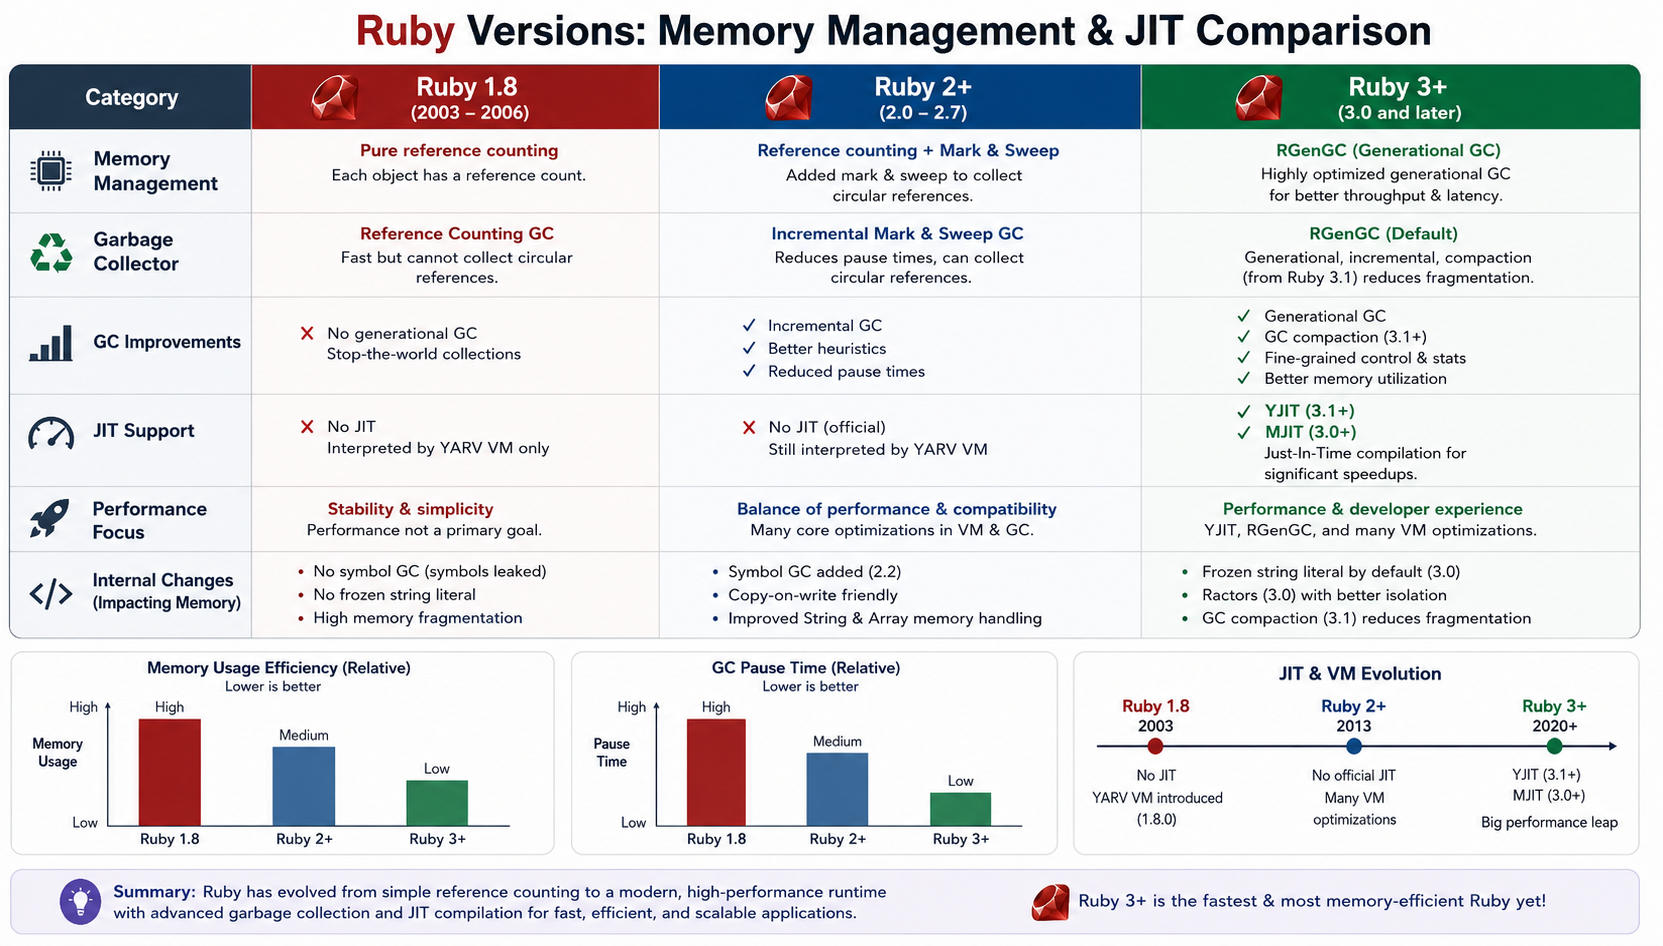
Ruby Memory Management – JIT Comparision

Check: https://docs.ruby-lang.org/en/3.4/yjit/yjit_md.html


Ruby’s heap becomes a much more interesting subject

In Ruby, you normally write:

user = User.new

and never ask:

Who called malloc?
Where exactly is this object?
Who will release its memory?

Ruby’s runtime manages those details.

The object is allocated under Ruby’s memory-management system and the garbage collector tracks object reachability and determines when memory can be reclaimed.

So rather than:

Application → malloc → free

you generally experience:

Ruby code
Ruby runtime
allocation
Ruby heap
GC

Learning C makes that second model much easier to reason about.


The fascinating part: VALUE

Now we arrive at one of the concepts that makes CRuby internals especially interesting.

In CRuby, Ruby values are represented internally using a type called:

VALUE

You will encounter VALUE everywhere when reading the Ruby C implementation and C extension APIs.

Conceptually, you can think of it as:

the low-level representation Ruby uses to pass around Ruby values inside the runtime.

For example, a Ruby C API function may look conceptually like:

VALUE rb_str_new_cstr(const char *ptr);

and C extension methods often receive and return VALUEs.

That means your Ruby object:

"hello"

does not remain some abstract concept all the way down.

CRuby represents it using its internal object/value machinery.


Not every Ruby value is simply a pointer

This is where Ruby becomes particularly interesting.

A common beginner assumption is:

Ruby object = pointer to heap object

That’s useful as a rough mental model, but it isn’t the whole story.

CRuby uses a representation that can encode certain immediate values directly rather than allocating a separate heap object for every value.

Integers are a classic example.

So when you write:

number = 42

you shouldn’t automatically imagine:

number
heap object containing 42

The runtime has specialized representations for some Ruby values.

This is one reason looking at CRuby internals is so educational.

A high-level statement such as:

“Ruby variables point to objects”

is useful, but the implementation is much more nuanced.


Why this matters for a Ruby developer

Let’s take:

a = 10
b = 10

At the Ruby language level, you care that both variables represent the integer 10.

After learning some C and Ruby internals, you start asking different questions:

Are these separate objects?
Is 10 heap allocated?
How does CRuby represent integers?
How does Ruby distinguish integers from ordinary heap objects?
What exactly is stored in VALUE?

Those are much deeper questions.

And they lead directly into:

  • immediate values
  • object flags
  • object headers
  • pointer tagging
  • garbage collection
  • object allocation
  • Ruby’s internal data structures

Pointers explain something else: object identity

Ruby lets us ask:

a = Object.new
b = a
a.equal?(b)
# => true

Why?

Because both variables refer to the same object.

Conceptually:

a ─────┐
[Object]
b ─────┘

C gives you the vocabulary to understand this relationship:

reference
address
pointer
memory location

Again, Ruby intentionally hides the actual pointer from application code.

But the underlying concept of “multiple references to the same object” remains.


The danger of C is also the lesson

Ruby protects you from many classes of memory errors.

In C, you can easily write:

int *ptr = malloc(sizeof(int));
*ptr = 42;
free(ptr);
*ptr = 100;

Now you’re accessing memory after it has been released.

That’s a use-after-free.

You can also leak memory:

int *ptr = malloc(sizeof(int));
/* forgot free(ptr) */

Or write outside an allocated buffer:

int numbers[10];
numbers[100] = 42;

These bugs are difficult precisely because C gives you so much control.

And that is the paradox:

The freedom that makes C powerful is the same freedom that makes it dangerous.

Ruby takes many of these responsibilities away from you.


The real payoff

After learning these concepts, this Ruby code:

users = 10_000.times.map { User.new }

starts looking different.

Instead of only seeing:

Ruby objects

you can begin thinking:

Ruby objects
object representation
memory allocation
references
Ruby heap
garbage collector

And when a Rails application starts consuming hundreds of megabytes of memory, that mental model becomes much more useful.

You can ask better questions.

Not just:

“Why is Rails using so much memory?”

but:

“What objects are being allocated, how long do they remain reachable, and how does Ruby’s allocator and GC interact with that workload?”

That’s a much more senior-level way of investigating the problem.


Where we go next

We have now established the foundation:

C
Memory
Addresses
Pointers
Stack / Heap
Ruby references
VALUE
CRuby object representation

The next step gets even more interesting:

What does a Ruby object actually look like inside CRuby?

We’ll look at concepts such as object headers, RBasic, type information, flags, heap allocation, and how the garbage collector sees Ruby objects.

That’s where the gap between:

User.new

and:

VALUE obj;

starts to disappear.

Happy Learning! 🚀

Learning C to Understand Ruby: A Senior Ruby Developer’s Journey – Part 1

As a Ruby developer, I have spent years enjoying one of Ruby’s biggest strengths: abstraction.

In Rails, I can write:

users = User.where(active: true)

and focus on the business problem rather than memory allocation, pointers, system calls or CPU instructions.

That is exactly why Ruby is productive.

But recently, I started asking a different question:

What is actually happening underneath my Ruby code?

What happens when Ruby creates an object?
Where does that object live?
Who allocates the memory?
Who releases it?
What does an array really look like internally?
What happens when Ruby calls a method?

And that leads to an interesting realization:

Learning C is not necessarily about moving away from Ruby. It can be a way of understanding Ruby at a much deeper level.

This is the first part of that journey.


Ruby hides the machine – intentionally

Consider this:

user = User.new

At the Ruby level, this is trivial.

But conceptually, a lot more is happening.

Ruby needs to:

  1. Represent the object.
  2. Allocate memory for it.
  3. Initialize its internal state.
  4. Keep track of the object for garbage collection.
  5. Maintain references between objects.
  6. Eventually reclaim its memory.

Ruby handles these details for us.

That abstraction is one of the reasons we love Ruby.

But it also means that most Ruby developers don’t need to think about the actual machine.

C removes much of that abstraction.


C forces you to think about memory

In C, you quickly encounter things like:

int number = 42;

and:

int *ptr = &number;

The second line introduces a concept that Ruby normally keeps away from you: the memory address of a value.

You can explicitly allocate memory:

int *numbers = malloc(100 * sizeof(int));

and explicitly release it:

free(numbers);

That changes your mental model.

Instead of thinking only in terms of:

objects
methods
classes

you begin thinking about:

memory
addresses
bytes
layouts
allocation
lifetime
references

And this is extremely useful when trying to understand Ruby internally.


Ruby objects are still data in memory

Take a simple Ruby value:

name = "Abhilash"

As a Ruby developer, you normally think:

name → String

A lower-level mindset makes you ask:

name
  ↓
Ruby value/reference
  ↓
Object representation
  ↓
Memory
  ↓
Bytes

Ruby doesn’t magically escape the laws of computing.

At some point, that string has to exist in memory.

The same is true for:

Array
Hash
Integer
String
User

They all ultimately have machine-level representations.

Learning C helps you become curious about those representations.


Stack vs Heap

One of the first concepts worth learning in C is the difference between stack and heap memory.

For example:

void example() {
    int number = 10;
}

The local variable has automatic storage duration associated with the function’s execution.

Dynamic allocation looks different:

int *number = malloc(sizeof(int));
*number = 10;

free(number);

Now the program explicitly controls the allocation and lifetime.

This distinction is extremely important when later studying Ruby’s memory management.

Ruby objects are managed by the runtime rather than by application code using malloc and free directly.

That leads naturally to the next question:

Who manages Ruby’s heap?

The answer takes us into the Ruby garbage collector.


Garbage collection becomes much easier to understand

A Ruby developer typically learns:

“Ruby has a garbage collector, so I don’t need to manually free objects.”

That’s correct, but incomplete.

Once you understand manual memory management in C, garbage collection becomes much more interesting.

You can start thinking about:

Object allocation
       ↓
Heap
       ↓
References
       ↓
Object becomes unreachable
       ↓
Garbage collector
       ↓
Memory can be reclaimed

Instead of viewing GC as some magical Ruby feature, you begin seeing it as a runtime memory-management strategy.

That distinction is important.

Ruby didn’t eliminate memory management.

It automated memory management.


C also teaches you that data layout matters

Consider:

struct User {
    int id;
    char name[50];
};

You are explicitly describing a data structure’s layout.

You begin thinking about questions such as:

  • How many bytes does this structure occupy?
  • How are fields aligned?
  • Are objects contiguous?
  • How efficiently will the CPU access them?
  • What happens to cache locality?

Ruby normally shields you from these concerns.

But when performance suddenly matters, these concepts become valuable.

For example, processing millions of objects isn’t only about algorithmic complexity.

Memory access patterns can matter too.

This is one reason understanding low-level systems concepts can make you a better high-level developer.


Then there is the most interesting part: Ruby itself uses C

This is where the journey becomes particularly relevant to Ruby developers.

The standard Ruby implementation, CRuby, is largely implemented in C.

That means the language we write:

array.map(&:name)

eventually reaches a runtime implemented at a much lower level.

Conceptually:

Ruby code
   ↓
Ruby parser / VM
   ↓
CRuby runtime
   ↓
Operating system
   ↓
CPU / memory

Once you start reading Ruby’s C source code, concepts that initially look mysterious start becoming understandable:

VALUE
Ruby objects
references
object allocation
method dispatch
garbage collection
VM execution

And suddenly C stops being just another programming language.

It becomes a lens through which you can inspect Ruby itself.


Why should a senior Rails developer care?

You don’t need to write your next Rails application in C.

That isn’t the point.

The goal is to develop a deeper mental model.

When you write:

100_000.times do
User.new
end

you should eventually be able to think beyond the Ruby syntax.

You start wondering:

How many allocations?

Where are those objects stored?

How does GC discover them?

What references exist?

How much memory is being consumed?

What happens when these objects become unreachable?

What is the runtime doing while my Ruby code executes?

Those questions are far more valuable than memorizing another Rails API.


The goal of this journey

My objective isn’t:

“Become a C programmer.”

It is:

Become a Ruby developer who understands what Ruby is doing underneath.

And the roadmap becomes surprisingly clear:

C fundamentals
      ↓
Pointers & memory
      ↓
Stack & heap
      ↓
Processes & system calls
      ↓
C programming at system level
      ↓
CRuby internals
      ↓
Ruby VM
      ↓
Garbage collection
      ↓
Ruby C extensions

The interesting part is that the deeper you go into C, the less mysterious Ruby becomes.

Ruby’s abstractions don’t disappear.

You simply start seeing what is behind them.

And for me, that is the real power of learning C as a Ruby developer.

Part 2 will start with the most important foundation: memory, pointers, stack, heap and how these concepts map to the Ruby object model.

For Part 2, I’d make memory + pointers + stack/heap → Ruby objects. That is where this series can become genuinely fascinating for an experienced Ruby developer.

Happy Learning! 🚀

The Magic of +”” and -“” in Ruby

Demystifying Unary String Operators for Performance and Safety

Ruby is renowned for its developer happiness and elegant syntax. It’s a language where common tasks often read like natural English. However, beneath this friendly surface lie powerful, slightly esoteric features designed for fine-grained control and performance optimization. One such feature – often puzzling to newcomers and occasionally overlooked by seasoned developers – is the use of unary operators on strings: specifically, +”” and -“” .

If you’ve ever dug into the source code of popular Ruby gems like Rails or sidekiq, you might have stumbled across a line like this and paused:

buffer = +""

What exactly is happening here? Why not just write buffer = “” ? Let’s dive into the mechanics, the advantages, and why this tiny symbol makes a significant difference.

The Problem: The Frozen String Literal Pragma

To understand +”” , we first have to understand a major shift in Ruby’s approach to memory management.

Historically, every time you declared a string literal in Ruby, a new object was created in memory. If you had a loop that printed “hello” 1,000 times, Ruby instantiated 1,000 distinct string objects, creating work for the garbage collector.
To combat this, Ruby 2.3 introduced the frozen string literal pragma:

frozen_string_literal: true

When placed at the top of a file, this magic comment instructs Ruby to freeze all string literals in that file. A frozen string cannot be modified. They become constants in memory, drastically reducing object allocations. This is considered a best practice in modern Ruby development.

However, this introduces a new problem. What if you want to build a string dynamically using append operations ( << )?

frozen_string_literal: true
buffer = ""
buffer << "Hello" # => FrozenError (can't modify frozen String)

The Solution: The Unary Plus ( +”” )

Enter the unary + operator. Introduced in Ruby 2.3 alongside the frozen string pragma, + explicitly unfreezes a string literal, returning a mutable copy.

frozen_string_literal: true
buffer = +""
buffer << "Hello "
buffer << "World"
puts buffer # => "Hello World"

In short: +”” says to Ruby, “I know frozen strings are enabled here, but I specifically need this particular string to be mutable because I plan to change it.”

Why is this better than String.new ?

You could achieve the same result using String.new .

buffer = String.new

Functionally, +”” and String.new achieve the same goal. However, +”” is generally preferred in the Ruby community for a few reasons:
* Brevity: It’s significantly shorter and reads more like a literal assignment.
* Idiomatic: It has become the recognized standard idiom in modern Ruby libraries.
* Performance (Micro-optimization): Historically, evaluating the literal +”” was marginally faster than the method dispatch required for String.new , although modern Ruby versions have largely leveled this playing field.

The Counterpart: The Unary Minus ( -“” )

If + unfreezes a string, what does – do? The unary minus does the opposite: it
guarantees a string is frozen and deduplicated.

frozen_string_literal: false (or omitted)
str1 = -"immutable"
str2 = -"immutable"
puts str1.object_id == str2.object_id # => true
str1 << " change" # => FrozenError (can't modify frozen String)

When you use – , Ruby checks an internal “frozestring” table. If a frozen string with the identical content already exists, it returns a reference to that existing object rather than creating a new one. This is equivalent to calling “immutable”.freeze , but it is syntactically cleaner when used inline.

Why Do Developers Miss This?

If these operators are so useful, why aren’t they universally understood?
* It’s visually subtle: The difference between “” and +”” is a single character. It’s easy for the eyes to glide over it during code review or while casually reading a library’s source code.
* It relies on file-level pragmas: If you aren’t in the habit of using #
frozen_string_literal: true
in your projects, you rarely encounter the
FrozenError that necessitates +”” . Many smaller scripts or older legacy
applications run without the pragma, meaning a regular “” works fine as a
mutable buffer.
* It feels “un-Ruby-like”: Ruby is usually explicit and readable (e.g., [1,
2].empty? ). Using arithmetic operators like + and – on strings to control memory allocation feels a bit like C-style pointer manipulation, which breaks the mental model some developers have of the language.

Best Practices & Takeaways

To write modern, performant, and safe Ruby code, adopt these habits:
* Always freeze by default: Add # frozen_string_literal: true to the top of all new Ruby files. It’s an easy win for memory efficiency.
* Use +”” for buffers: When you need to incrementally build a string using << ,
initialize it with +”” .
* Avoid += in loops: Building strings with += creates a new object on every iteration, regardless of pragmas. Always prefer appending to a mutable buffer with << .

BAD (Creates 1001 string objects)
frozen_string_literal: true
result = +""
1000.times { result += "a" }
GOOD (Creates 1 mutable string object and modifies it in place)
frozen_string_literal: true
result = +""
1000.times { result << "a" }

The unary operators + and – on strings are small, esoteric features that pack a
significant punch. Understanding them not only helps you write better code but also enables you to read and understand the source code of the Ruby ecosystem’s most robust libraries.

Files

Download PDF:

Happy Rubying!

Learn SQL: Day 7 – Query Optimization Workshop

Welcome to Day 7.

Everything we’ve learned so far leads to this lesson.

Until now, you’ve learned:

  • How to write SQL
  • How JOINs work
  • How GROUP BY works
  • How indexes work
  • How PostgreSQL chooses execution plans

Today, we’ll combine everything to solve real-world performance problems.


Today’s Goals

By the end of today, you’ll be able to answer questions like:

  • Why is this query slow?
  • Should I add an index?
  • Should I rewrite the query?
  • Is this a database problem or an application problem?
  • How would I debug this in production?

These are exactly the kinds of discussions that happen in senior Rails interviews.


A Senior Engineer’s Workflow

Suppose your manager says:

“The Users page takes 8 seconds to load.”

A junior developer might immediately say:

“Let’s add an index.”

A senior developer thinks:

1. Is the query actually slow?
2. Which query is slow?
3. How much data is involved?
4. What is PostgreSQL doing?
5. Can I rewrite the query?
6. Do I need an index?
7. Is the application causing the problem?

Notice:

Adding an index is Step 6, not Step 1.

Our Practice Schema

Let’s build something closer to a real Rails application.

DROP TABLE IF EXISTS order_items;
DROP TABLE IF EXISTS orders;
DROP TABLE IF EXISTS products;
DROP TABLE IF EXISTS users;

Users

CREATE TABLE users (
    id BIGSERIAL PRIMARY KEY,
    name TEXT,
    email TEXT,
    city TEXT
);

Products

CREATE TABLE products (
    id BIGSERIAL PRIMARY KEY,
    name TEXT,
    price NUMERIC(10,2),
    category TEXT
);

Orders

CREATE TABLE orders (
    id BIGSERIAL PRIMARY KEY,
    user_id BIGINT NOT NULL REFERENCES users(id),
    status TEXT,
    created_at TIMESTAMP DEFAULT NOW()
);

Order Items

CREATE TABLE order_items (
    id BIGSERIAL PRIMARY KEY,
    order_id BIGINT NOT NULL REFERENCES orders(id),
    product_id BIGINT NOT NULL REFERENCES products(id),
    quantity INTEGER,
    price NUMERIC(10,2)
);


The Six-Step Performance Checklist

Every slow query investigation should start with this checklist.

Step 1 – Measure

Never optimise blindly.

Run:

EXPLAIN ANALYZE
SELECT ...

Step 2 – Understand the Business Question

Example:

Show the last 20 completed orders.

Don’t optimise before understanding what the query should do.

Step 3 – Read the Plan

Look for:

  • Seq Scan
  • Nested Loop
  • Hash Join
  • Sort
  • Aggregate
  • Bitmap Heap Scan

Step 4 – Find the Bottleneck

Ask:

  • Which node took the most time?
  • Which node processed the most rows?

Step 5 – Decide the Fix

Possible fixes:

  • Better index
  • Better SQL
  • Better schema
  • Better ActiveRecord
  • Better pagination

Step 6 – Measure Again

Never assume the optimisation worked.

Always compare before and after.


Scenario 1 – Missing Index

Query:

SELECT *
FROM users
WHERE email='john@example.com';

Execution plan:

Seq Scan
rows=100000
actual rows=1

Question:

What’s wrong?

Diagnosis

No index on email.

Fix

CREATE INDEX idx_users_email
ON users(email);

Run again:

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE email='john@example.com';

Expect:

Index Scan

Scenario 2 – Wrong Index

Suppose the application runs:

SELECT *
FROM users
WHERE city='Chicago'
AND age=30;

Indexes:

(city)
(age)

Question:

Better solution?

Answer

Composite index:

CREATE INDEX idx_city_age
ON users(city, age);

Because the application almost always filters by both.


Scenario 3 – Sorting

Query:

SELECT *
FROM orders
ORDER BY created_at DESC
LIMIT 20;

Plan:

Seq Scan
Sort
Limit

Question:

Can we avoid sorting?

Solution

CREATE INDEX idx_orders_created_at_desc
ON orders(created_at DESC);

Now PostgreSQL can read the index in order.

Often:

Index Scan
Limit

No Sort node.


Scenario 4 – N+1 Queries

Rails code:

orders = Order.limit(100)

orders.each do |order|
  puts order.user.name
end

SQL executed:

SELECT * FROM orders LIMIT 100;

Then:

SELECT * FROM users WHERE id=1;

SELECT * FROM users WHERE id=2;

100 additional queries.

Total

101 queries

Fix

Order.includes(:user)

Now:

SELECT * FROM orders;
SELECT *
FROM users
WHERE id IN (...);

Two queries.

Interview Question

Which is faster?

includes

or

joins

Answer:

They solve different problems.


Scenario 5 – OFFSET Pagination

Query:

SELECT *
FROM orders
ORDER BY created_at DESC
LIMIT 20
OFFSET 100000;

Looks harmless.

But PostgreSQL must skip:

100000 rows

before returning:

20 rows

Large OFFSET values become increasingly expensive.

Better Solution

Keyset Pagination.

Instead of:

OFFSET 100000

Use:

WHERE created_at < '2026-07-01'
ORDER BY created_at DESC
LIMIT 20;

This lets PostgreSQL continue from the last seen row instead of counting through earlier rows.

Rails Example

Instead of:

Order.order(created_at: :desc)
     .offset(100000)
     .limit(20)

Use:

Order
  .where("created_at < ?", last_created_at)
  .order(created_at: :desc)
  .limit(20)

This is called keyset pagination or cursor pagination.


Scenario 6 – SELECT *

Query:

SELECT *
FROM users;

Returns:

id
name
email
city
address
bio
avatar
...

Suppose the page only displays:

  • name
  • city

Why fetch everything?

Better:

SELECT
name,
city
FROM users;

Rails:

User.select(:name, :city)

Scenario 7 – COUNT(*)

Suppose:

SELECT COUNT(*)
FROM orders;

On:

300 million rows

Question:

Can this be slow?

Yes.

Because PostgreSQL must count visible rows.

Unlike some databases, PostgreSQL generally doesn’t maintain an exact row count that’s instantly available for arbitrary COUNT(*).


Scenario 8 – DISTINCT

Query:

SELECT DISTINCT users.*
FROM users
JOIN orders
ON users.id=orders.user_id;

Question:

Why is DISTINCT needed?

Because JOIN duplicates users.

Could EXISTS express the requirement more directly?

SELECT *
FROM users u
WHERE EXISTS (
SELECT 1
FROM orders o
WHERE o.user_id=u.id
);

Sometimes that’s clearer.


Scenario 9 – Functions in WHERE

Query:

SELECT *
FROM users
WHERE LOWER(email)='john@example.com';

Normal email index?

Not useful.

Solution:

CREATE INDEX idx_lower_email
ON users(LOWER(email));

Expression index.


Scenario 10 – Too Many Indexes

Suppose:

users
12 indexes

Problem?

Every INSERT must update:

Table
+
12 indexes

Indexes speed reads but slow writes.

Always consider the workload.


Optimization Decision Tree

When a query is slow, ask:

Is PostgreSQL scanning too many rows?
Yes
Would an index help?
Yes
Do I already have one?
No
Create the correct index.

But also ask:

Am I returning unnecessary data?
Am I sorting unnecessarily?
Am I joining unnecessarily?
Am I executing the query too many times?

Real Rails Optimization Example

Suppose this page loads slowly:

@orders = Order
            .where(status: "completed")
            .order(created_at: :desc)
            .limit(20)

Questions:

  1. Is there an index on status?
  2. Is there an index on created_at?
  3. Would a composite index help?

Potential solution:

CREATE INDEX idx_orders_status_created_at
ON orders(status, created_at DESC);

Why?

Because the query filters by status and orders by created_at.


Senior Interview Exercise

Suppose you see:

SELECT *
FROM orders
WHERE user_id = 100
ORDER BY created_at DESC
LIMIT 20;

Which index would you create?

Many people answer:

(user_id)
(created_at)

A stronger answer is:

CREATE INDEX idx_orders_user_created
ON orders(user_id, created_at DESC);

Because it supports both the filter and the ordering in one index.


Common Performance Mistakes

Mistake 1

Adding indexes without measuring.

Mistake 2

Using SELECT * everywhere.

Mistake 3

Ignoring N+1 queries.

Mistake 4

Using huge OFFSET values.

Mistake 5

Creating duplicate indexes.

Mistake 6

Ignoring EXPLAIN ANALYZE.

Senior-Level Mental Model

Every query has a “cost.”

The cost comes from:

Rows read
+
Rows sorted
+
Rows joined
+
Rows transferred
+
Application round trips

The goal of optimisation is to reduce one or more of these.


Practical Exercises

Exercise 1

Create:

CREATE INDEX idx_orders_user_created
ON orders(user_id, created_at DESC);

Run:

EXPLAIN ANALYZE
SELECT *
FROM orders
WHERE user_id=1
ORDER BY created_at DESC
LIMIT 20;

Observe whether PostgreSQL can avoid an explicit Sort.

Exercise 2

Compare:

SELECT *
FROM users;

with:

SELECT name, city
FROM users;

Think about the amount of data returned.

Exercise 3

Write three versions of:

“Find users with completed orders.”

Using:

  1. JOIN
  2. EXISTS
  3. IN

Then compare their execution plans.

Exercise 4

Find a query that performs a Seq Scan.

Add an appropriate index.

Run EXPLAIN ANALYZE again.

What changed?


Interview Case Study

Imagine you’re in a senior Rails interview.

The interviewer says:

“A customer reports that the Orders page takes 6 seconds to load.”

A strong answer isn’t:

“I’ll add an index.”

A stronger answer is:

  1. Reproduce the issue.
  2. Identify the SQL generated by ActiveRecord.
  3. Run EXPLAIN ANALYZE.
  4. Inspect scan types, joins, and sort operations.
  5. Check existing indexes.
  6. Decide whether the fix belongs in the SQL, indexes, ActiveRecord code, or schema.
  7. Measure again after the change.

That systematic approach demonstrates senior-level thinking.


Homework

Build a small benchmark using your practice schema.

  1. Populate:
    • 100,000 users
    • 500,000 orders
  2. Measure these queries before and after adding indexes:
    • Find a user by email.
    • Find recent orders for a user.
    • Find completed orders.
    • Find users with no orders.
  3. For each query, record:
    • Execution plan
    • Execution time
    • Scan type
    • Rows estimated
    • Rows returned
  4. Explain why PostgreSQL chose each plan.

What’s Next?

At this point, you’re already covering topics that many experienced Rails developers never study in depth.

For Day 8, I recommend Window Functions:

  • ROW_NUMBER()
  • RANK()
  • DENSE_RANK()
  • LAG()
  • LEAD()
  • Running totals
  • Moving averages
  • Top N per group

Window functions are common in reporting, analytics, and senior backend interviews because they solve problems that are difficult or inefficient with plain GROUP BY. Understanding them will significantly broaden your SQL toolkit.

Happy Learning! 🚀

Learn SQL: Day 6C – Mastering EXPLAIN ANALYZE (Think Like the PostgreSQL Query Planner)

Welcome to Day 6C.

This is one of the most valuable lessons in the entire course.

Many developers know how to write SQL.

Very few can answer questions like:

“Why is this query slow?”

or

“Why did PostgreSQL choose a Bitmap Heap Scan instead of an Index Scan?”

or

“What would you optimize first?”

This lesson will teach you exactly that.

Today’s Goal

By the end of today, you should be able to:

  • Read an EXPLAIN ANALYZE plan from top to bottom
  • Understand every important field
  • Explain why PostgreSQL chose a plan
  • Identify bottlenecks
  • Suggest optimizations
  • Discuss execution plans confidently in a senior interview

First, Understand What EXPLAIN ANALYZE Actually Does

Consider this query:

SELECT *
FROM users
WHERE email = 'user50000@example.com';

Without EXPLAIN, PostgreSQL simply returns the result.

With:

EXPLAIN
SELECT *
FROM users
WHERE email = 'user50000@example.com';

PostgreSQL says:

“Here’s the plan I intend to use.”

With:

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE email = 'user50000@example.com';

PostgreSQL actually executes the query and says:

“Here’s what really happened.”

The Query Planner

Imagine PostgreSQL as a GPS.

You ask:

Go from A to B.

The GPS considers:

  • Highway
  • Local roads
  • Toll roads
  • Traffic

Then chooses the cheapest route.

PostgreSQL does exactly the same.

It considers:

  • Sequential Scan
  • Index Scan
  • Bitmap Scan
  • Hash Join
  • Nested Loop
  • Merge Join

and chooses what it estimates to be the cheapest plan.

Our Practice Table

Use the same table from Day 6B.

users

100,000 rows.

Our First Plan

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE email='user50000@example.com';

You might see something similar to:

Index Scan using idx_users_email on users
(cost=0.42..8.44 rows=1 width=51)
(actual time=0.030..0.032 rows=1 loops=1)

Let’s decode every part.


Part 1 – Scan Type

First line:

Index Scan

This answers:

How did PostgreSQL access the table?

Possible answers:

  • Seq Scan
  • Index Scan
  • Index Only Scan
  • Bitmap Heap Scan

The scan type is the first thing you should notice.


Part 2 – Using Which Index?

using idx_users_email

PostgreSQL tells you exactly which index it used.

If you expected:

idx_users_city

but it chose:

idx_users_age

you should ask yourself why.


Part 3 – Cost

Example:

cost=0.42..8.44

Many beginners think:

“8.44 milliseconds.”

No.

Cost is not time.

It is PostgreSQL’s internal scoring system.

Think of it like this:

Plan A
Cost = 150
Plan B
Cost = 70

PostgreSQL chooses Plan B.

Startup Cost

First number:

0.42

Cost before the first row can be returned.

Total Cost

Second number:

8.44

Cost to return every row.


Part 4 – Rows

rows=1

Planner estimate.

Meaning:

"I think this query will return
1 row."

Part 5 – Width

width=51

Estimated average size of one returned row.

Used internally for memory and I/O estimates.


Part 6 – Actual Time

actual time=0.030..0.032

Meaning:

First row
0.030 ms

Entire query finished:

0.032 ms

Part 7 – Actual Rows

actual rows=1

Excellent.

Planner guessed:

1

Reality:

1

Very accurate.


Part 8 – Loops

loops=1

This operation executed once.

You’ll later see plans like:

loops=100000

That often indicates an expensive nested loop.


Reading Plans from Bottom to Top

This surprises many developers.

Execution plans are printed like a tree.

Example:

Limit
Sort
Index Scan

Although Limit appears first, execution begins at the bottom.

Conceptually:

Index Scan
Sort
Limit

Think of a factory:

Raw Material
Machine 1
Machine 2
Finished Product

The raw material starts at the bottom.


Example 2 – Sequential Scan

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE city='Chicago';

Output:

Seq Scan on users
(cost=0.00..2332.00 rows=24780 width=51)
(actual time=0.08..21.10 rows=25000 loops=1)

Let’s interpret it.

Why Seq Scan?

Question:

How many rows match?

25,000

That’s:

25%

of the table.

Using the index might require:

  • index lookup
  • 25,000 table lookups

Sequential Scan may simply be cheaper.

Interview Question

If PostgreSQL ignores your index,

does that mean

the index is useless?

Answer:

Absolutely not.

It means PostgreSQL estimated another plan to be cheaper for that specific query.


Example 3 – Bitmap Heap Scan

Suppose you create:

CREATE INDEX idx_users_city
ON users(city);

Now:

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE city='Chicago';

Output:

Bitmap Heap Scan
Bitmap Index Scan

Notice there are two nodes.

Bitmap Index Scan

First:

Read the index.

Chicago
Rows
4
8
12
...

Bitmap Heap Scan

Then:

Visit the table efficiently.

Instead of:

Index
Table
Index
Table

It does:

Index
Collect row locations
Read pages together

Excellent for medium-sized result sets.

Visual

Bitmap Index Scan
Matching Row IDs
Bitmap Heap Scan
Actual Rows

Example 4 – Index Only Scan

Suppose:

SELECT email
FROM users
WHERE email='user100@example.com';

Plan:

Index Only Scan

Question:

Why is this faster?

Answer:

Because PostgreSQL answered the query using only the index.

No table lookup.

Planning Time vs Execution Time

Example:

Planning Time: 0.2 ms
Execution Time: 0.3 ms

Planning:

Choosing the route.

Execution:

Driving the route.

Why Estimates Matter

Suppose:

Planner:

rows=5

Reality:

actual rows=50000

Huge difference.

The planner may choose a terrible plan because its estimate was wrong.

This usually indicates stale statistics.

ANALYZE

Run:

ANALYZE users;

PostgreSQL updates statistics.

The planner now has better information.

VACUUM ANALYZE

Often you’ll see:

VACUUM ANALYZE users;

It does two things:

  • Cleans dead tuples
  • Updates statistics

We’ll study MVCC later.

The Most Common Plan Nodes

These are the ones you should know well for interviews.

Seq Scan

Reads every row.

Think:

Read entire book.

Index Scan

Uses an index.

Think:

Use the book's index.

Index Only Scan

Never touches the table.

Think:

Everything I need is already in the index.

Bitmap Index Scan

Collect matching row locations.

Bitmap Heap Scan

Fetch those rows efficiently.

Sort

ORDER BY

often produces:

Sort

Sorting millions of rows can be expensive.

Aggregate

Produced by:

COUNT()
SUM()
AVG()
GROUP BY

Hash Join

Often used for joins.

We’ll study joins from PostgreSQL’s perspective soon.

Nested Loop

Good when:

One side is tiny.

Terrible when:

Both sides are huge.

Limit

Produced by:

LIMIT 10

Real Example

SELECT *
FROM users
ORDER BY created_at DESC
LIMIT 10;

Possible plan:

Limit
Sort
Seq Scan

Question:

Can we improve it?

Yes.

Index:

CREATE INDEX idx_created_at
ON users(created_at DESC);

Now PostgreSQL may avoid sorting completely.

Buffers (Advanced)

Sometimes you’ll see:

Buffers:
shared hit=500
read=2

Meaning:

Most pages were already in memory.

We’ll study this later.

Parallel Query

Sometimes:

Gather
Parallel Seq Scan

PostgreSQL used multiple CPU workers.

Very common for huge tables.

How to Read Any Plan

I use this checklist.

Step 1

What is the scan type?

Step 2

Which index?

Step 3

Estimated rows?

Step 4

Actual rows?

Step 5

Huge mismatch?

If yes,

statistics may be wrong.

Step 6

Planning vs execution time.

Step 7

Which operation consumed most of the cost?


Real Interview Example

Interviewer shows:

Seq Scan
rows=100000
actual rows=1

Question:

Would you optimize?

Yes.

Probably missing an index.

Another example:

Index Scan
rows=90000

Question:

Should PostgreSQL maybe use Seq Scan?

Possibly.

Need to inspect the query.


Common Mistakes

Mistake 1

Thinking cost is milliseconds.

Wrong.

Mistake 2

Looking only at execution time.

Also inspect:

  • estimated rows
  • actual rows

Mistake 3

Ignoring scan type.

Always notice:

Seq
Index
Bitmap
Index Only

Mistake 4

Assuming an index must always be used.

False.

Senior-Level Interview Questions

Q1

Difference:

EXPLAIN
EXPLAIN ANALYZE

Q2

Why can PostgreSQL ignore an index?

Q3

What does

rows

mean?

Q4

Difference between

rows
actual rows

Q5

What is

loops

?

Q6

Difference between

Index Scan
Index Only Scan

Q7

Why is Bitmap Heap Scan useful?

Q8

Why isn’t cost measured in milliseconds?

Q9

How do stale statistics affect query plans?

Q10

Why should you run

ANALYZE

after major data changes?


Practical Exercises

Exercise 1

Run:

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE email='user50000@example.com';

Write down:

  • Scan type
  • Estimated rows
  • Actual rows
  • Execution time

Exercise 2

Run:

EXPLAIN ANALYZE
SELECT *
FROM users
WHERE city='Chicago';

Explain why PostgreSQL chose that plan.

Exercise 3

Run:

EXPLAIN ANALYZE
SELECT *
FROM users
ORDER BY created_at DESC
LIMIT 10;

Then create an index:

CREATE INDEX idx_users_created_at_desc
ON users(created_at DESC);

Run the query again and compare the plans.

Exercise 4

Run:

ANALYZE users;

Then compare the estimated rows with the actual rows again.


Senior Rails Interview Tips

If an interviewer gives you an execution plan, don’t immediately suggest adding an index.

Instead, ask:

  1. How many rows are in the table?
  2. How many rows does this query return?
  3. What indexes already exist?
  4. Is the planner’s estimate accurate?
  5. Is the query actually slow?

That line of reasoning demonstrates experience much better than jumping straight to “add an index.”


What’s Next?

From here, I recommend Day 7: Query Optimization Workshop.

Unlike the previous lessons, it won’t introduce many new SQL keywords. Instead, we’ll work through real production-style problems, such as:

  • A query that takes 8 seconds—how do we optimize it?
  • Why did PostgreSQL choose a Nested Loop instead of a Hash Join?
  • N+1 queries in Rails and how to eliminate them.
  • OFFSET pagination vs keyset pagination.
  • Rewriting slow SQL into faster SQL.
  • Using indexes effectively rather than adding them blindly.

This is the stage where you’ll start thinking like a senior backend engineer rather than someone who simply knows SQL syntax.

Happy Learning! 🚀